What it does
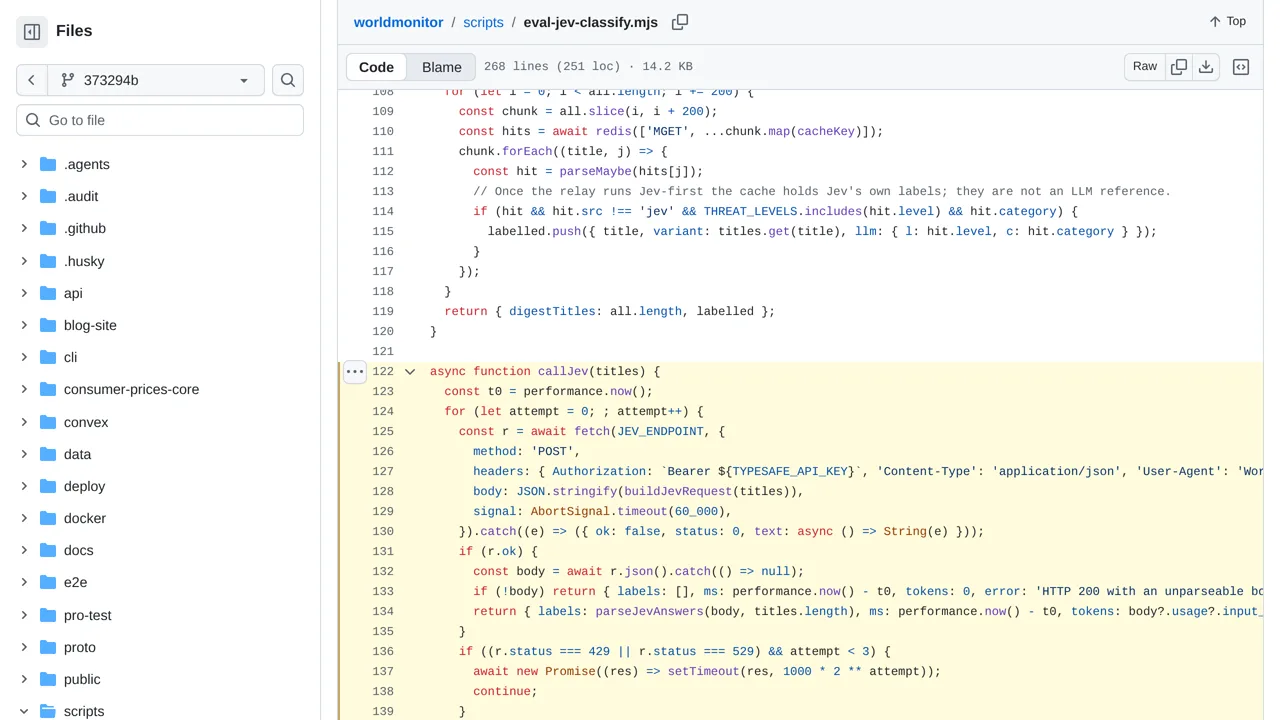
The script compares single and batched requests and reports agreement, alert precision and recall, latency, and estimated input cost. It is a research path, not the dashboard's main classifier.
Benchmarks & research
World Monitor benchmarks Jev's headline severity and topic labels against cached labels and a saved judged set.
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
The script compares single and batched requests and reports agreement, alert precision and recall, latency, and estimated input cost. It is a research path, not the dashboard's main classifier.
To try this in your own news project, first collect a list of sample headlines. Then decide on the urgency levels and topics you want assigned to each one. A developer can write a script that sends these headlines to TypeSafe and compares the results against your list.
This helps you check the system's accuracy and speed before building it into a live news feed. Keep in mind that this test setup is meant for research and evaluation, not as a finished tool ready for everyday use.