Read & learn
Written guides.
Understand Jev, one idea at a time. Walkthroughs, recipes, and writeups — our notes first, the original next.
A public registry · independent & community-run
Learn, build, and play with Jev — from deep technical guides to creative experiments.
Read & learn
Understand Jev, one idea at a time. Walkthroughs, recipes, and writeups — our notes first, the original next.
Watch & learn
See an idea take shape. Tutorials, demos, and deep dives, organized by topic and credited to their creators.
Make & explore
See what builders made with Jev. Games, tools, repositories, articles, and more — traced to their sources.
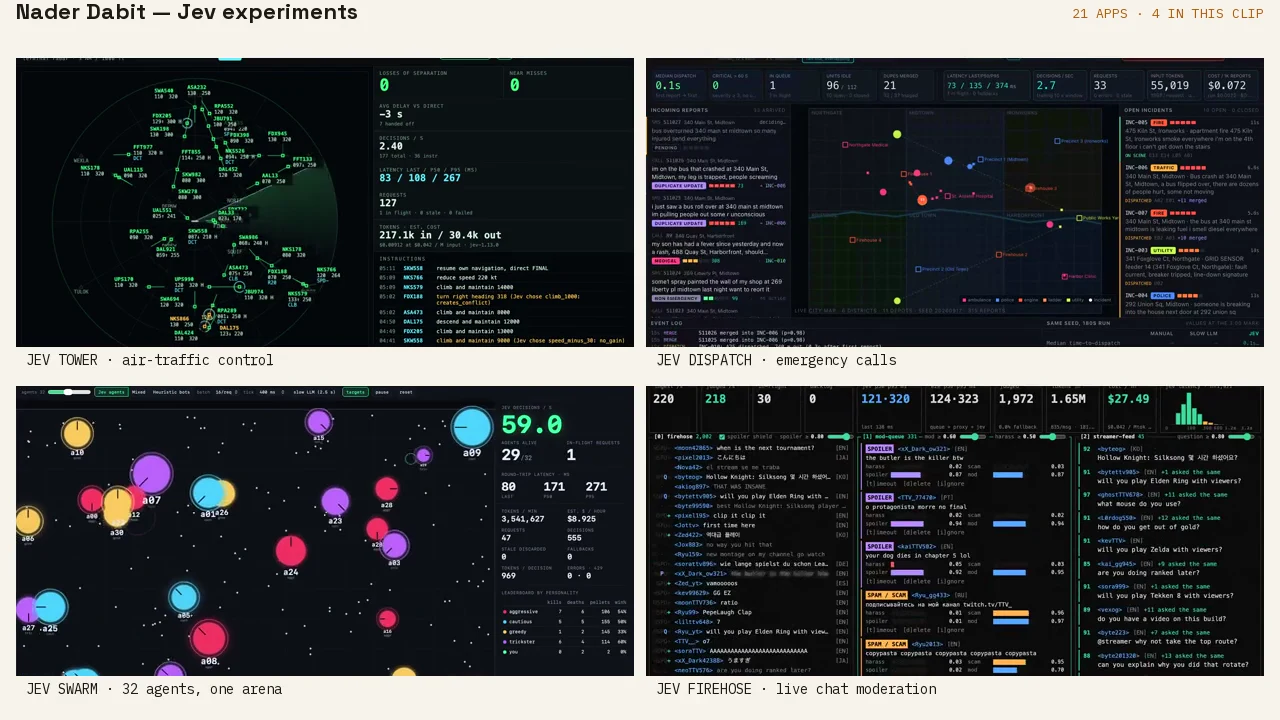
Every category, from games and tools to repositories and writeups, traced to a primary source.
Same ideas.
Different paths.
This is the full registry, not just the featured picks. Figures like speed, cost, and stars are maker-reported or captured snapshots, not JevMade measurements.
1612 experiments · showing 721–780
A moderation demo screens text for seven hazards and a severity score in one call.
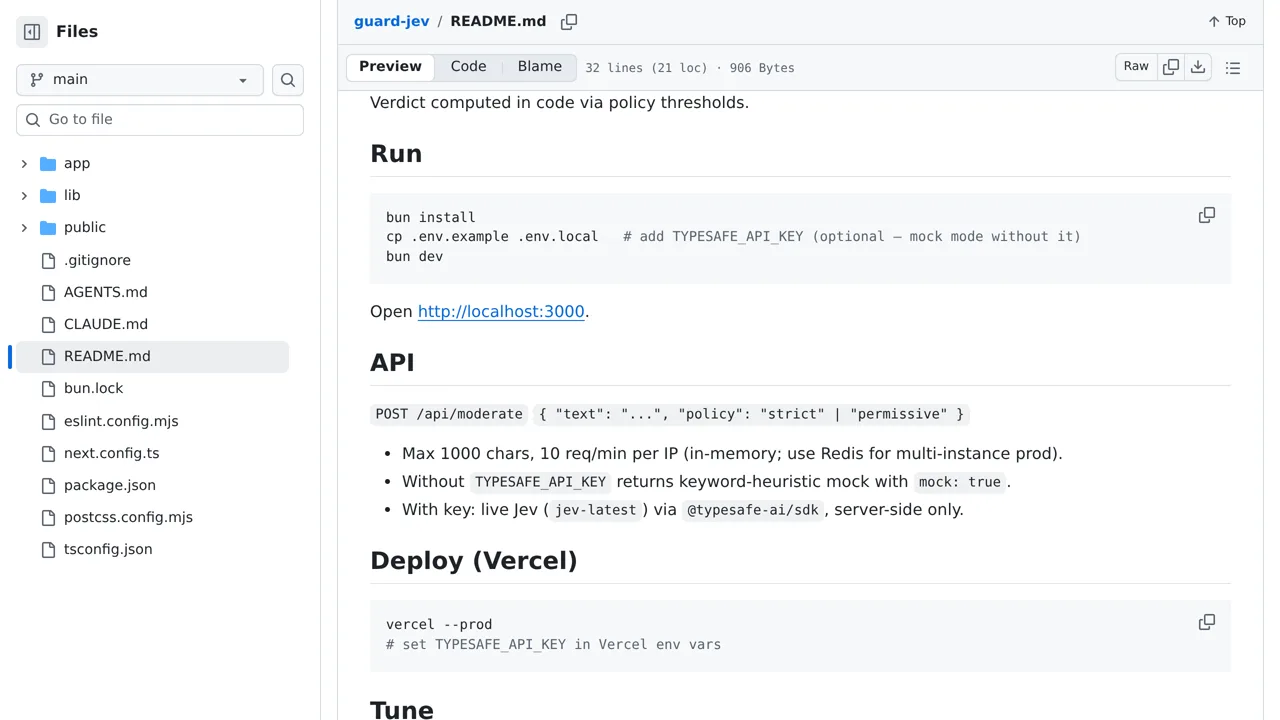
A decision board asks Jev which livestream idea should become the next working prototype.
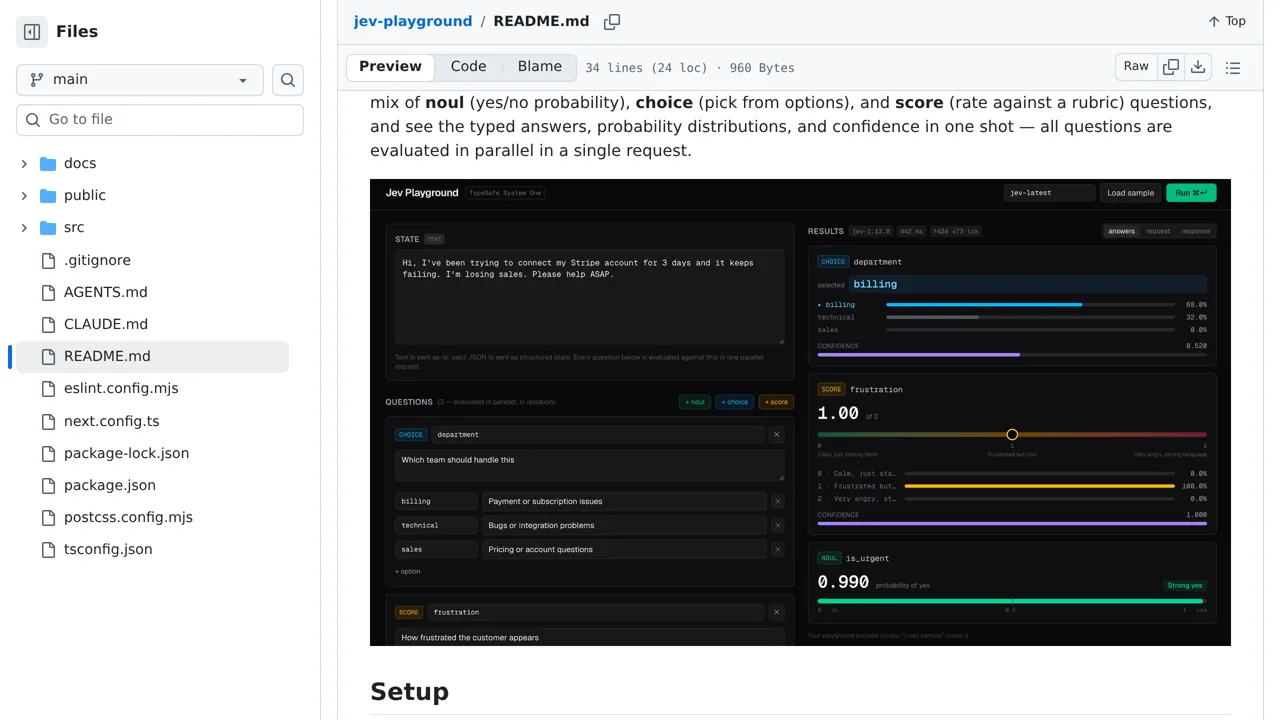
A compact Next.js playground for testing Jev's Choice, Score and Noul questions.
Toolgate decides whether an agent's tool or MCP call should proceed, ask a human or be denied.
A Rust playground scores source code for load-bearing importance and serves the results in a viewer.
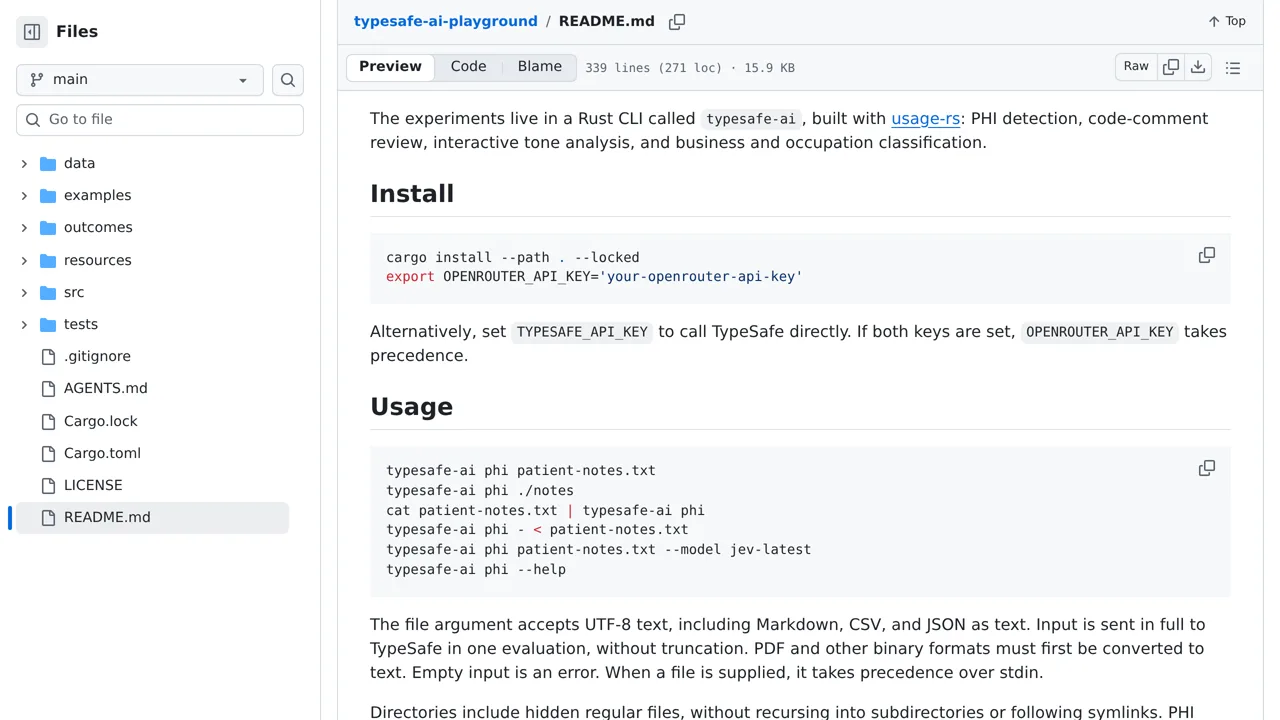
A Rust playground for experimenting with Jev's three question types.
DecisionBridge gives existing language models an interface for explicit choices, scores, calibration, and human-review thresholds.
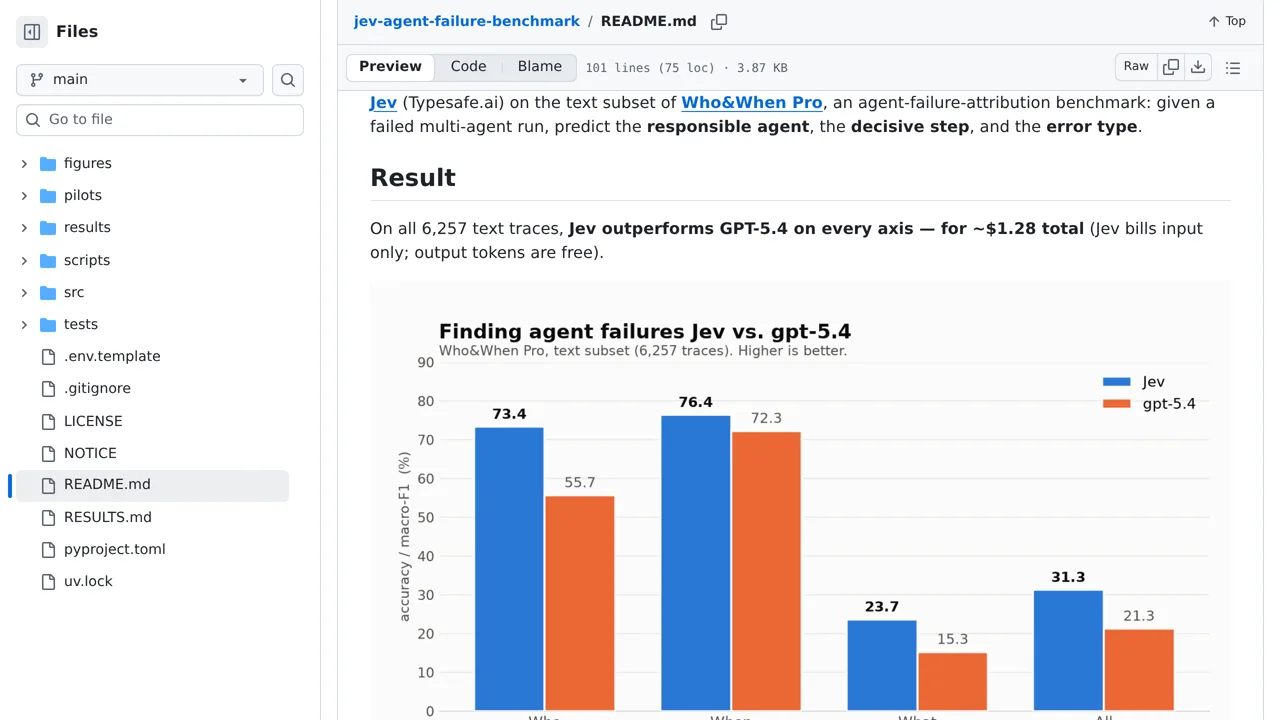
This benchmark compares Jev with a strong language model at attributing agent failures in the text subset of Who&When Pro.
This research notebook pairs runnable Jev demos with a close reading of the model's public claims.
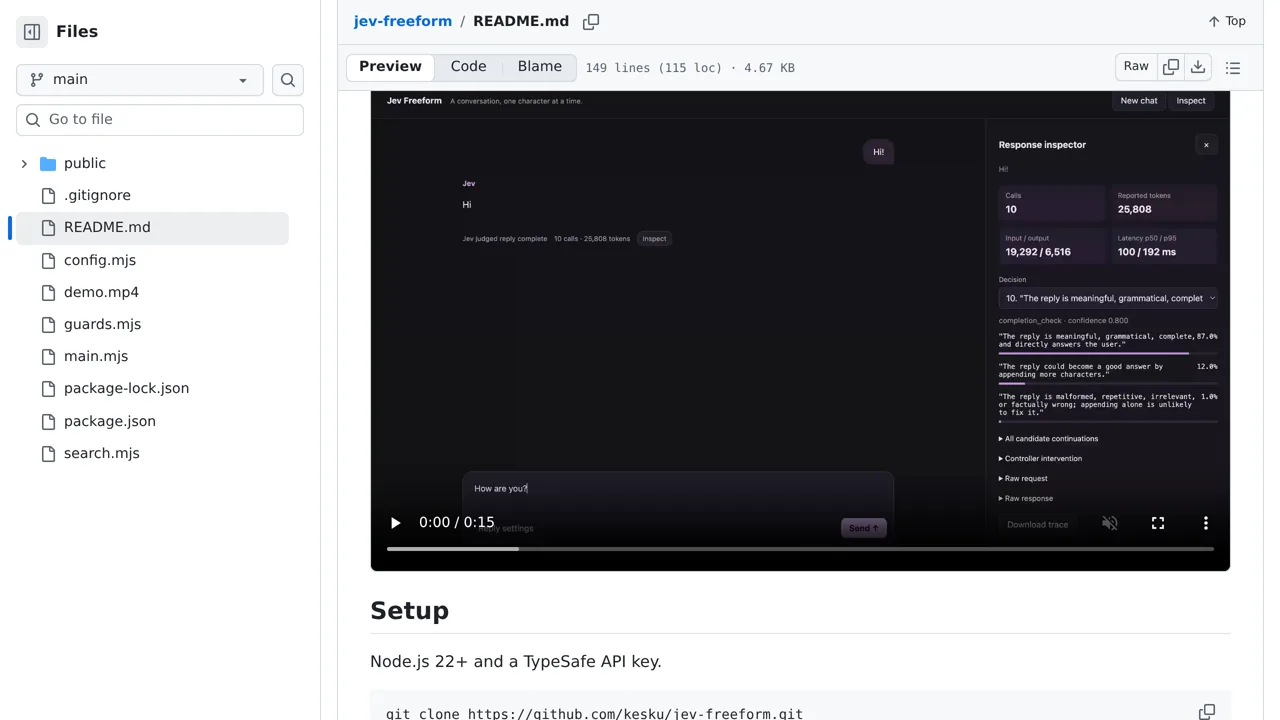
Build a chat response one character at a time, with every character chosen by Jev.
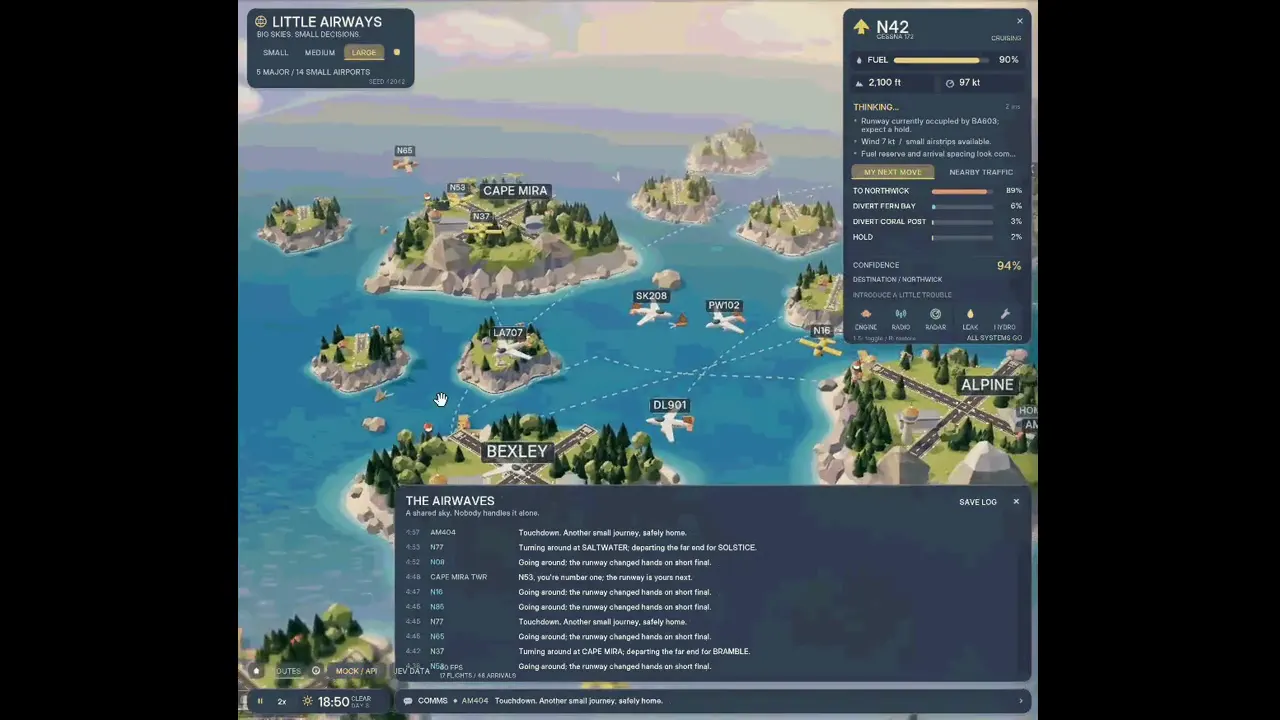
Little Airways puts Jev's decision-making into a small browser-based flying demo.
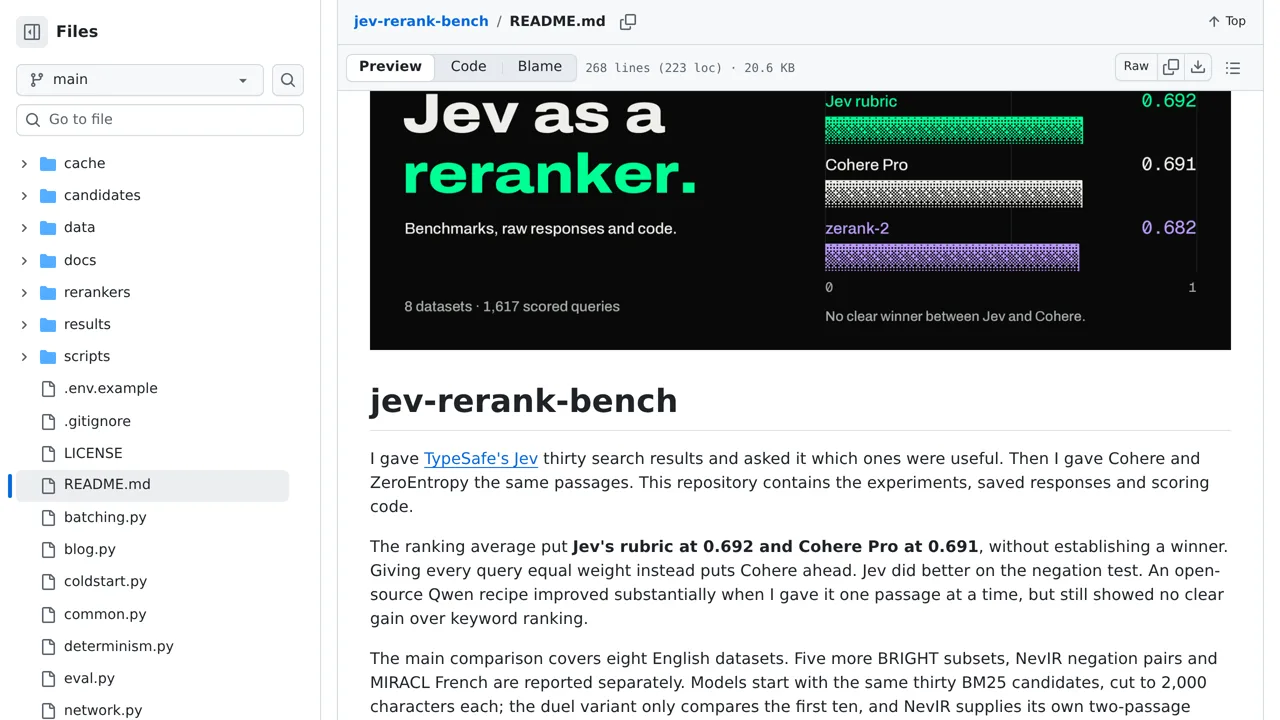
This benchmark compares Jev with Cohere, ZeroEntropy, and a chat model on 14 reranking datasets.
This harness evaluates Jev Ultrafast on curated research-browser cases and generates a field report from each run.
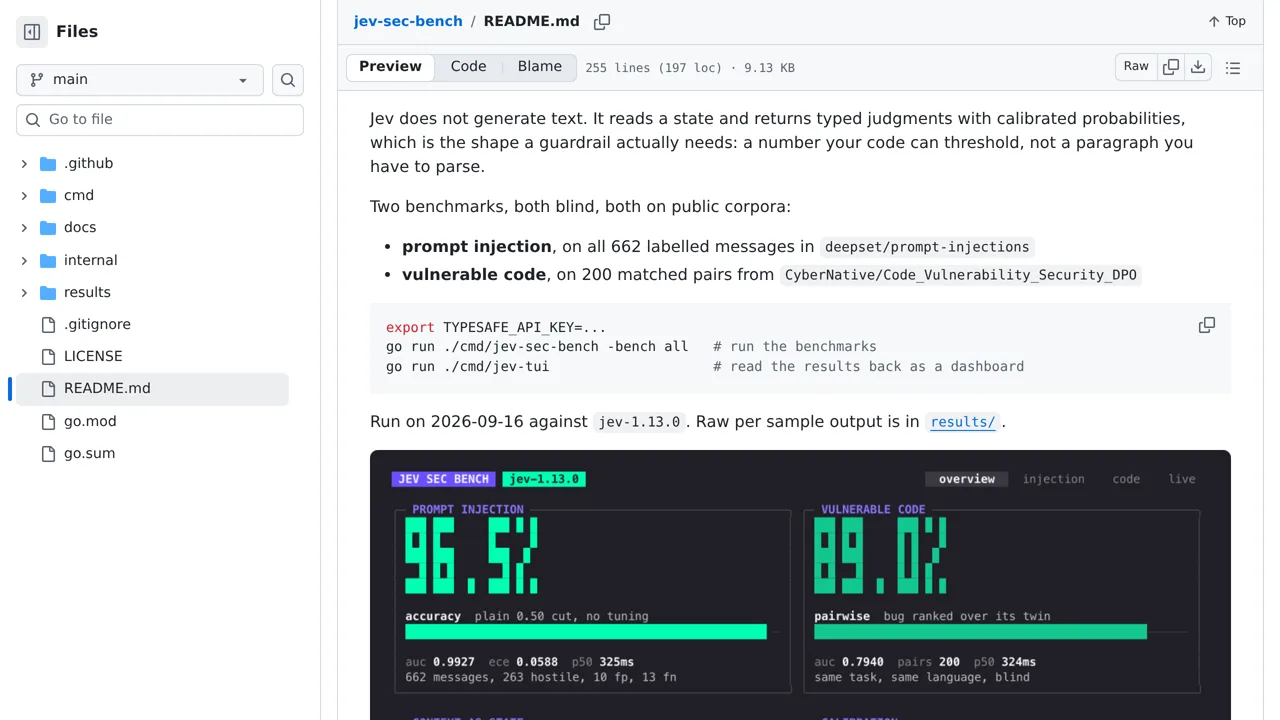
jev-sec-bench tests Jev blindly on prompt-injection and vulnerable-code detection tasks.
This demo compares Jev's abstract-screening decisions with gold labels from the ASReview SYNERGY dataset.
This static dashboard compares Jev and two Luna settings on Japan's 2026 Common Test.
Explore a Monte Carlo tree search that uses Gemini to propose paths and Jev to judge them.
PadFlow contributes anonymized land-development decisions for testing confidence-aware models such as Jev.
qwen-rlcd trains Qwen3.5-0.8B to make Jev-style choices, scores, and binary judgments with calibrated confidence.
RISC-jeV asks how far state-in, decision-out inference can go by wiring Jev up as a RISC-V CPU.
These OpenJev experiments classify sentence pairs, including whether one statement follows from or contradicts another.
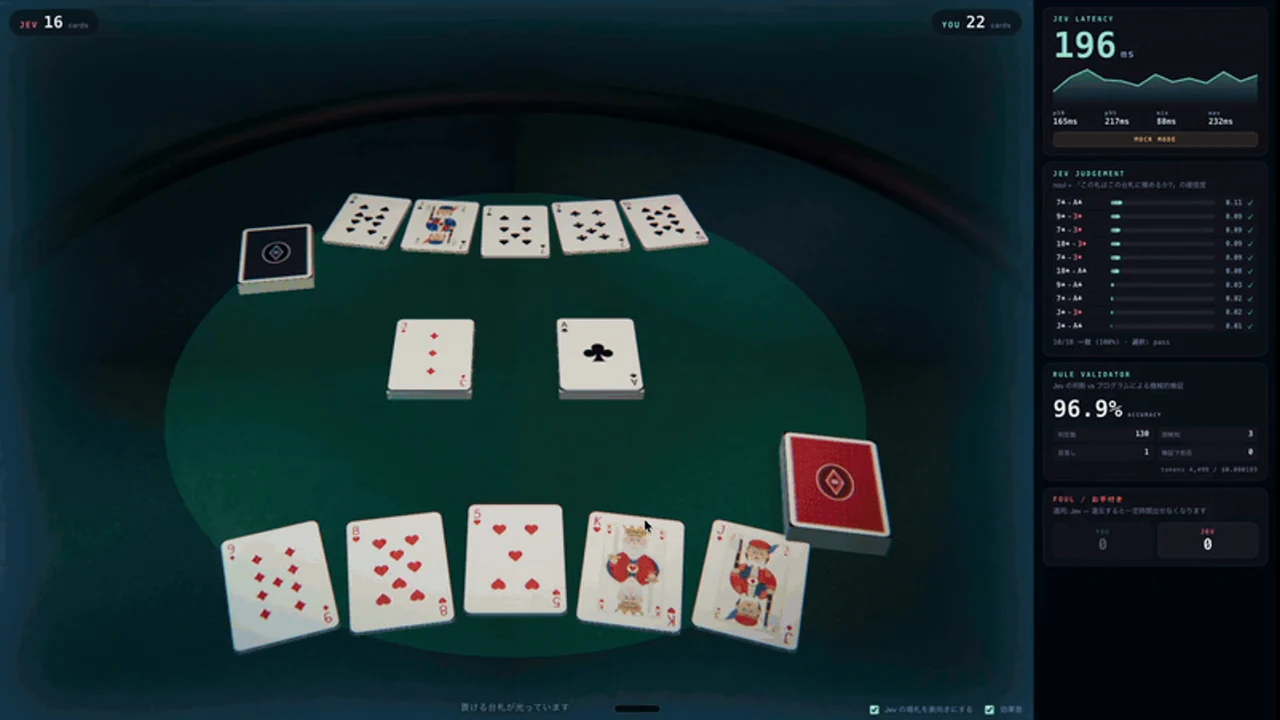
Race Jev at the card game Speed while the interface reveals its legal-move beliefs, chosen play, and pressure rating.
Play Battleship against Jev, follow its probability heatmap, or match it against text models on identical fleets.
Jev ranks the available moves in a Python 2048 engine designed for AI search and browser spectating.
Inspect and operate an SO-101 robot workbench where Jev can choose bounded joint movements.
Browse an arcade of Jev-piloted experiments spanning Flappy Bird, Pong, Invaders, flight, driving, space, and survival.
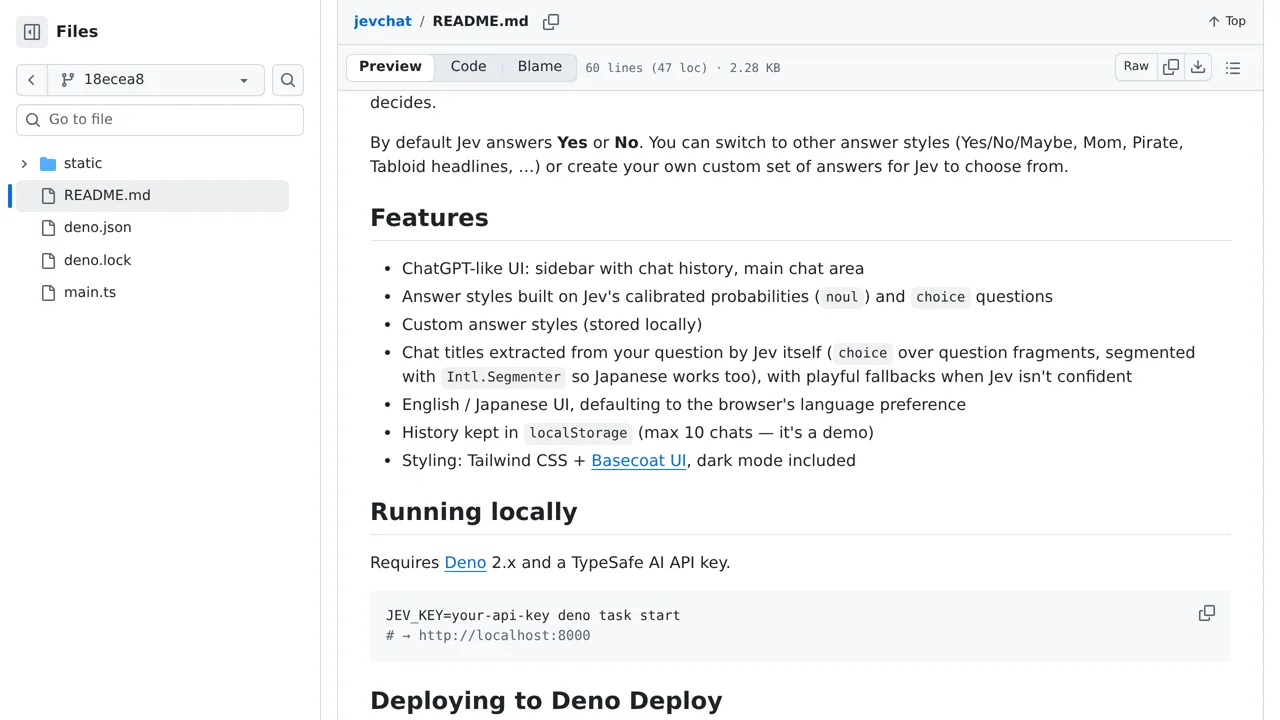
Chat with a model that cannot write: Jev can only pick from yes/no, pirate, headline, fortune, or custom canned replies.
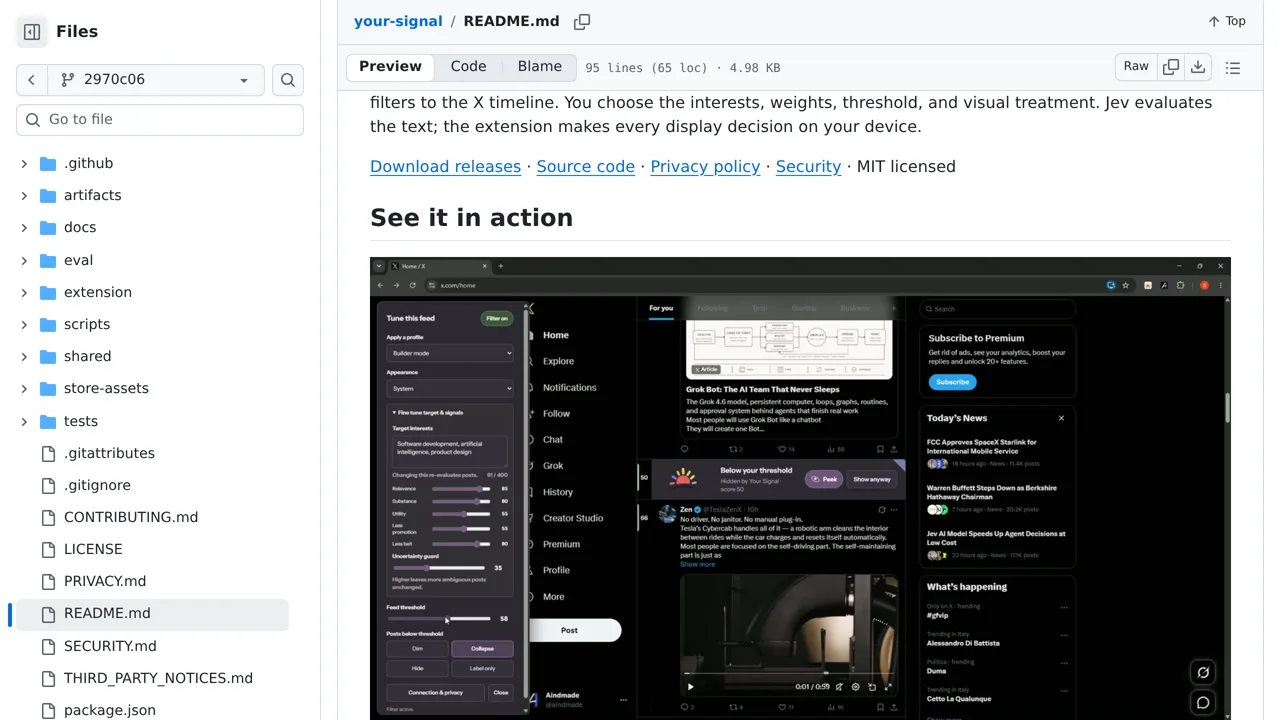
Define what deserves your attention on X, then highlight, dim, collapse, or hide posts without losing the option to reverse it.
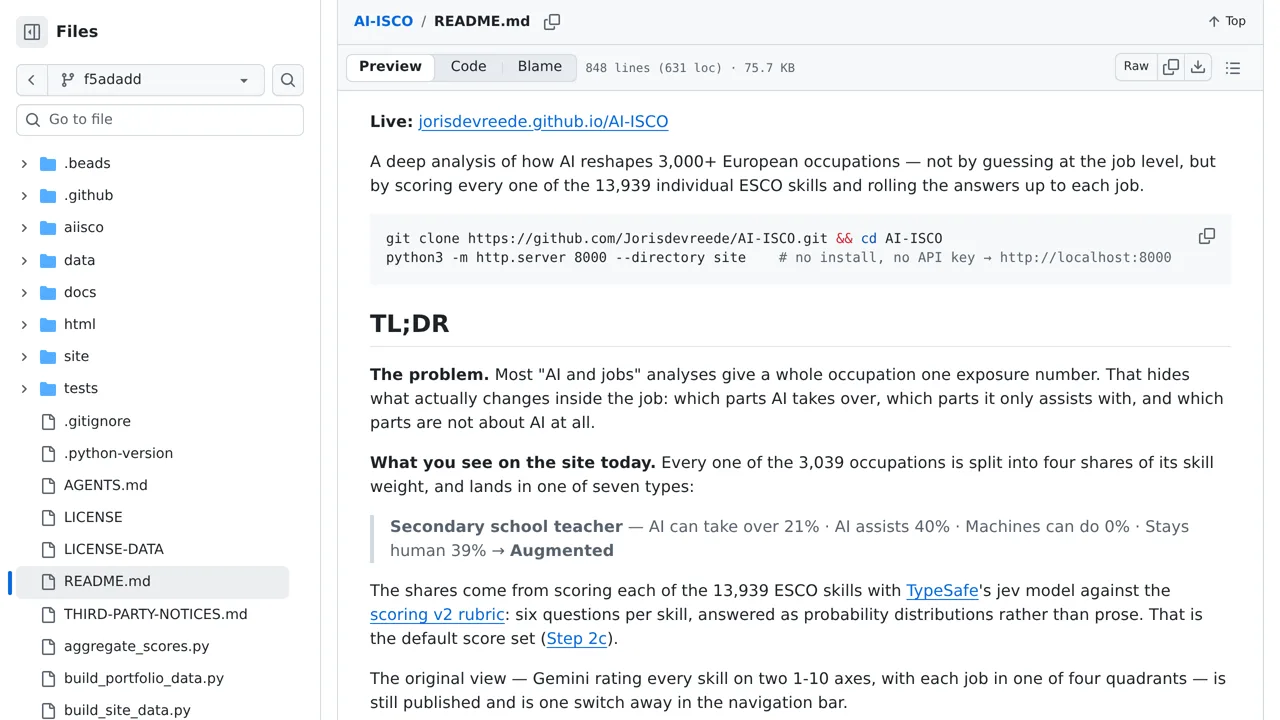
See how estimated automation risk and AI amplification roll up from nearly 14,000 skills into European occupations.
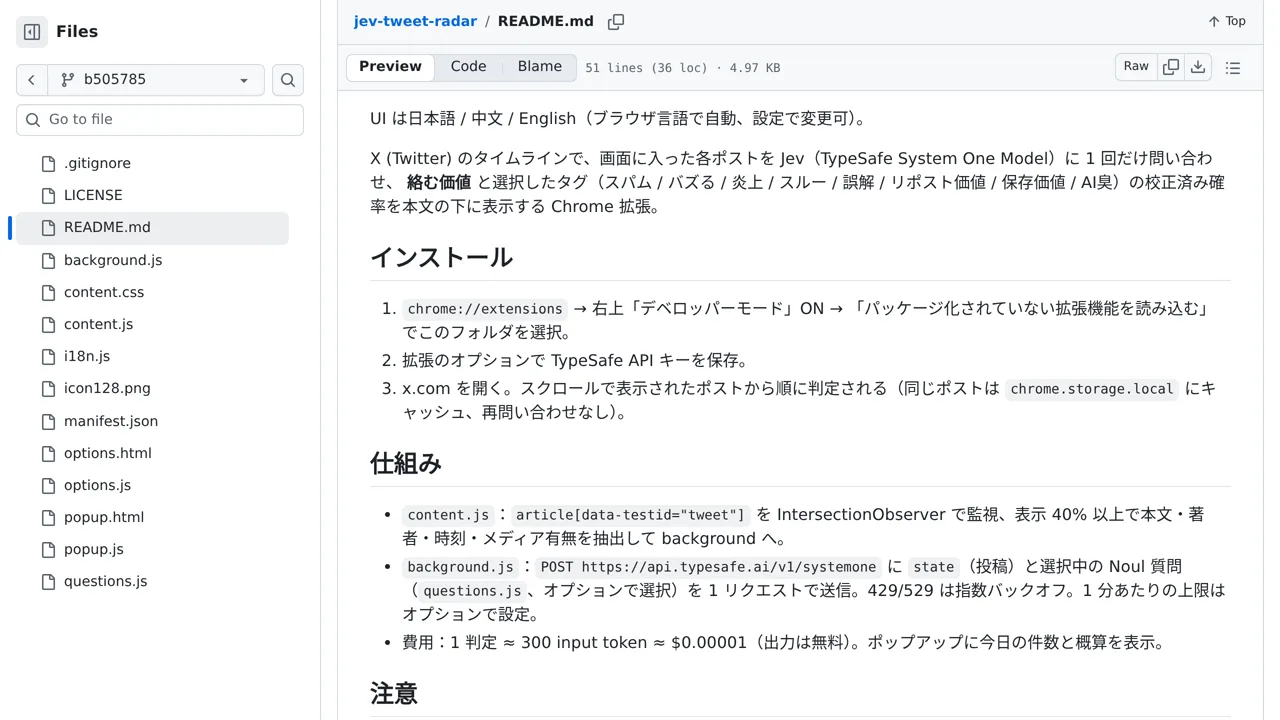
Overlay X with scores for engagement value, spam, buzz, misreading risk, and other signals you choose.
Use Jev as a low-cost first-pass scorer for fundamentals in a simulated U.S. equity research pipeline.
Lets agents gather audit context while Jev assigns severity, confidence and routing judgments for code-owned policy.
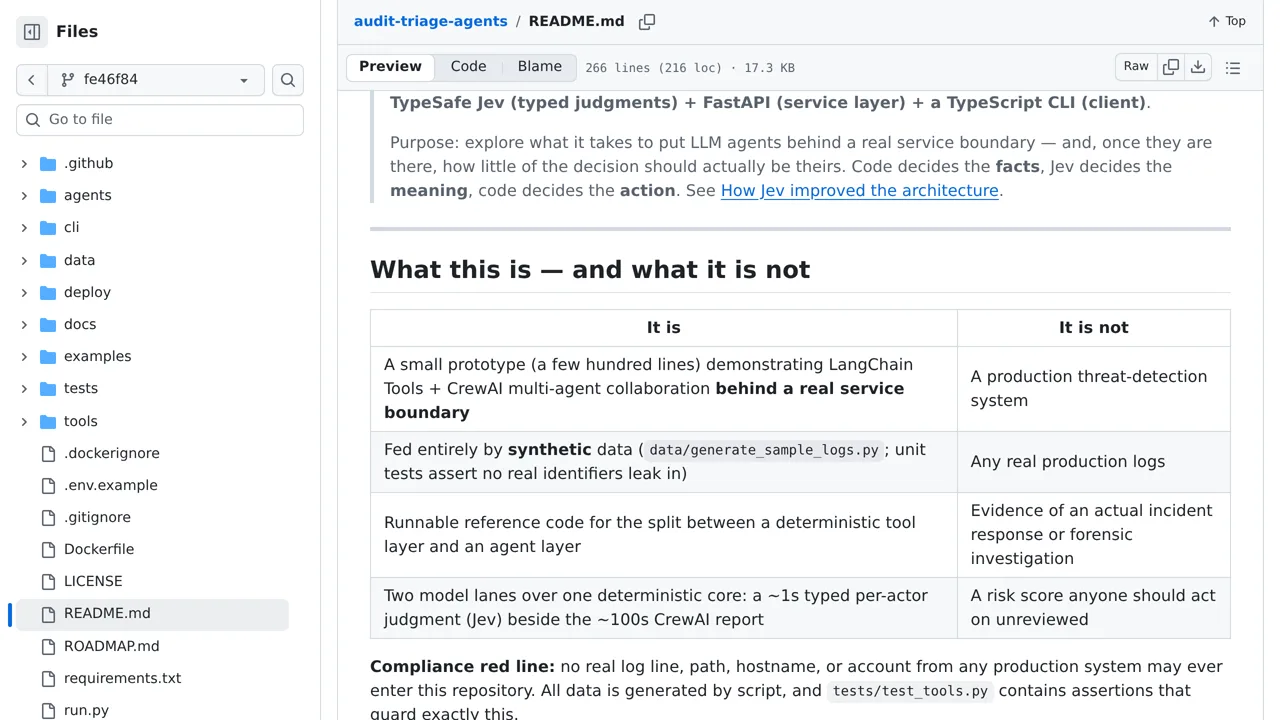
Remove stale read-only Pi tool exchanges while preserving every retained piece of evidence byte for byte.
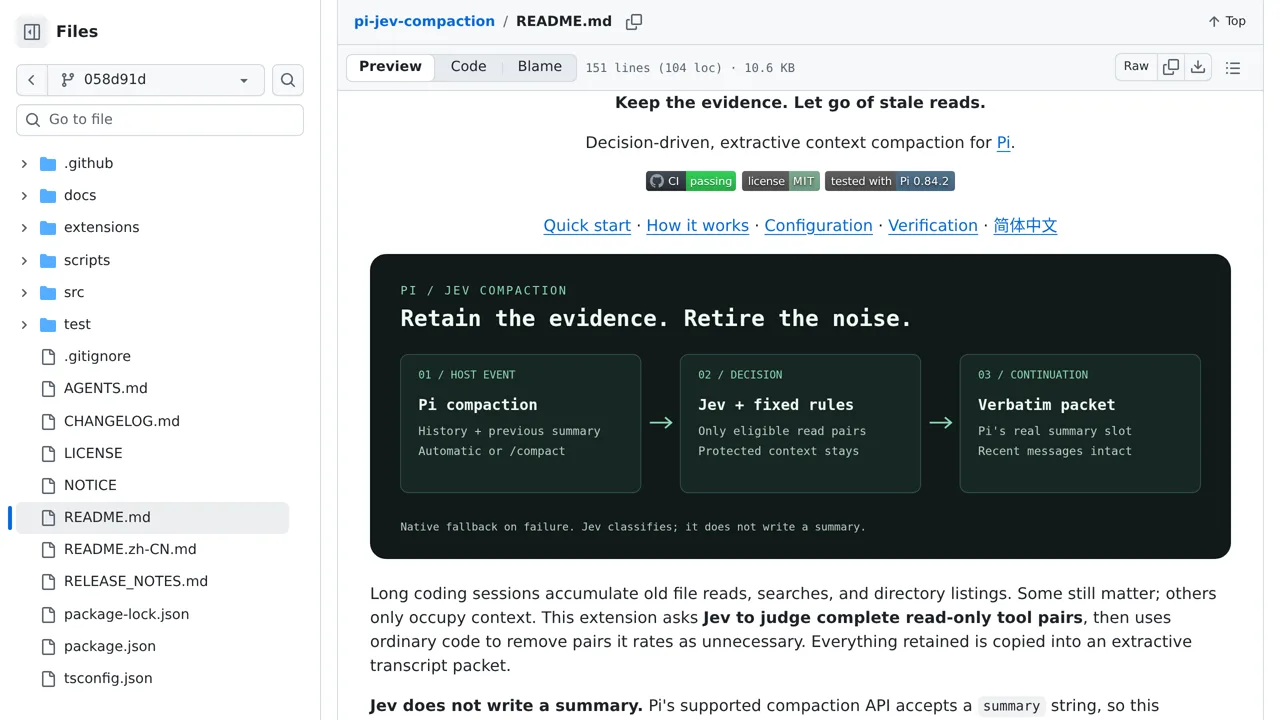
A practical guide and prototype for putting Jev triage in front of Herdr-managed coding agents.
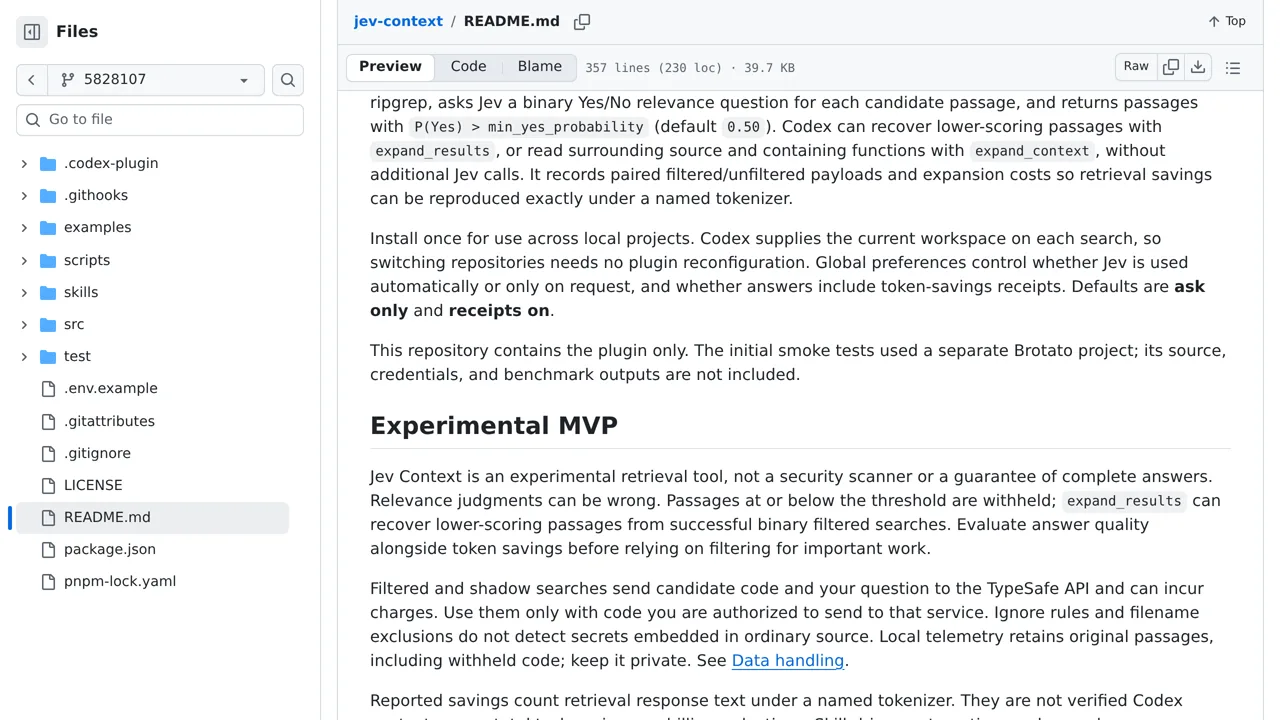
Filter ripgrep passages for a Codex task without losing the ability to reveal hidden results or nearby code.
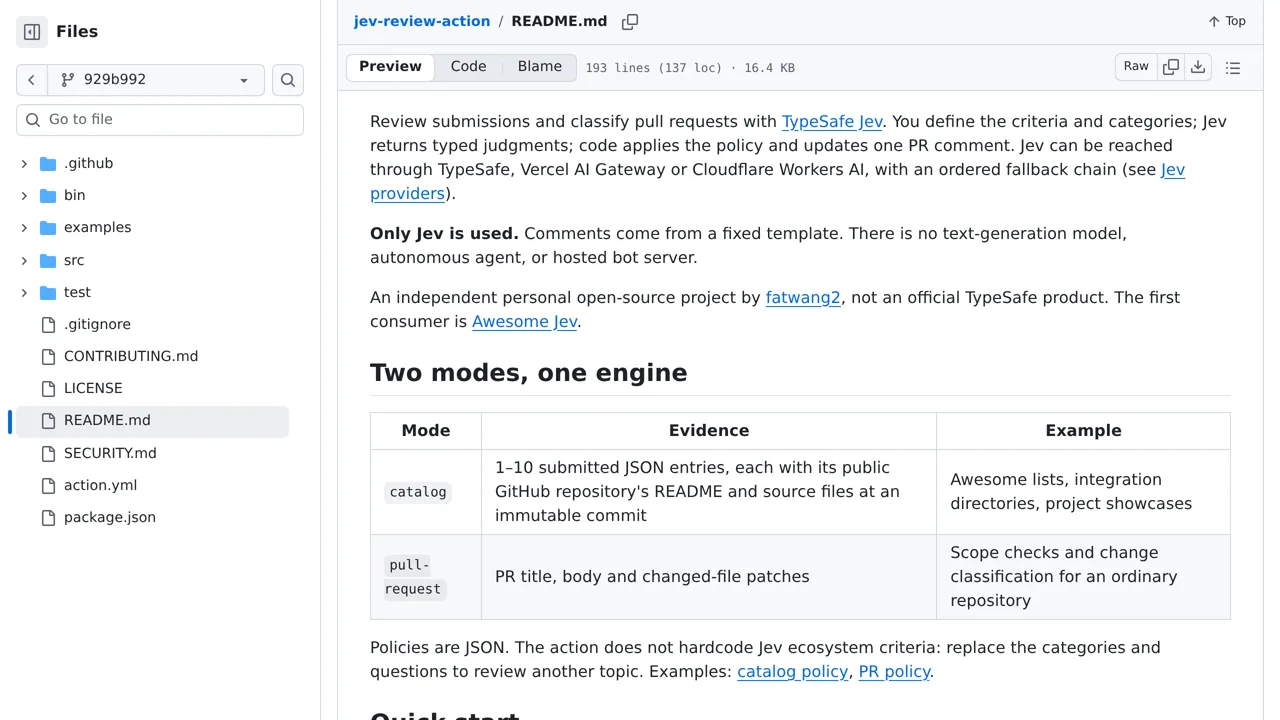
Reviews catalog submissions or pull-request patches and posts a single fixed-format policy result to GitHub.
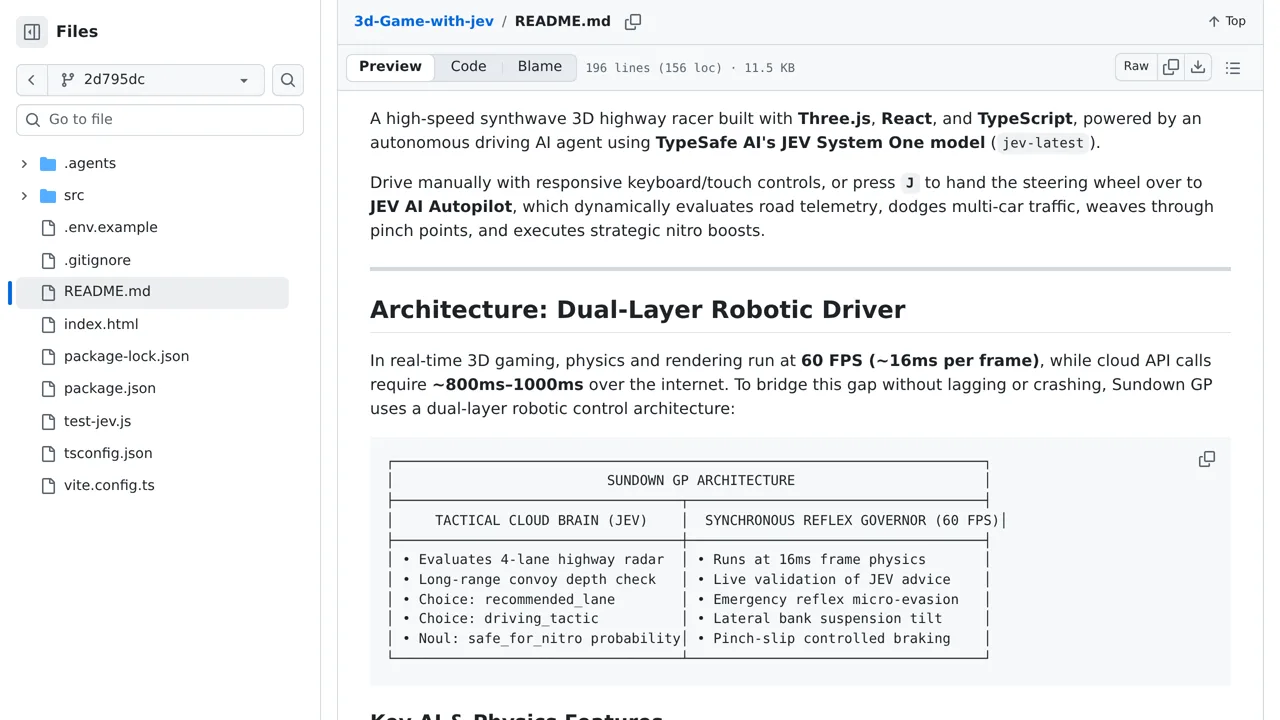
A synthwave highway racer where Jev suggests lanes, tactics and nitro while a per-frame governor watches the moving road.
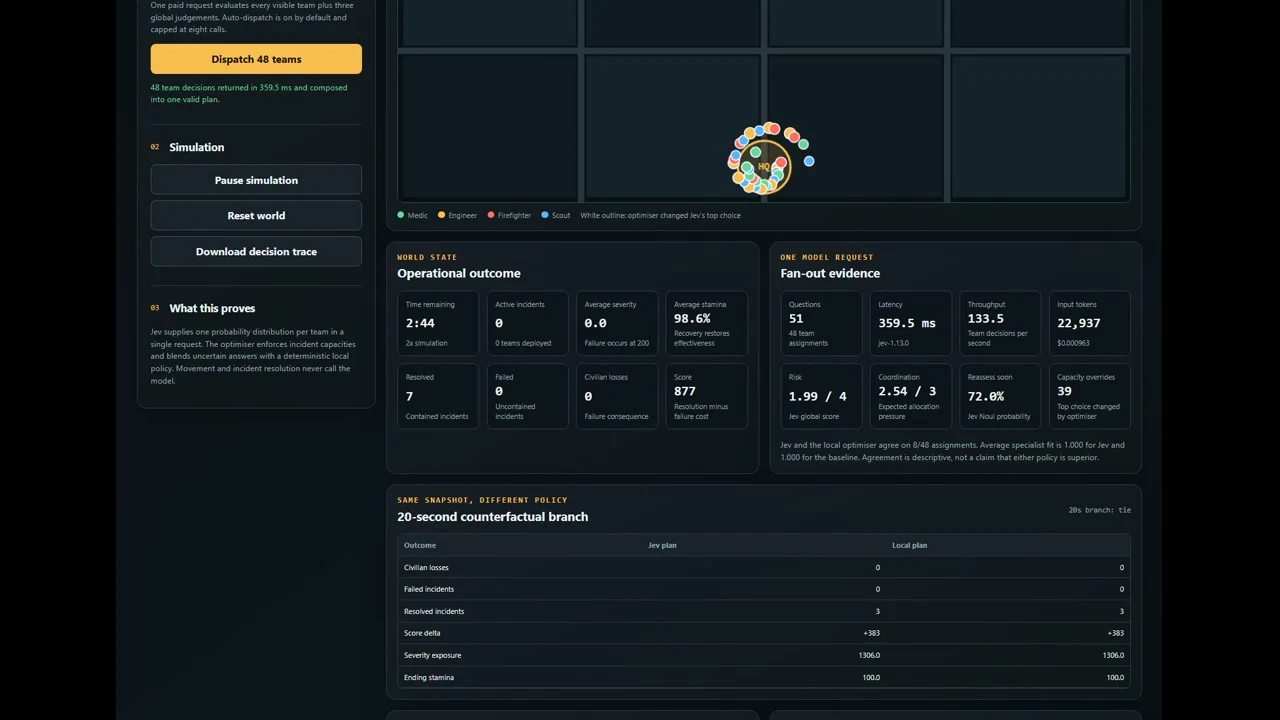
A crisis-response simulation in which Jev helps decide where to send each team.
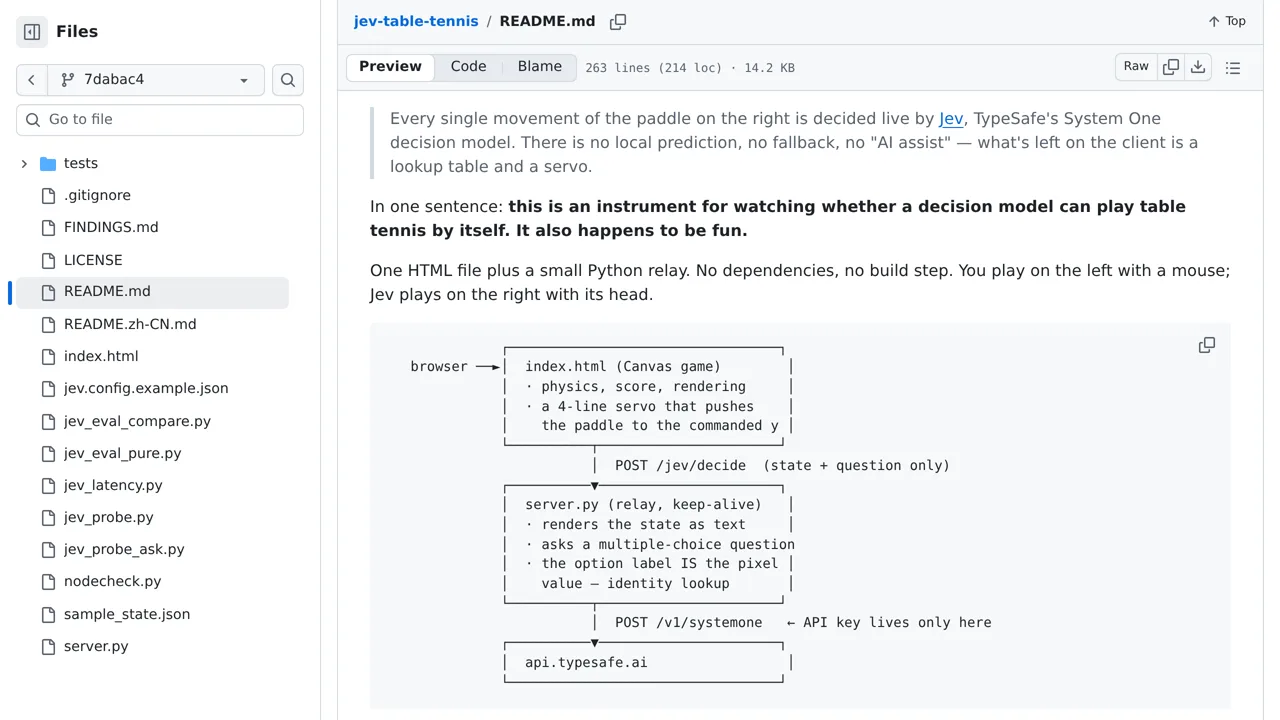
A table-tennis game where Jev's answer is the paddle's target pixel and a tiny local servo simply moves there.
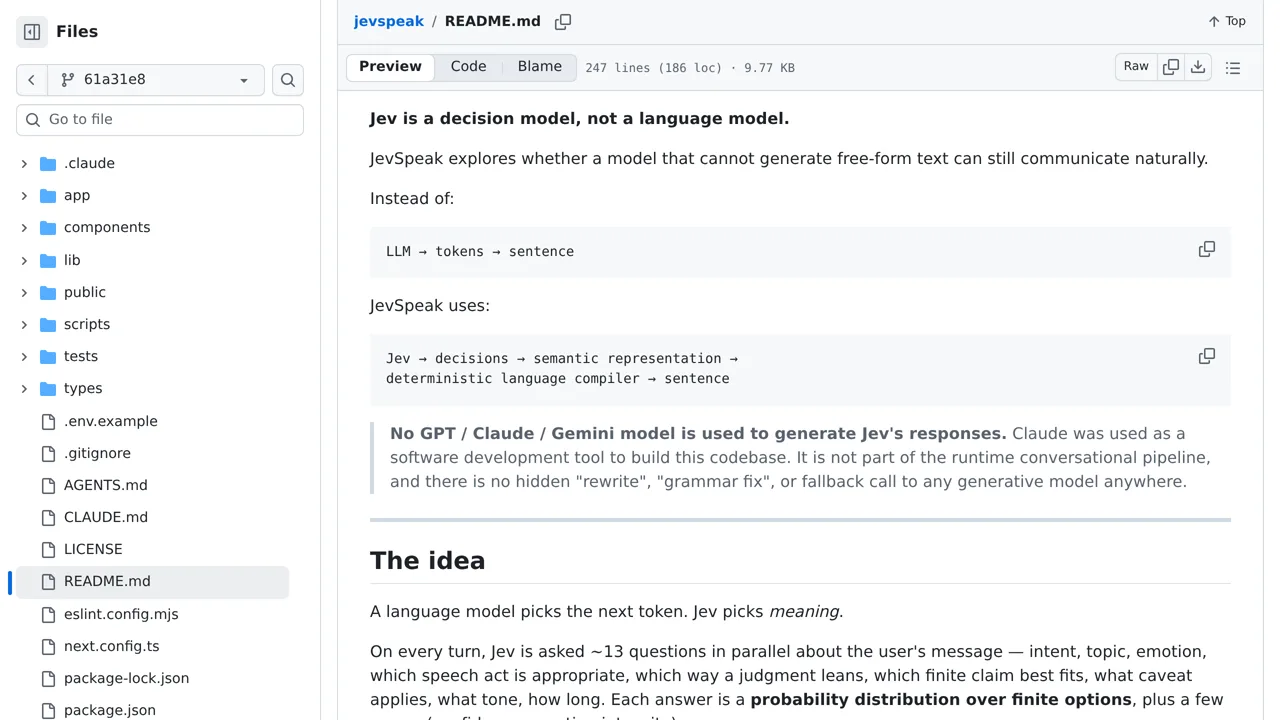
Turns Jev's judgments into conversation by compiling a semantic plan into an English sentence.
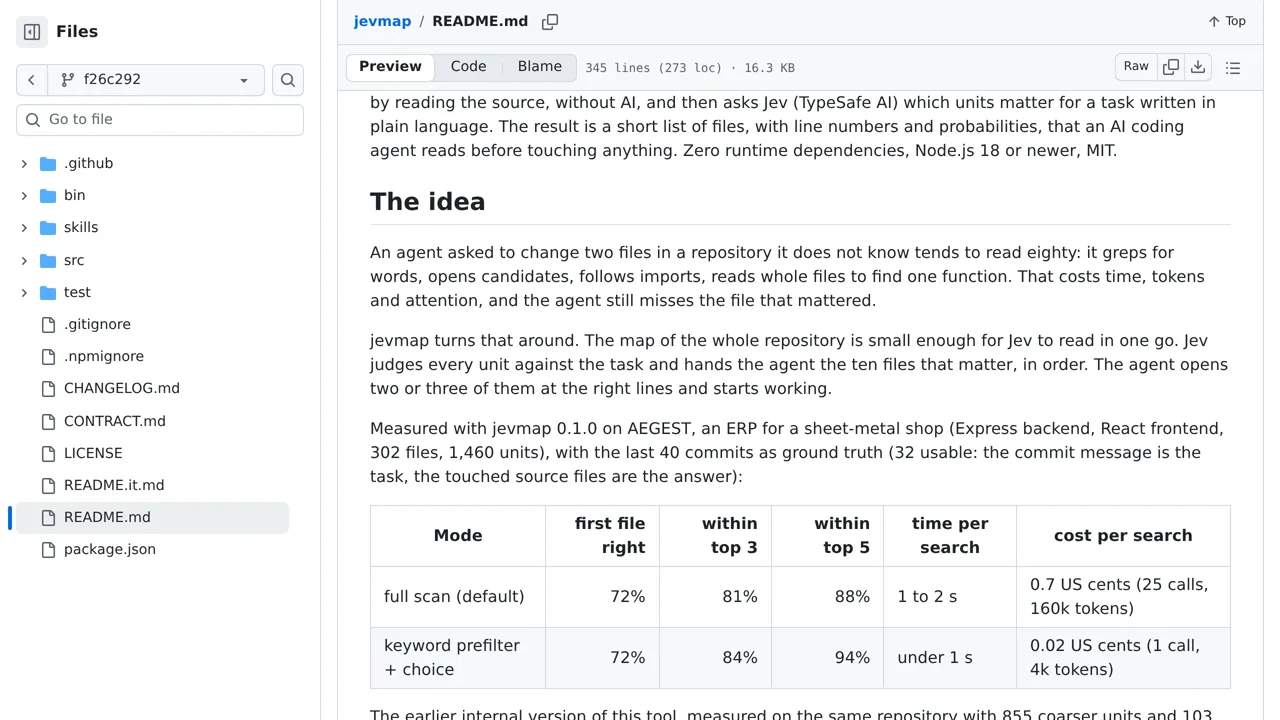
Find files and line ranges relevant to a coding task with a searchable map of your source code.
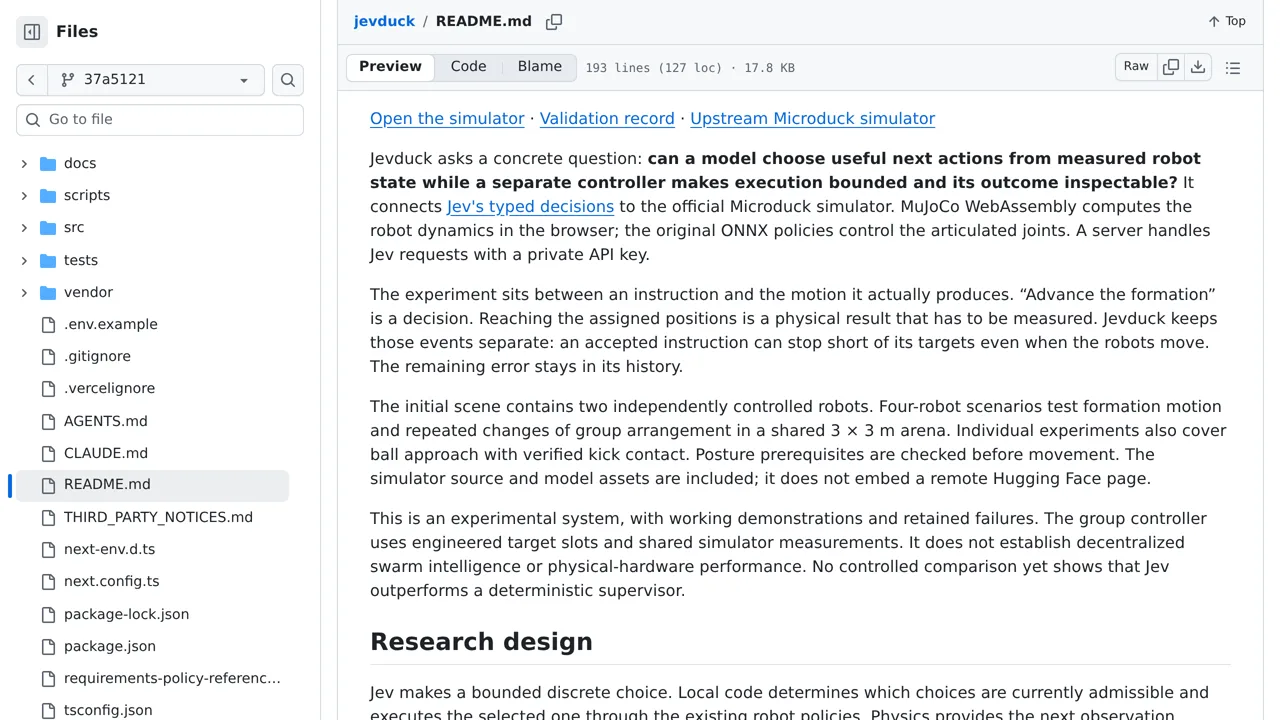
A browser MuJoCo lab where Jev chooses instructions for individual robot ducks or a small swarm.
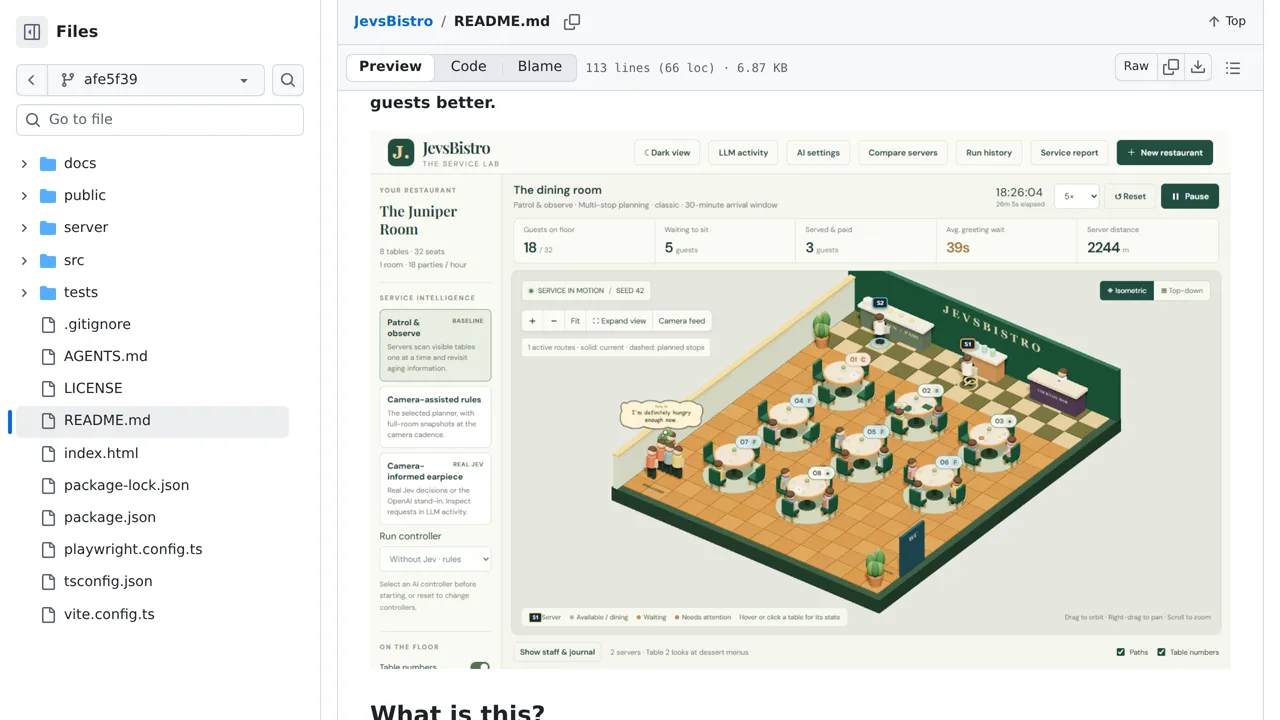
Replays the same restaurant evening under hand-written rules or Jev-selected service tours for a fair side-by-side comparison.
Experiment with a Jev-powered Codenames player and a separate CLI for checking determinism, sensitivity and calibration.
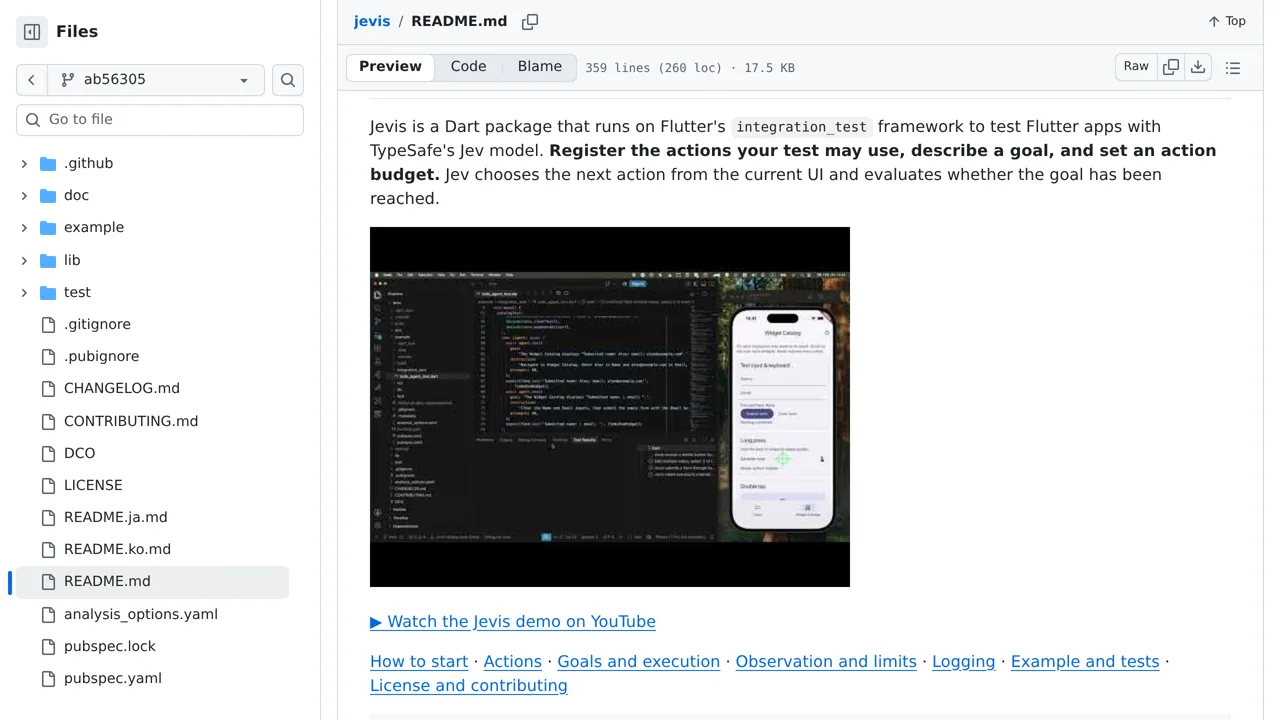
Lets a Flutter integration test state its goal, then chooses registered UI actions until that goal is met or attempts run out.
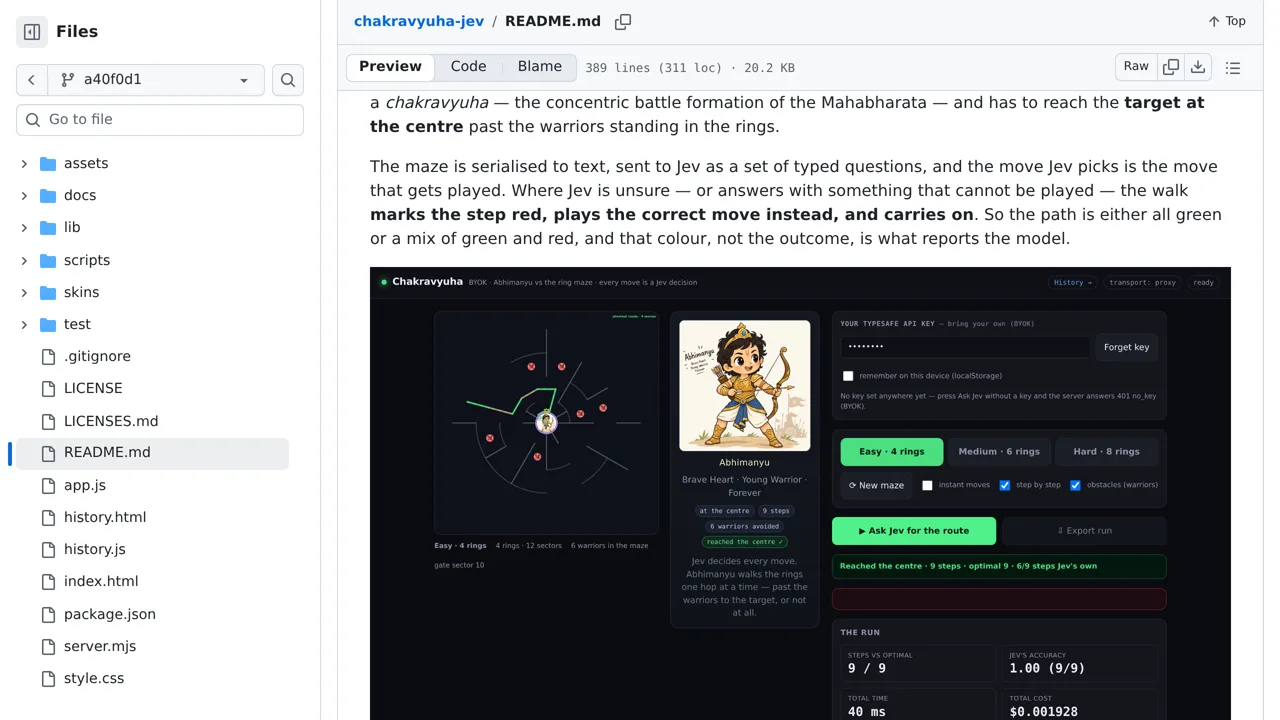
A ring-maze game that asks Jev for the best move from every cell, then colors each played or overruled step.
An AI player tackles Unreal Tournament 99 on a real Windows 98 machine.
A self-running browser instrument that asks Jev which musical scene, harmony, phrase, riff and timbre should arrive next.
Coaxes sentences from a classifier by choosing a domain, then asking Jev to pick each next word from bounded vocabularies.
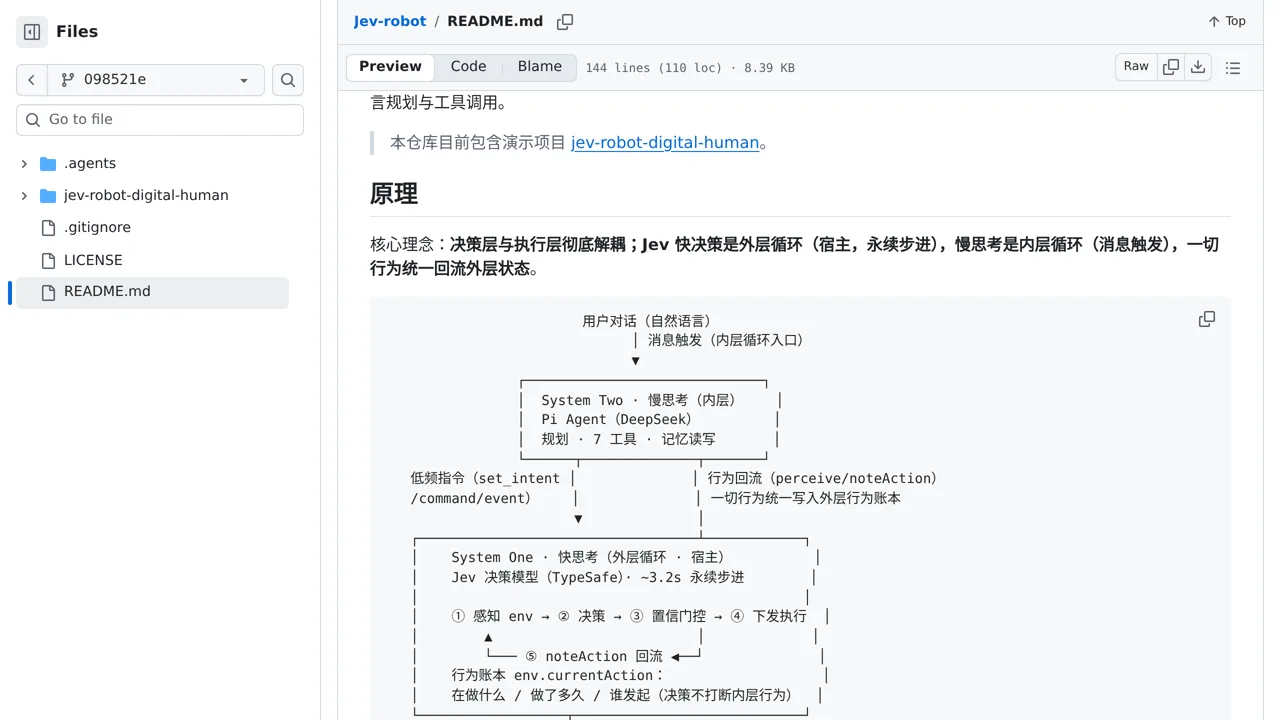
A 3D character whose movements, expressions and gaze are chosen by Jev.
Listens to a language lesson, judges corrections and useful moments, then builds notes only from words the participants actually said.
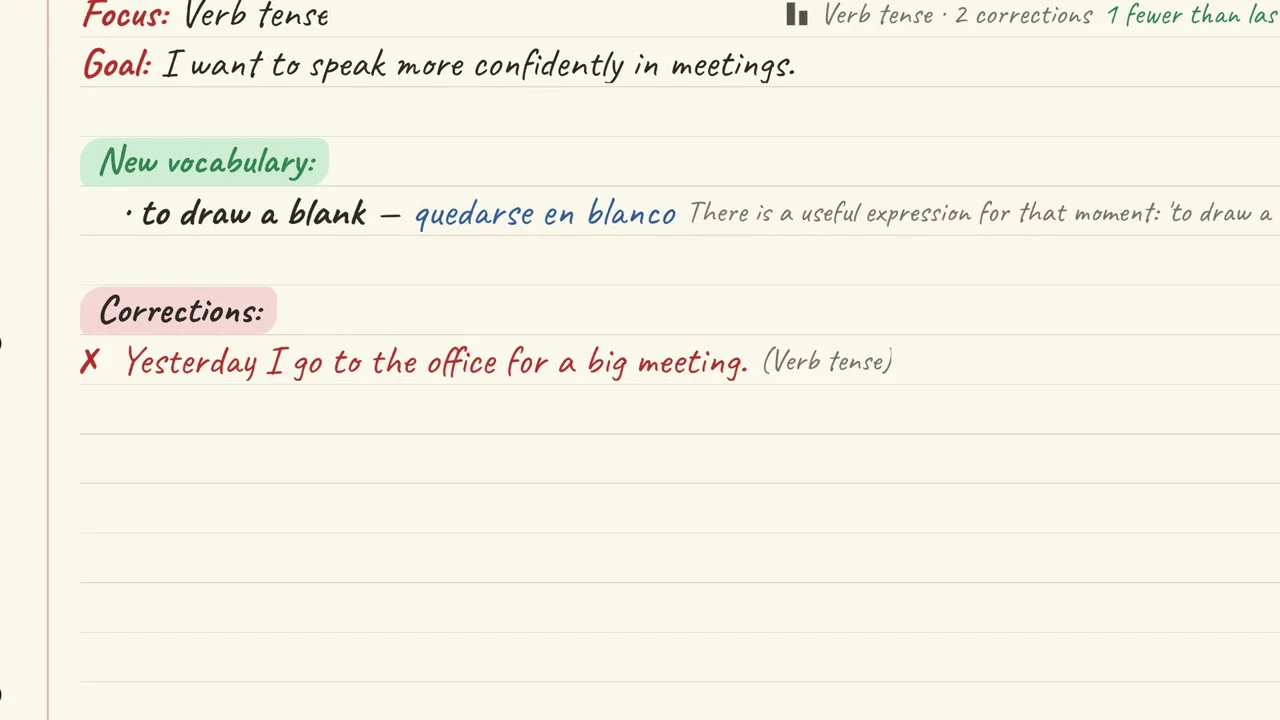
Two Jev brains perform a fixed piano piece, choosing hand and finger positions for each 100-millisecond slice ahead of time.
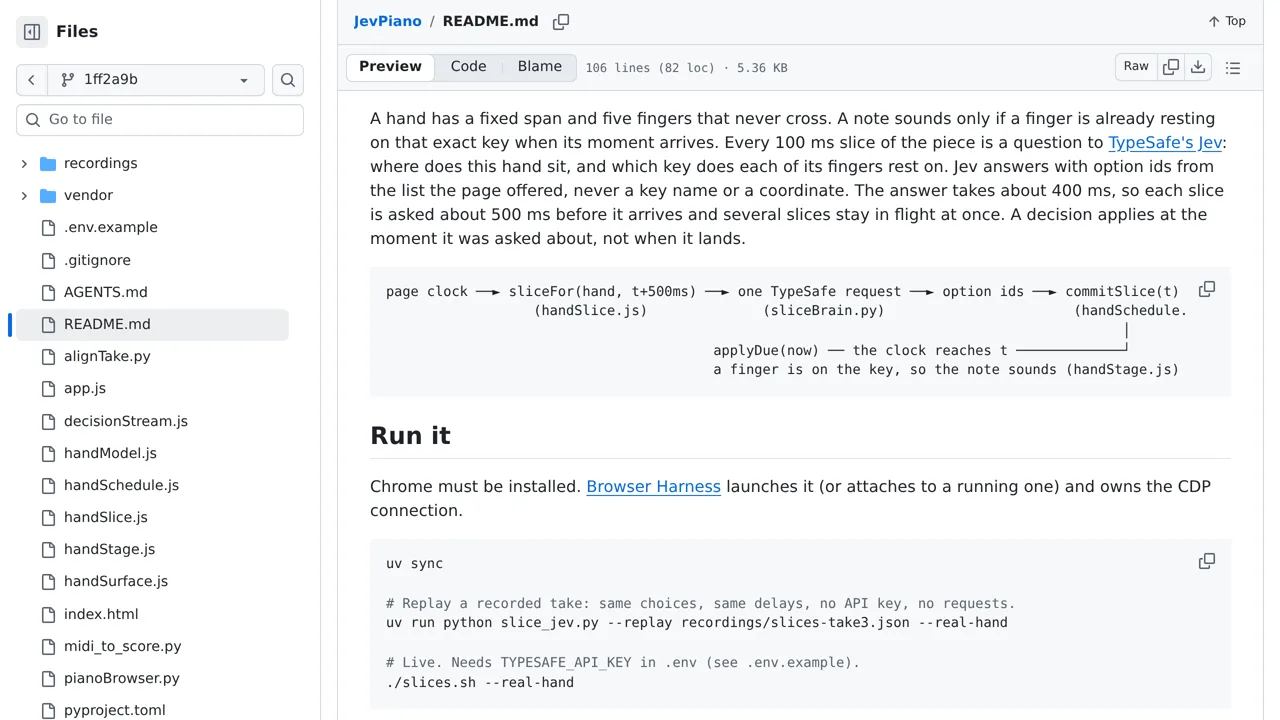
A paper-trading options workspace where Jev chooses among complete structures built from the live quoted chain—or simply holds.
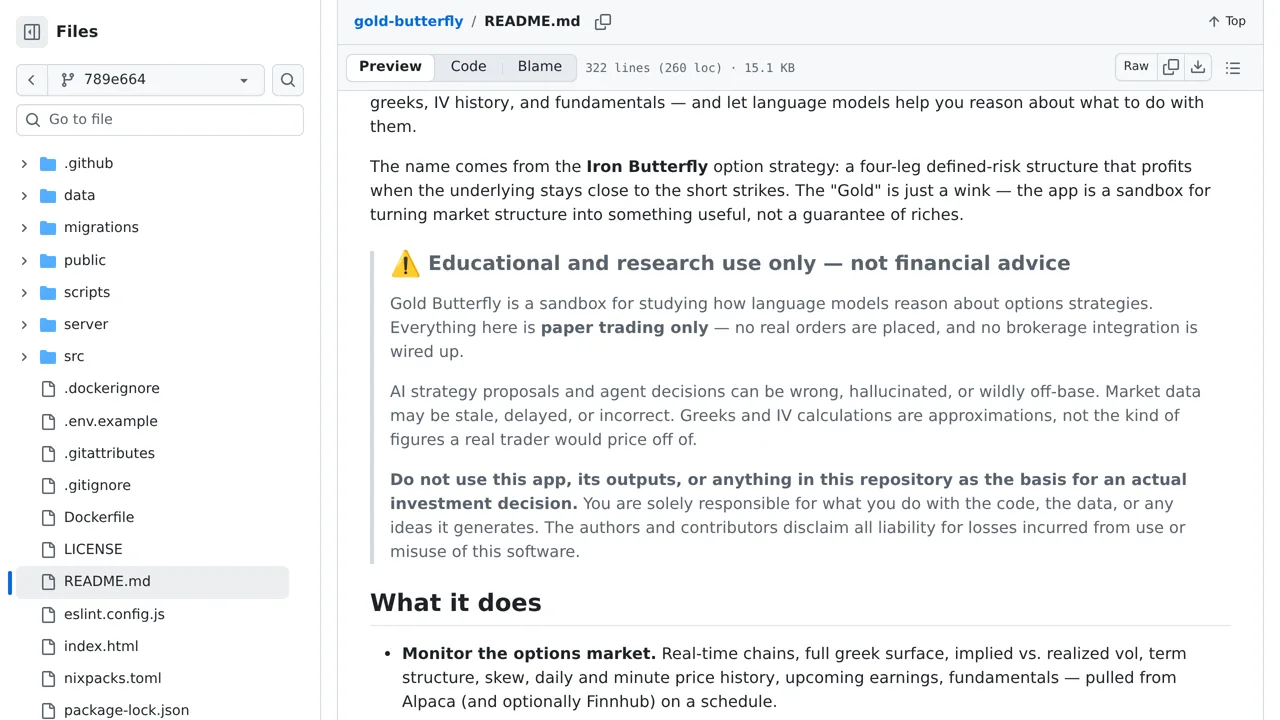
Pitch an invention to three fictional judges and try to win their votes.
A pixel-art experiment that asks Jev to choose the colors from a short brief.
Turns a word into ranked associations for taste, material, smell and shape using four fixed sensory vocabularies.
Three experiments in making color themes, photo grades and charts from Jev's decisions.
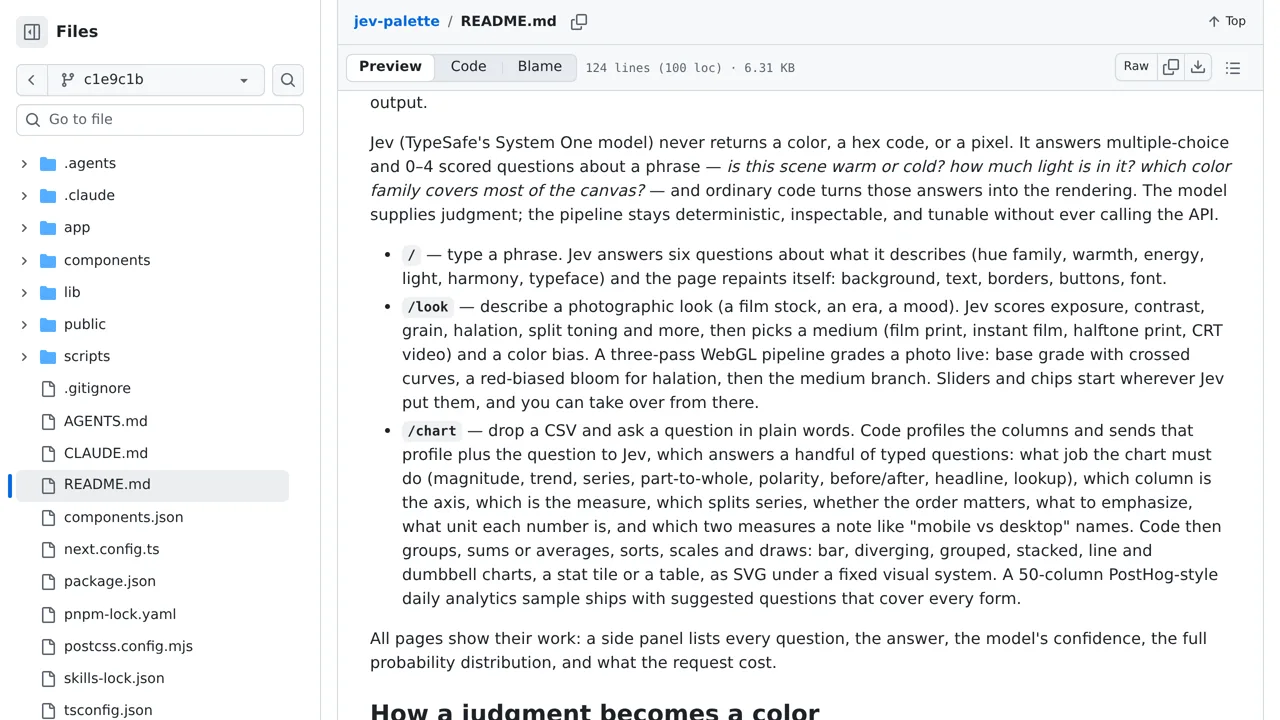
A local RSS inbox that screens articles for relevance, substance, evidence, promotion, context and personal exclusions.
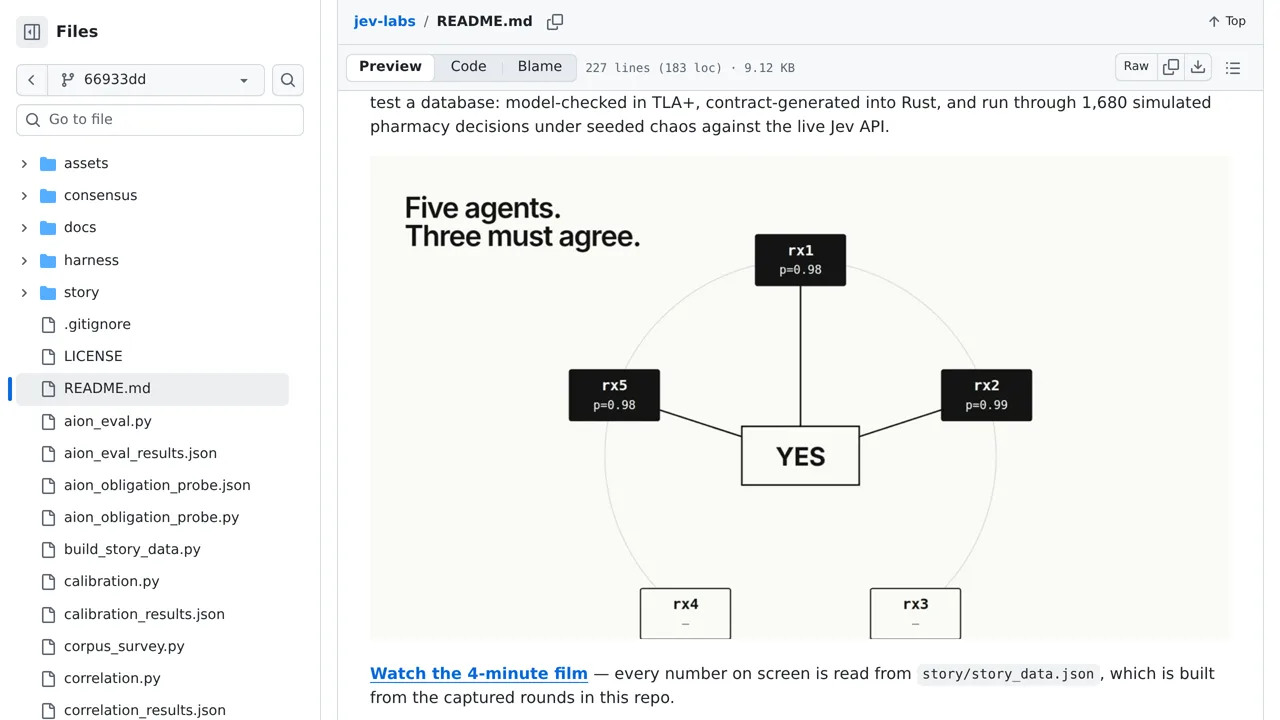
An experimental pharmacy checker that asks Jev the same question five ways and looks for agreement.
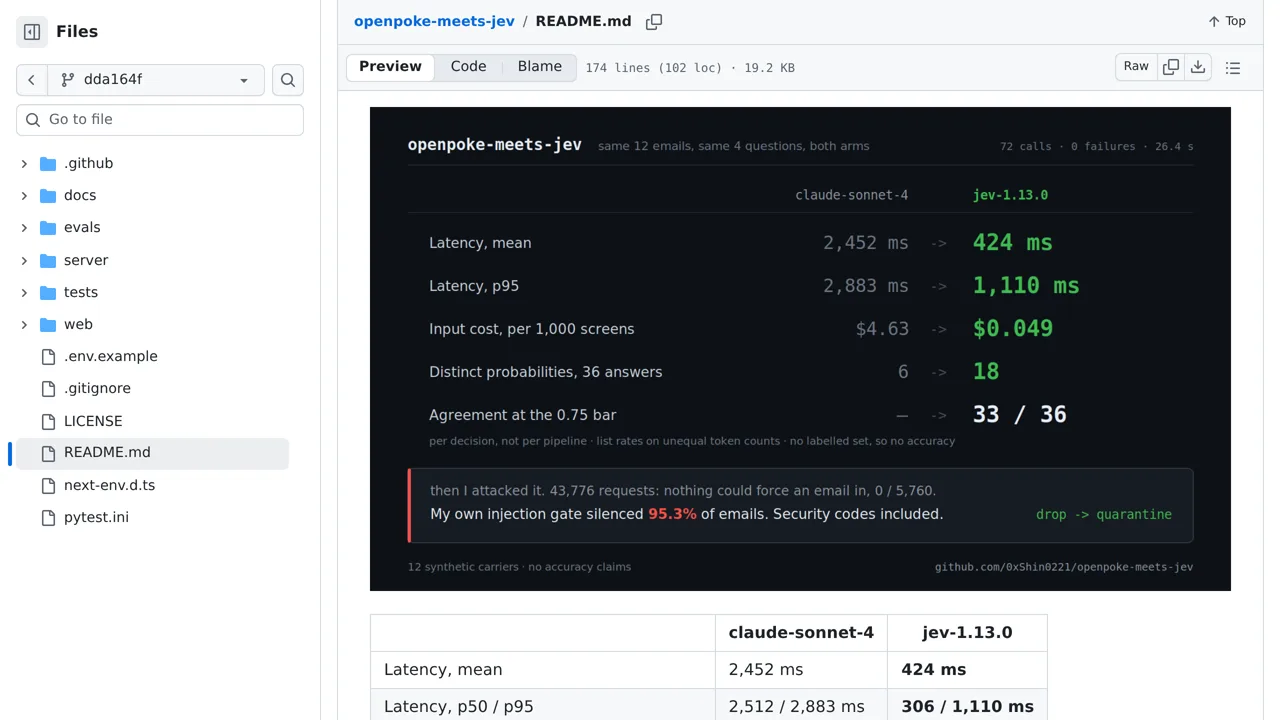
An experiment in replacing an email assistant's expensive model checks with Jev.
Jev, briefly
A chat model generates text token by token and hopes you parse it. Jev never generates a word. Your code sends the state of the world plus typed questions; Jev returns every answer in one parallel pass — typed values with calibrated probabilities and a confidence score your code can trust. About 70–500 ms end to end, $0.042 per million input tokens, output free. Trained with what TypeSafe calls Reinforcement Learning for Calibrated Decisions.
You define the options. Jev returns the chosen option, a probability for every option, and a confidence. The workhorse of routing, agents, and games — the answer space is always legal, so there is nothing to parse and nothing to hallucinate.
You describe ordered levels — say trivial / normal / critical. Jev returns the level, the probability of each, and a confidence. Scores turn fuzzy judgment (“how severe is this log line?”) into a number-free decision your code can branch on.
You assert a statement; Jev returns the probability that it is true — a noul. Moderation, verification, guardrails, “does this diff actually fix the bug?”: one question, one calibrated probability.
Official material lives at typesafe.ai and docs.typesafe.ai. JevMade is an independent community registry — not affiliated with or endorsed by TypeSafe AI.
Recurring lessons
Games, drones, trading bots, and browser agents all converge on the same loop: serialize the state, ask one decisive question, act, repeat. Jev’s latency makes the loop feel instant — the model lives inside the control loop, not outside it.
The answer says what; the confidence says whether to act. The most reliable entries threshold on confidence to route edge cases to a slower model or a human — automation with an honest escape hatch.
Makers rarely ask Jev to pick from everything. Local tactics prune 225 gomoku moves to ~40; DOM filters turn a page into an element table; code narrows options, Jev judges within them.
A recurring split: Jev makes every decision cheaply and instantly, and a small LLM is only invoked when a human-facing string must actually be written. Decision and generation are separate budgets.
Send the link — repo, live demo, post, or video — plus a line on what it does and which primitives it uses. Every entry is verified against its primary source before it ships.
Submit your experiment → hello@JevMade.com