The full collection
A different way to learn.
197 videos · showing 73–96
 ▶
33:01
by AI News & Strategy Daily | Nate B Jones
Nate B. Jones explores TypeSafe's Jev classifier, outlining how a dedicated multi-choice model fits into software architectures, agent orchestration, and automated pipelines alongside LLMs.
Duration: 33 minutes 1 seconds.
 ▶
12:37
by AI News Today | Julian Goldie Podcast
This video explains how to build front-door model routing for AI agents using Jev. It covers creating model lanes with descriptive criteria, routing on confidence thresholds, handling multi-query task profiling, choosing between sticky and turn-by-turn routing, and establishing fallback mechanisms when network calls fail.
Duration: 12 minutes 37 seconds.
 ▶
25:20
by 起業の履歴書【AI解説】
Japanese tech commentators explain TypeSafe AI's Jev model, contrasting its fast System 1 parallel decision design with slow System 2 generative LLMs. They examine Diogo Almeida's 'Bitterest Lesson', RLCD decision training, and the practical software automation possibilities created by lower latency and cost.
Duration: 25 minutes 20 seconds.
 ▶
10:20
by bitwise
This video breaks down TypeSafe AI's Jev model, contrasting System 1 fast structured decision-making against sequential generative LLMs. It explains parallel sampling, RLCD calibration, claimed sub-500ms latencies, and practical use cases.
Duration: 10 minutes 20 seconds.
 ▶
13:02
by CoderOne
CoderOne introduces TypeSafe's Jev System 1 classification model alongside open-source alternatives like Laya. The video examines browser automation workflows, contrasts System 1 fast decisions with System 2 reasoning, and demonstrates Jev's API schema in the developer playground using state definitions and typed classification criteria.
Duration: 13 minutes 2 seconds.
 ▶
16:50
by Dave Ebbelaar
Dave Ebbelaar builds a Python support-ticket flow, inspects category probabilities, and combines category, frustration, and refund questions in one call. He also explains why sending client data to a new provider needs a separate privacy decision, even when the API is easy to use.
Duration: 16 minutes 50 seconds.
 ▶
1:30
by devblackie
This video introduces TypeSafe AI's Jev, contrasting text-generating LLMs with parallel typed decision-making. It demonstrates ticket routing workflows using predefined questions and confidence scores.
Duration: 1 minutes 30 seconds.
 ▶
15:09
by Farzam Arefi
Farzam Arefi demonstrates using the TypeSafe AI playground to configure Jev primitives. The video breaks down state evaluation and details how to format Noul, choice, and score question types, interpret probability distributions and confidence scores, and structure multi-primitive parallel requests.
Duration: 15 minutes 9 seconds.
 ▶
13:40
by Gary Chen
This video breaks down TypeSafe AI's Jev model, explaining its discrete three decision modes (boolean, categorical, and graded rating scales) and showing how to integrate it into automated customer support routing workflows as an ultra-fast classification filter and post-generation safety check.
Duration: 13 minutes 40 seconds.
 ▶
5:05
by Inference Desk
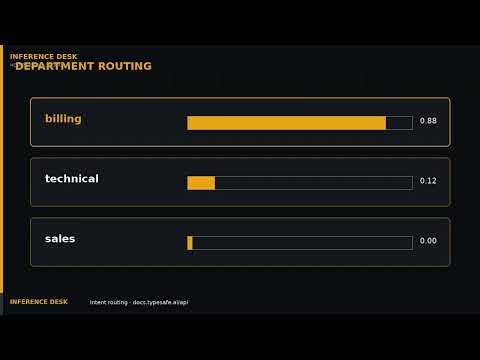
Inference Desk explains Jev’s binary, categorical, and scoring questions, then connects the request schema to application control flow. The examples cover independent questions over one state and confidence gates that send uncertain cases to another handler.
Duration: 5 minutes 5 seconds.
 ▶
10:12
by Infra Blueprint
This video examines TypeSafe AI's Jev model, explaining its non-autoregressive typed primitives (Noul, Choice, Score) for fast decision-making. It outlines confidence-gated routing cascades and practical operational limitations.
Duration: 10 minutes 12 seconds.
 ▶
11:46
by Jay E | RoboNuggets
This video introduces TypeSafe's Jev model as a fast, low-cost system-one classifier. It demonstrates integrating Jev with Claude Code across three practical levels: internal agent routing and skill selection, high-volume batch triage like lead qualification, and application-level features including semantic UI filtering and element removal.
Duration: 11 minutes 46 seconds.
 ▶
17:13
by Cole Medin
Cole Medin explains Jev, TypeSafe's fast decision-making AI model trained with RLCD. He demonstrates practical implementations including PR triage, model routing, and game loop decision-making, comparing Jev's speed, cost, and reliability against traditional LLM structured outputs.
Duration: 17 minutes 13 seconds.
 ▶
16:14
by ともすた | たにぐち まこと
Makoto Taniguchi demonstrates TypeSafe AI's Jev, explaining its structured probability output, testing criteria and states in the playground, and implementing an inquiry categorization web application.
Duration: 16 minutes 14 seconds.
 ▶
5:17
by Kev Builds Apps
This video shows how Jev acts as a fast tool-routing agent inside the Hyper Edit open-source video editor. It demonstrates invoking media sourcing, dead-air removal via FFmpeg, captioning, and fallback routing to Claude without standard LLM thinking overhead.
Duration: 5 minutes 17 seconds.
 ▶
23:27
by Krish Naik
Krish Naik explains TypeSafe AI's Jev decision model, contrasting its fast probabilistic classification with generative LLM reasoning loops. He walks through conceptual architectural diagrams showing how Jev can handle tool routing, multi-agent dispatch, and post-generation guardrail verification without replacing generative LLMs.
Duration: 23 minutes 27 seconds.
 ▶
24:32
by Kristiyan Stoyanov
Kristiyan Stoyanov demonstrates TypeSafe's Jev model through direct API queries, illustrating its noul, choice, and score question types. He then showcases two end-to-end implementations: dynamic routing between local Qwen and hosted Claude Sonnet, and multi-agent pull request triage evaluating comment severity and relevance.
Duration: 24 minutes 32 seconds.
 ▶
9:14
by LangChain
LangChain product manager Sydney introduces Jev, a System 1 decision model from TypeSafe AI. The video covers how Jev handles parallel typed queries (choice, score, boolean) directly on structured state, contrasting it with LLMs and demonstrating harness use cases like model routing, risky tool call gating, and judge-based evals.
Duration: 9 minutes 14 seconds.
 ▶
2:22:22
by Latent Space
TypeSafe CEO Diogo Almeida discusses Jev’s machine-oriented API, the distinction between assistance and automation, and why he favors small, testable decisions over long conversational prompts. The interview also explores external memory and coordination in multi-agent coding systems.
Duration: 142 minutes 22 seconds.
 ▶
5:31
by Marc De Fanti
This German-language tutorial introduces Jev by TypeSafe AI, framing it as a fast System 1 model that outputs classifications, scores, and probabilities instead of generative prose. It covers query structures, pricing, and how confidence scores enable automated routing workflows alongside LLMs.
Duration: 5 minutes 31 seconds.
 ▶
21:28
by Matheus Battisti - Hora de Codar
This Portuguese-language tutorial demonstrates integrating Jev alongside DeepSeek to audit legal contracts. It covers sequential question-by-question API calls, confidence cutoff thresholds for manual review, and user-configurable risk checklists.
Duration: 21 minutes 28 seconds.
 ▶
12:10
by Mohamed Naji Aboo
Mohamed Naji Aboo introduces TypeSafe AI's Jev model as a fast System 1 decision engine. He walks through the Python SDK using Noul, Choice, and Score in a single API call to classify customer support message topics, tone, and urgency.
Duration: 12 minutes 10 seconds.
 ▶
13:11
by Moon Dev
Moon Dev evaluates Jev for crypto trading pipelines, contrasting single forward-pass parallel classification with generative LLMs. He reviews latency, context, and calibration claims, highlights arithmetic limitations, and shows how to run Jev in shadow mode.
Duration: 13 minutes 11 seconds.
 ▶
17:40
by Niklas Hansen
Niklas Hansen explains Jev's structured decision outputs (Choice, Score, Noul) and demonstrates six practical use cases: agent model routing, batch email classification, browser automation, lead scoring, custom RAG reranking, and coding assistant skills. He evaluates Jev against GPT-4o-mini and the local Laya alternative, highlighting realistic performance limits and failure modes.
Duration: 17 minutes 40 seconds.