What it does
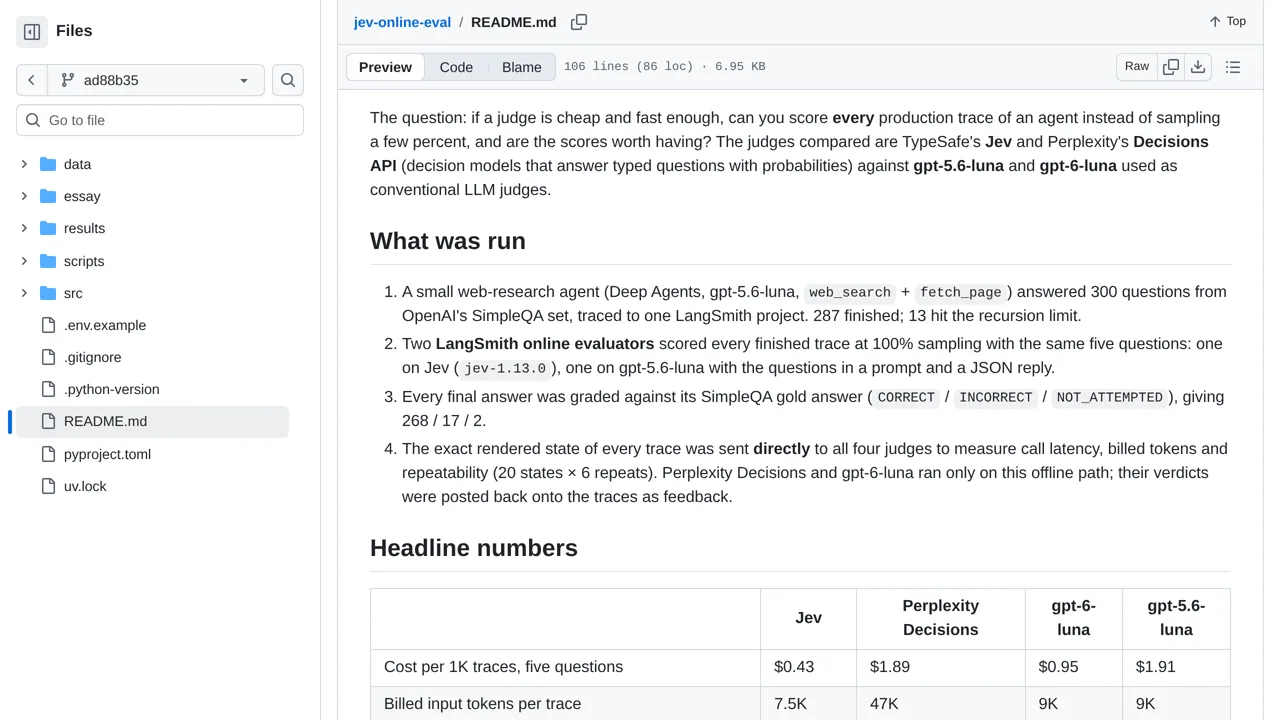
The author reports Jev flagged two of seventeen wrong answers at a 0.5 cutoff. Saved aggregate results are public, but the advertised per-run datasets are absent and reference grading used another model, not people.
Benchmarks & research
Compare Jev and other judges on a web-research agent’s answers, separating direct-call speed from the wait for scores in LangSmith.
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
The author reports Jev flagged two of seventeen wrong answers at a 0.5 cutoff. Saved aggregate results are public, but the advertised per-run datasets are absent and reference grading used another model, not people.
Borrow the method to compare AI services that review your app’s answers. Give each reviewer the same saved question, answer and tool results, then compare its ratings with answers checked separately. Measure how long the reviewer takes and how long you wait to see its score as two different things.
A developer can inspect the saved review questions and comparison code, but the listed files of individual runs are missing. Rebuilding the study needs several paid services and shares agent records with them. Another AI graded the answers used for comparison, not people. Low scores were feedback; they did not block answers.