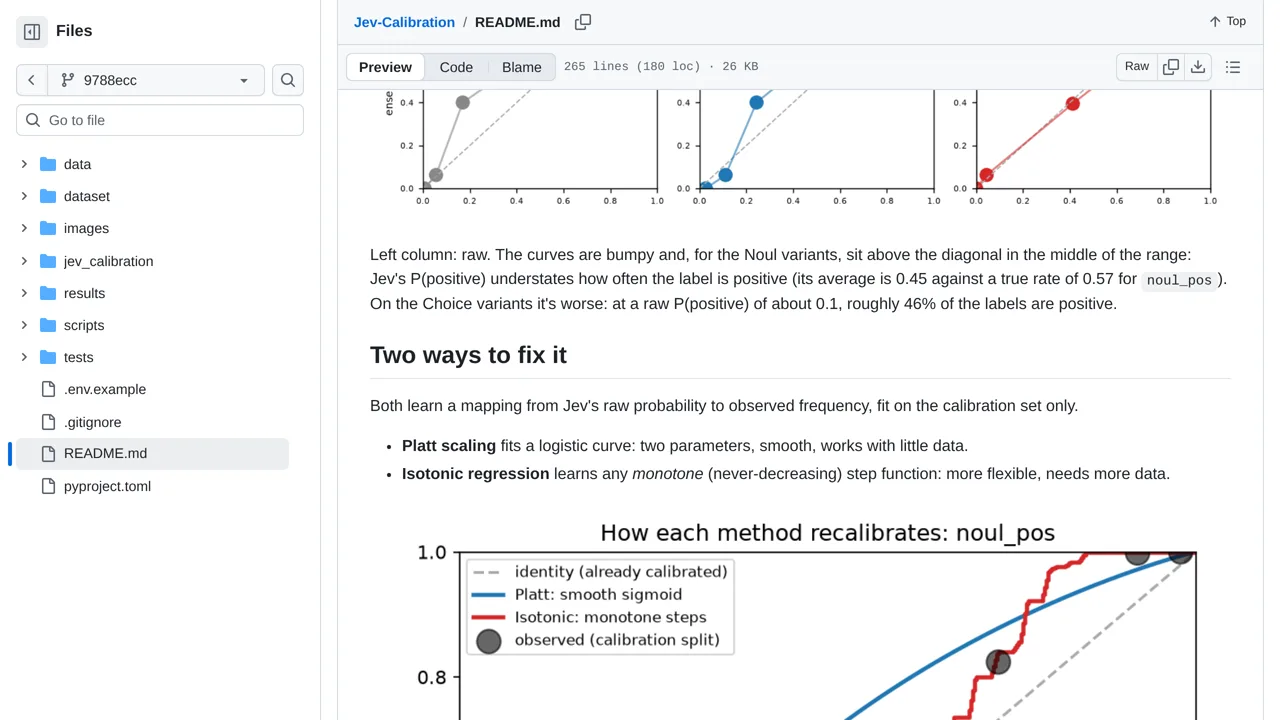
The maker reports a smaller calibration gap after fitting a flexible correction. The study uses one constructed dataset, includes arbitrary neutral labels and compares many variants on the same test set; its best results may be optimistic.
How you can use it
If Jev says a message has an 80% chance of being positive, check whether that matches real examples. Your developer can adjust those estimates using messages you have labeled. Keep a separate group to test the change. Use messages from your own task, rather than this study's made-up ones.