What it does
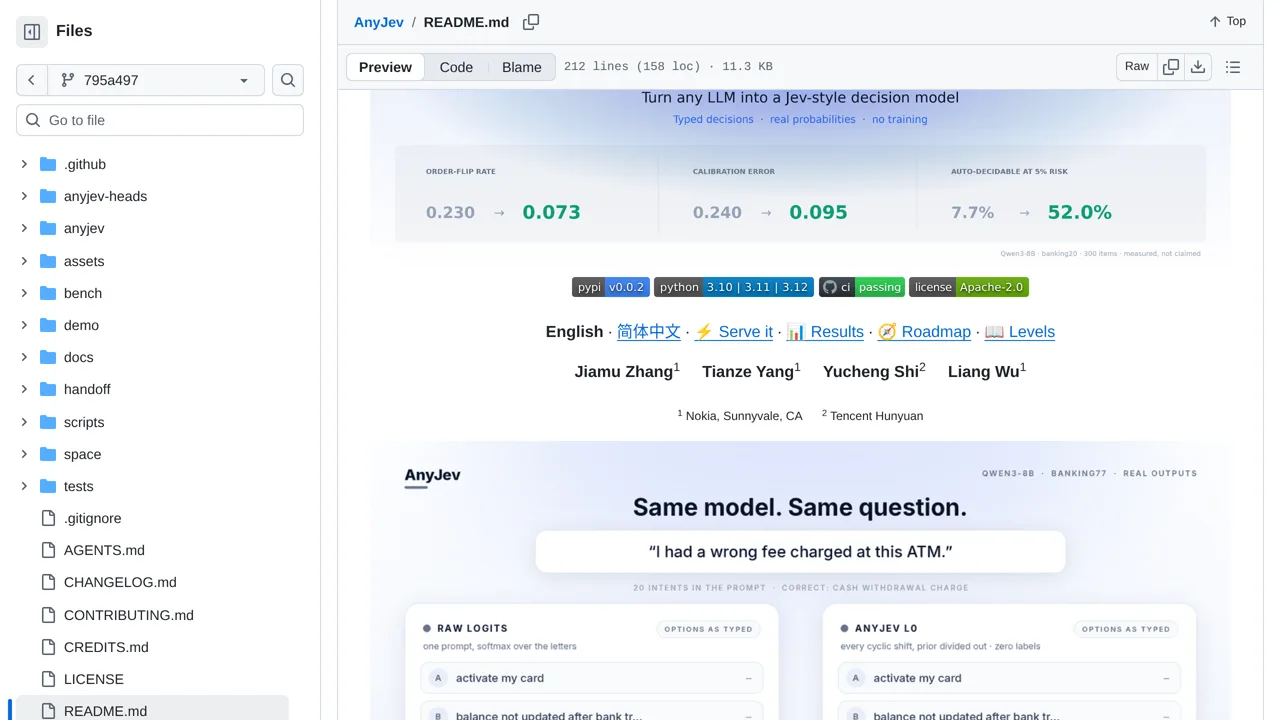
Adds typed probability readouts and calibration heads to ordinary language models, with Jev-style evaluations and saved results.
Benchmarks & research
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
Adds typed probability readouts and calibration heads to ordinary language models, with Jev-style evaluations and saved results.
Your developer can use this code to test how an AI makes choices. They can give the included demo a customer ticket and a list of categories. The tool then guesses the correct category and reports how sure it is.
To start without a heavy download, they can run a fast test model. This project is a research experiment built to measure accuracy. It needs hundreds of previous examples to reach its best performance. Your developer must adapt the code before using it in a live app.