What it does
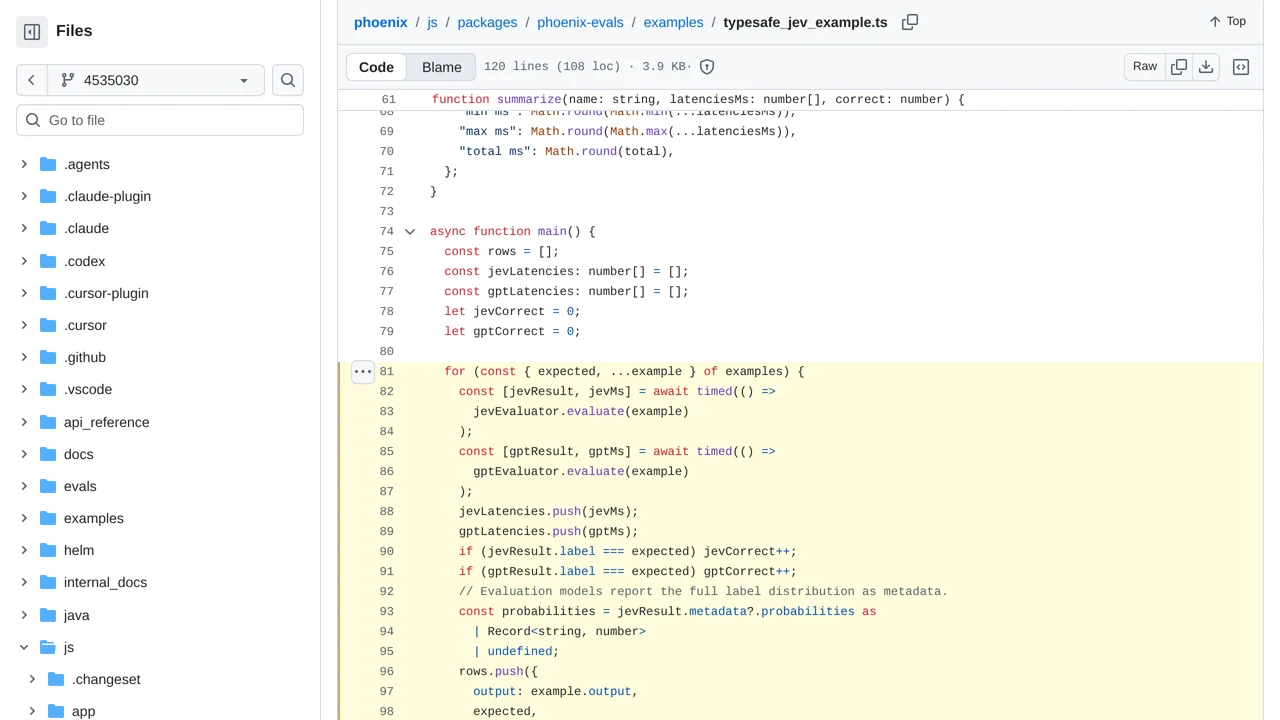
For each case it records Jev's label and probability, then builds correctness and latency tables. Running the example requires a TypeSafe key.
Benchmarks & research
A Phoenix Evals example pits Jev against a small grounded-versus-hallucinated answer benchmark.
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
For each case it records Jev's label and probability, then builds correctness and latency tables. Running the example requires a TypeSafe key.
Start by collecting sample questions with their source documents. Add answers you have already marked by hand as truthful or made up. A developer can write a script that sends these texts to TypeSafe AI, which judges whether each answer matches the facts.
The script then compares those AI decisions and response speeds directly against your original notes. Running this check requires an access key from TypeSafe. Because an automated evaluation can still make mistakes, a person should check important results.