JevMade

Sign in
← Back to experiments

Benchmarks & research

Can you fool Jev?

Hüseyin Babal wrote 1,000 trick questions, laced with sarcasm, hidden severity and planted instructions, and sent the same requests to Jev and three smaller local models.

Source screenshot of Can you fool Jev?
SOURCE SCREENSHOTFull screenshot ↗

What it does

Jev got the most right, while the local models struggled most with 1-to-10 scores. Every question, label and reply is public, so anyone can check a result or rerun it against another model. He wrote and labelled the questions himself, calls 42 labels debatable, and most of the set is customer messages.

How you can use it

If you are picking a decision model for customer messages, this gives you a thousand awkward examples to test it with. Look for the kinds of trick that match your own messages, such as sarcasm or a serious problem described politely, and see which model stays right, and how confident each one was when it was wrong.
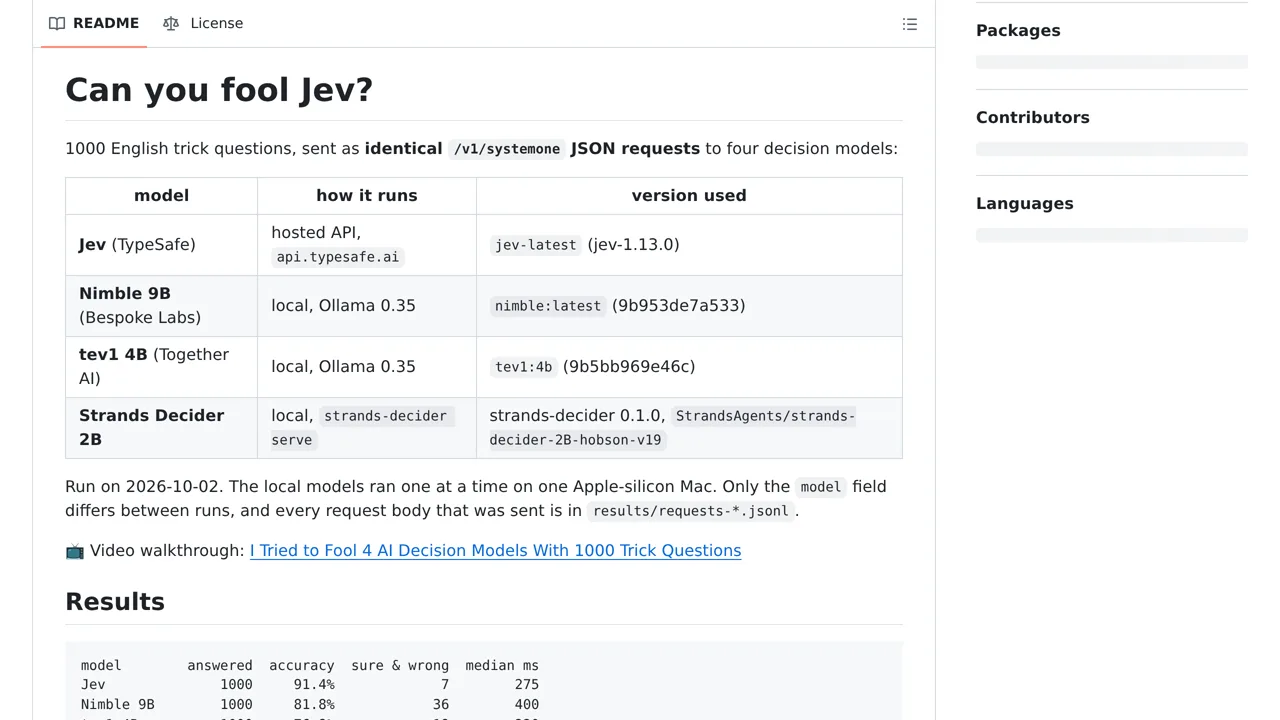
Maker-reported (not independently measured by JevMade): Hüseyin Babal reports accuracy of 91.4% for Jev 1.13.0, 81.8% for Nimble 9B, 76.8% for tev1 4B and 64.7% for Strands Decider 2B, each run once with default settings on 2 October 2026. · He counts wrong answers given with at least 90% probability as 7 for Jev, 36 for Nimble, 19 for tev1 and 4 for Strands; median latencies were 275, 400, 220 and 77 ms, with Jev's including the network round trip. · 843 of the 1,000 questions are customer messages; the other categories have 19 to 35 questions each, which he says to read as a direction rather than a ranking.

Primitives
choice, noul, score
Platform
Python
Added
Project created

Keep this for later

Sign in to bookmark experiments, guides and videos, and keep notes only you can see.

Continue to sign in

We’ll bring you back to this listing.