What it does
The authors report faster responses in their runs, but no general cost advantage over GPT-6 Luna batch pricing. Calibration gains vary by comparator and task. This is an unreproduced preprint, not a peer-reviewed result.
Benchmarks & research
Compare Jev with human reference labels and language models across seven political-science replications, including annotation, scaling and probability calibration.
Only you can see your notes.
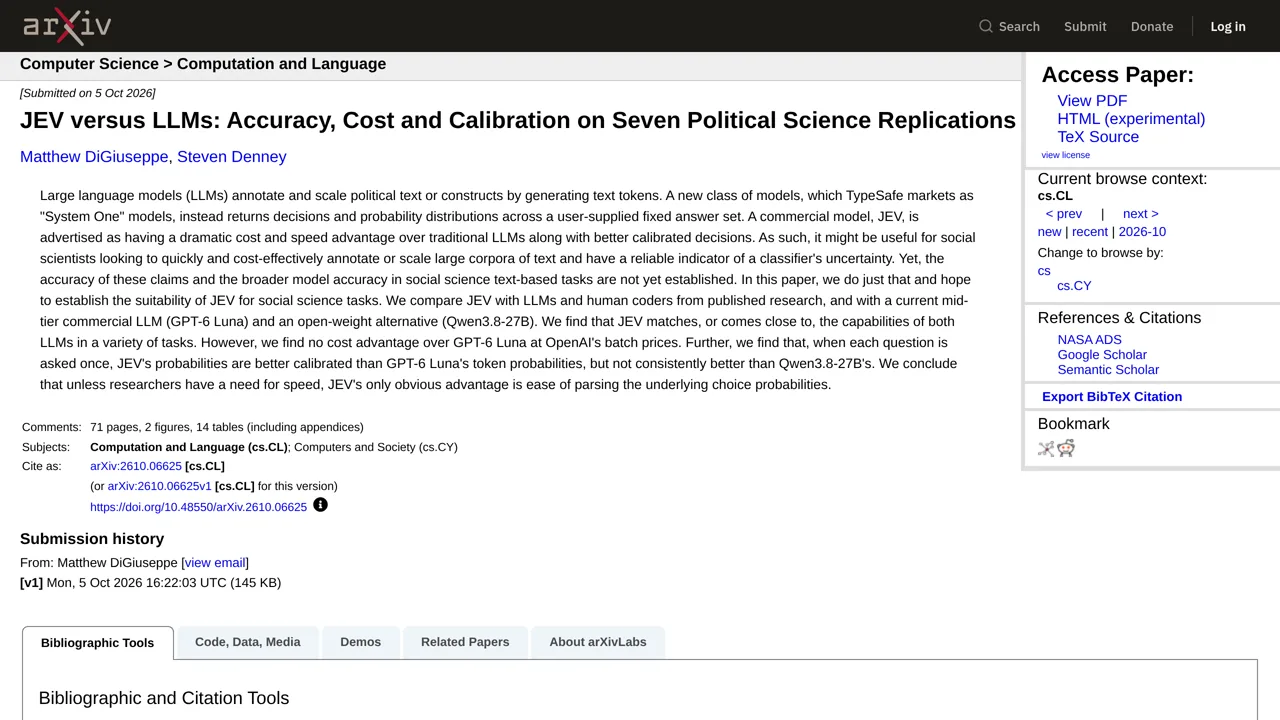
Screenshot unavailable. Open the experiment ↗
The authors report faster responses in their runs, but no general cost advantage over GPT-6 Luna batch pricing. Calibration gains vary by comparator and task. This is an unreproduced preprint, not a peer-reviewed result.
You can borrow this testing approach to evaluate AI services for your own projects. A developer can gather a set of text documents that people have already sorted. They can then send these same documents to several different AI tools to compare the results.
You can score each tool on how closely its answers match the human choices. You can also test whether a service gives a reliable confidence score when it is unsure. This helps you choose the best option before you sort a large batch of new information.