What it does
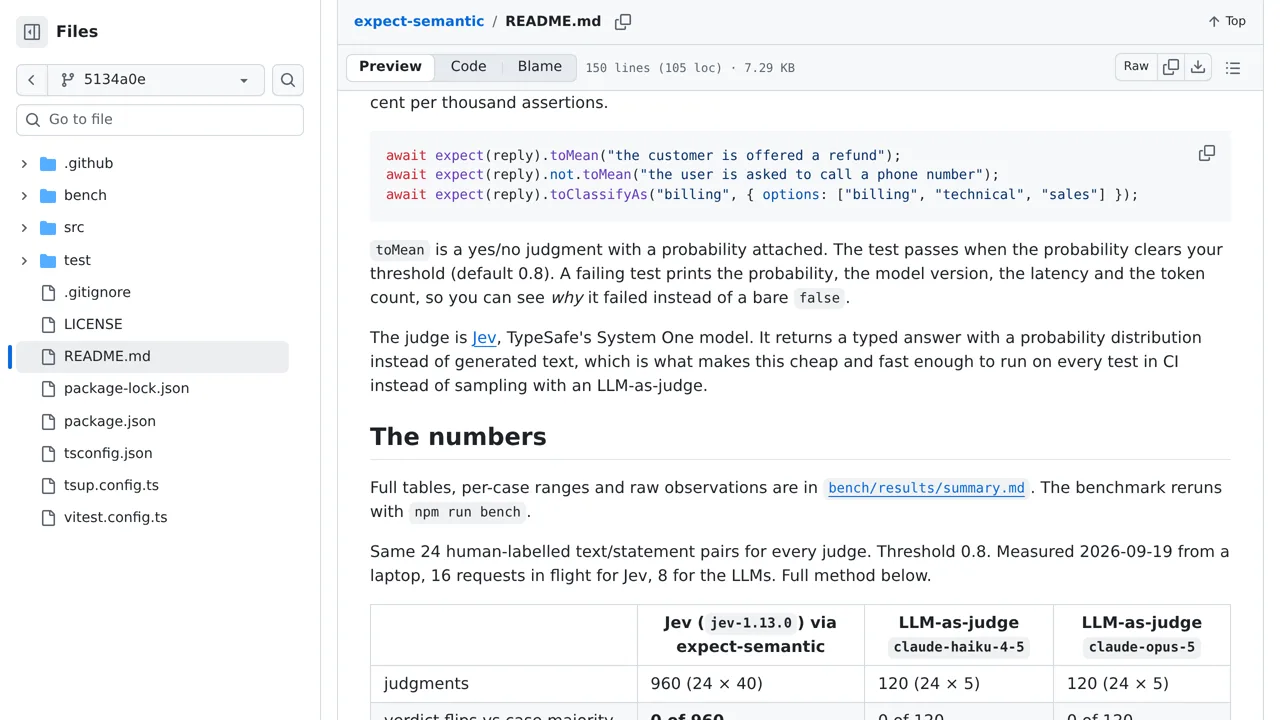
The maker's small benchmark separates Jev from Claude on speed and cost, not accuracy: all three judges got every case right.
Benchmarks & research
Test what an answer means, not just which words it contains, with Jev assertions for Vitest and Jest.
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
The maker's small benchmark separates Jev from Claude on speed and cost, not accuracy: all three judges got every case right.
Use this when your app's reply can have different wording but must mean the same thing. Ask a developer to add a check such as whether a reply offers a refund. Jev, an outside AI service, judges the meaning. This can catch changes that a search for exact words would miss.
Try clear example replies first, then include awkward or doubtful ones. Answers near the pass mark can change between runs. These checks do not prove every reply is correct; keep ordinary tests for things that code can check exactly.