What it does
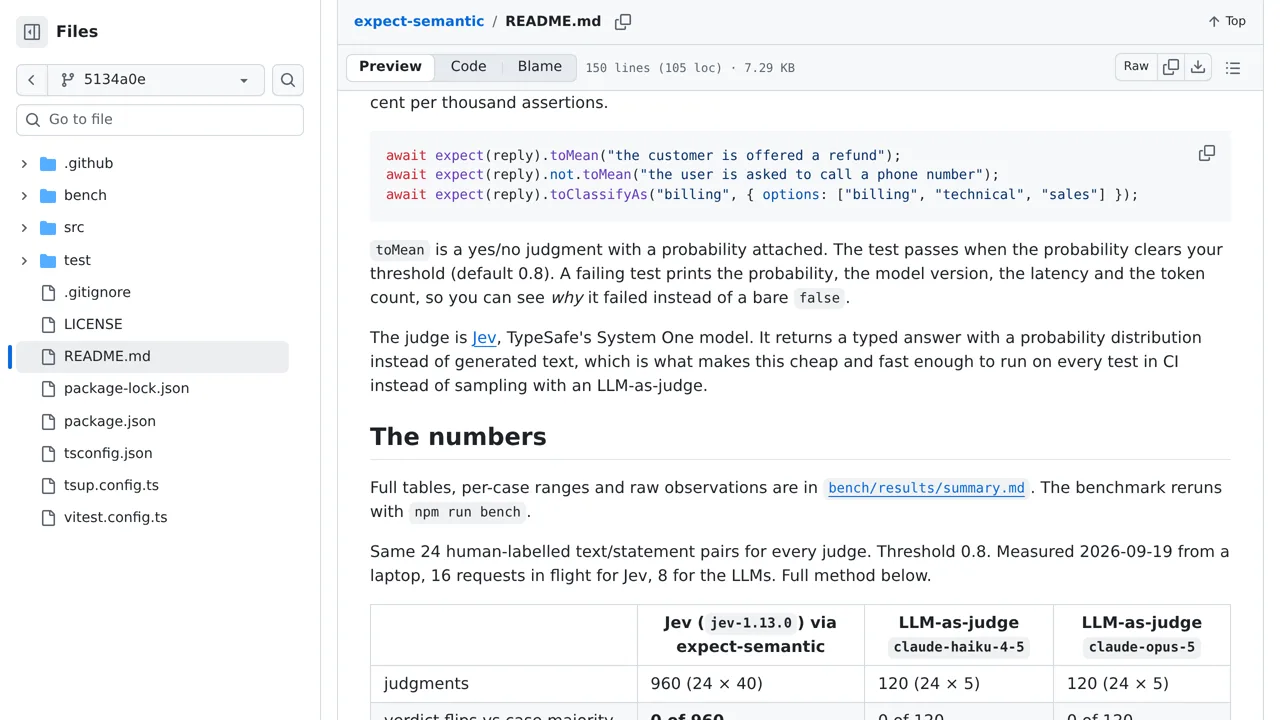
The maker's small benchmark separates Jev from Claude on speed and cost, not accuracy: all three judges got every case right.
Maker-reported (not independently measured by JevMade): Nine hundred and sixty judgments over 24 labelled pairs at threshold 0.8, with 0 verdict flips and a p50/p95 of 359/466 ms (author-reported) · $0.012 per 1,000 judgments against $0.279 for claude-haiku-4-5 and $1.923 for claude-opus-5 at list price (author-reported) · The sarcasm case sat at 0.01 across all 40 runs and the double-negation case at 0.10 to 0.14 (author-reported)
- Primitives
- noul, choice
- Platform
- TypeScript
- Added
- Project created
- GitHub stars
- 0 · snapshot 2026-09-22
Source checked 2026-09-22 — opened the primary source directly.