What it does
The label sets were fixed before the first model run, so the answers could not shape the test.
Benchmarks & research
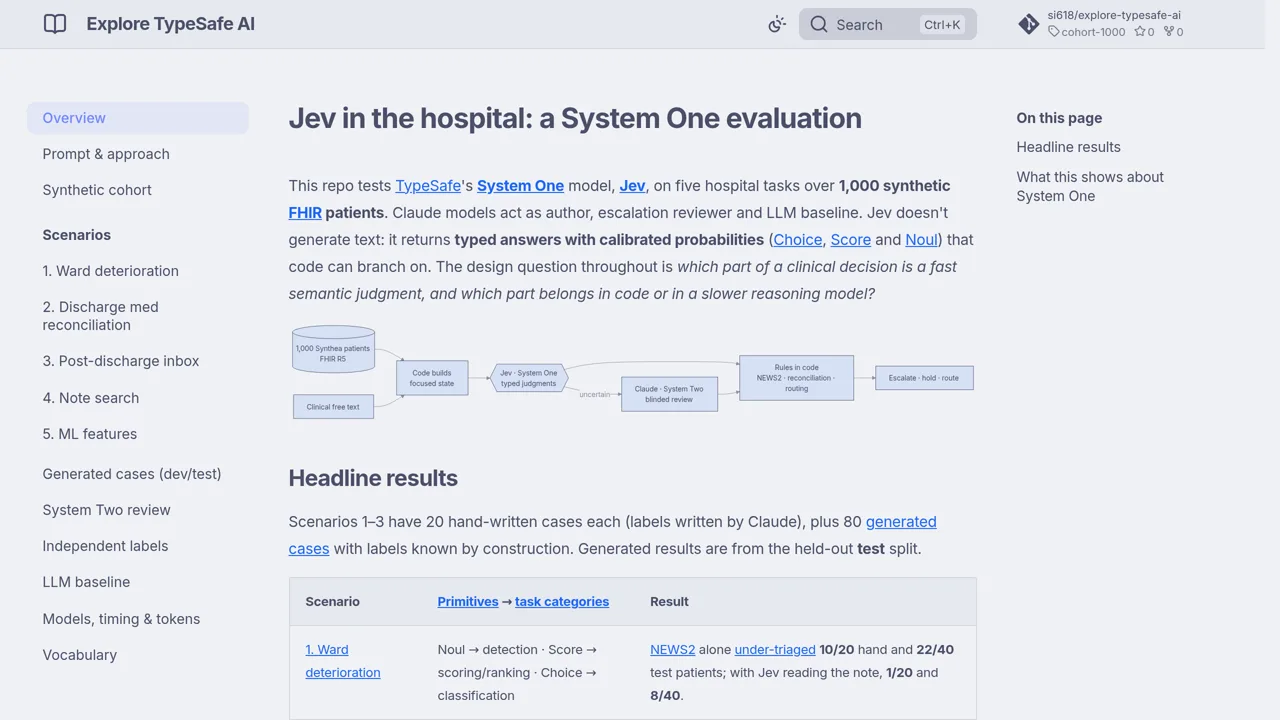
Five hospital tasks, a thousand synthetic patients, and Jev answering every one, with Claude writing the scenarios and reviewing the results.
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
The label sets were fixed before the first model run, so the answers could not shape the test.
For a healthcare project, borrow the way this study fixes expected answers before testing AI. Start with its made-up patient cases, not real records. A developer can compare new answers with the saved ones. Results on made-up patients are not proof of safety in care; qualified people must still make real clinical decisions.