What it does
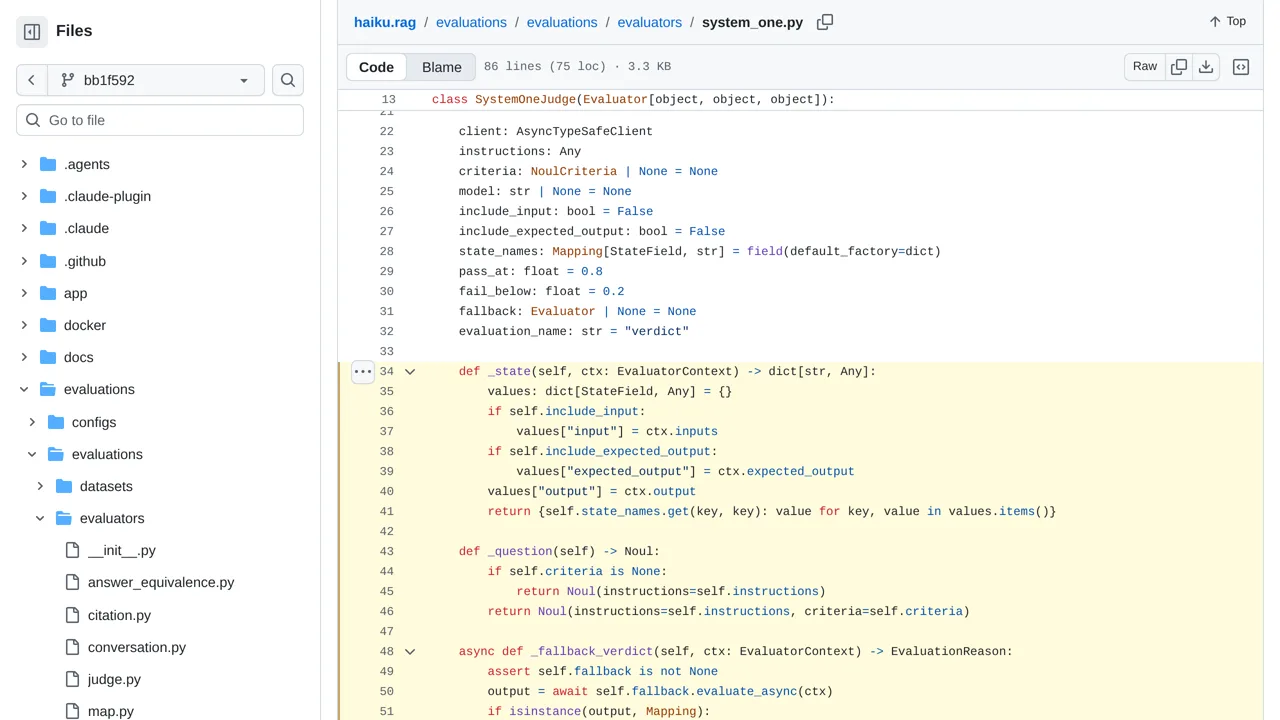
It packages the input, expected answer, and generated answer into one Noul rubric. Uncertain or failed verdicts can be handed to a configured fallback judge.
Benchmarks & research
haiku.rag provides a reusable System One judge for benchmark verdicts such as whether two answers are equivalent.
Screenshot unavailable. Open the experiment ↗
It packages the input, expected answer, and generated answer into one Noul rubric. Uncertain or failed verdicts can be handed to a configured fallback judge.
A developer can use this code to test if a chat tool gives correct answers. The software compares a new response against a known good answer. This checks if the two messages mean the same thing. The app groups the question and both answers together for an AI to review.
If the first review fails, the app sends the texts to a second reviewer. The default setup runs the AI directly on your own computer. It does not require an access key that connects the software to an outside service.