JevMade

Sign in
← Back to experiments

Benchmarks & research

H2O-Lightning-4B

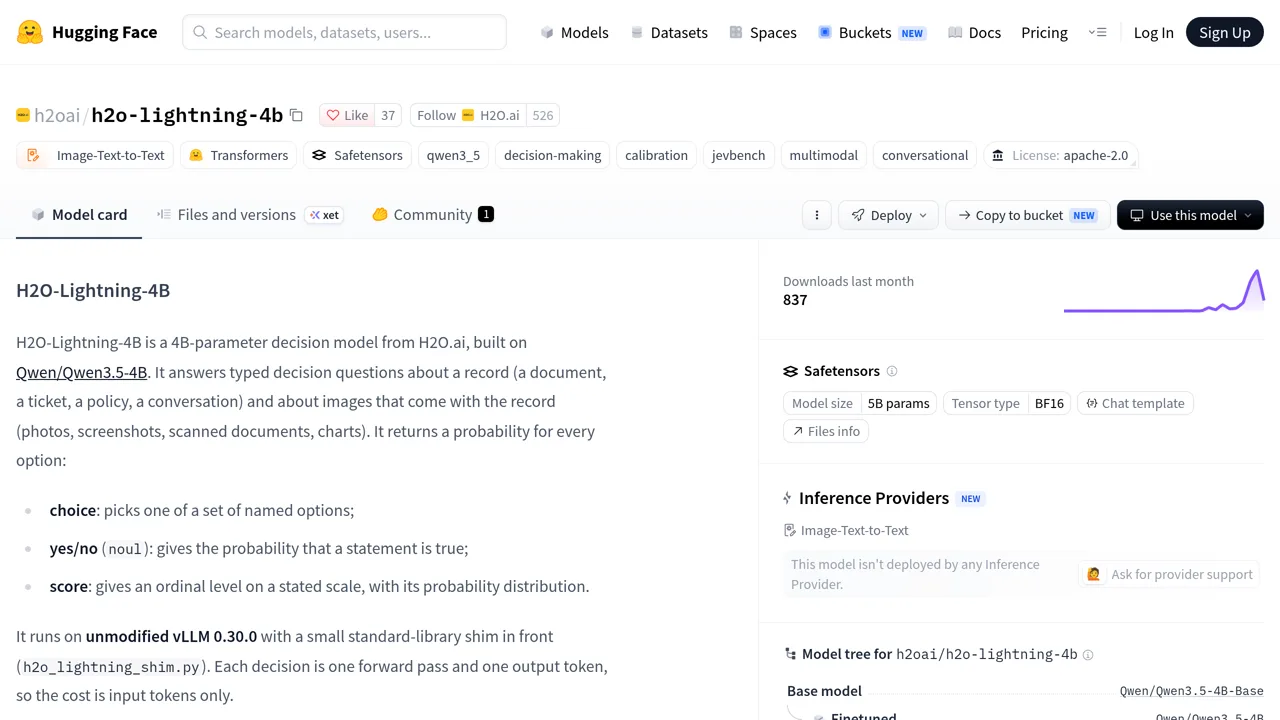
H2O.ai's open 4B decision model, built on Qwen3.5-4B, answers choice, yes/no and score questions about records and the images that come with them.

Source screenshot of H2O-Lightning-4B
SOURCE SCREENSHOTFull screenshot ↗

What it does

It runs on stock vLLM behind a small shim that serves Jev-format requests, and each answer takes one forward pass and one output token. H2O's recorded demos show it checking claims against a written policy, guiding browser agents and choosing moves in a Freedoom level, where a thin controller does the aiming.

How you can use it

H2O-Lightning-4B suits large piles of routine checks run on your own computer, such as whether a claim follows a written policy or what total a photographed receipt shows. Each answer comes with how sure the model is, and H2O lists how many answers would be passed to a person at different levels of certainty.
Maker-reported (not independently measured by JevMade): H2O's card reports first place among open-weight systems on Benchmark Heaven's JevBench v1.6.1 composite, 72.5 against 71.5 for Jev 1.13.0 (read 7 October 2026). On 10 October the board showed it first of the open-weight systems and second overall behind the hosted Sage 1.3.0 (74.05), with Jev ahead on the intelligence axis, 63.6 against 60.0. · H2O reports 205 of 231 correct on JevBench's public items with JevBench's own command-line tool; the board measured a 29 ms median per decision on an RTX 5090.

Primitives
choice, noul, score
Platform
Python / vLLM / Hugging Face
Added
Project created

Keep this for later

Sign in to bookmark experiments, guides and videos, and keep notes only you can see.

Continue to sign in

We’ll bring you back to this listing.