What it does
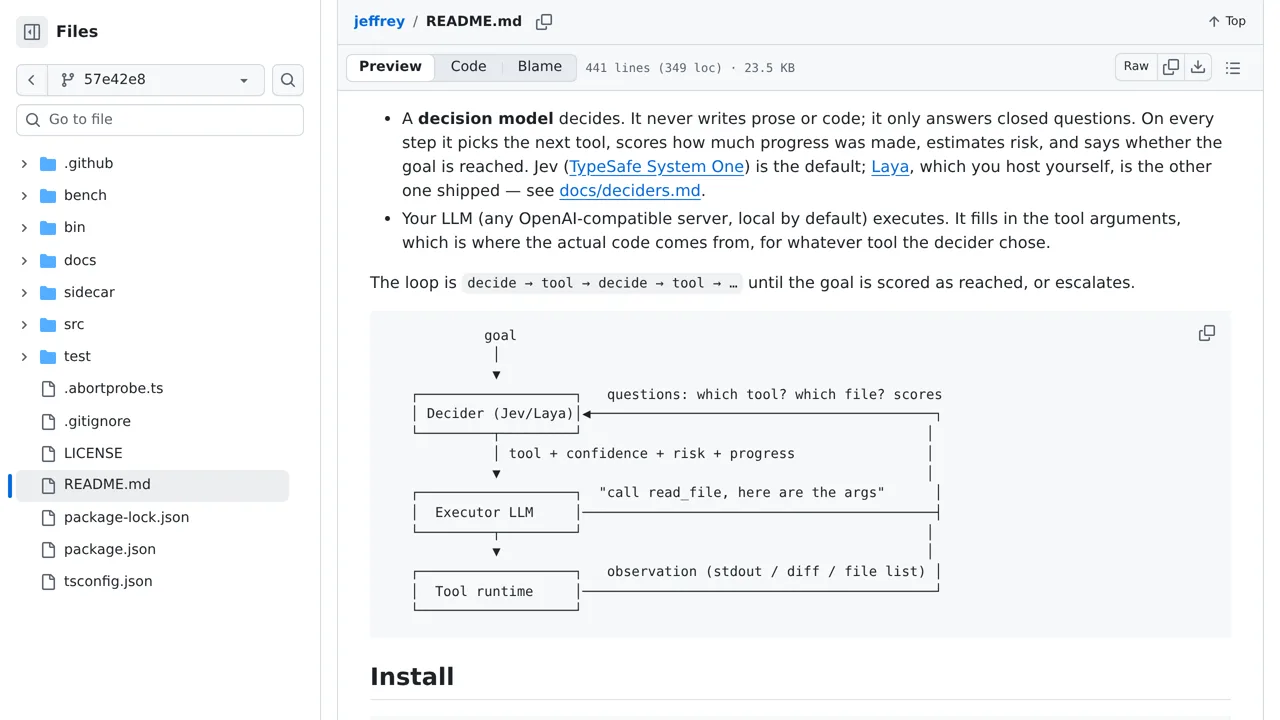
The loop runs decide, tool, decide, tool until the goal is scored reached or it escalates, and a benchmark suite scores a run against hidden tests and a reference directory.
Agent tooling
A coding-agent CLI that splits the work: a decision model picks the next tool, scores progress and judges whether the goal is reached, while an LLM only fills in arguments and writes code.
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
The loop runs decide, tool, decide, tool until the goal is scored reached or it escalates, and a benchmark suite scores a run against hidden tests and a reference directory.
For a code change in your app, have a developer try this AI helper. The developer sets it up and limits how many steps it may take. One AI chooses what to do next; another writes the code. Ask the developer to check the changed files with you, even if the helper says the task is finished.