- Primitives
- choice
- Platform
- Python
- Added
- Project created
- GitHub stars
- 1 · snapshot 2026-09-18T22:58:45Z
Source checked 2026-09-19 — opened the GitHub repository directly.
Benchmarks & research
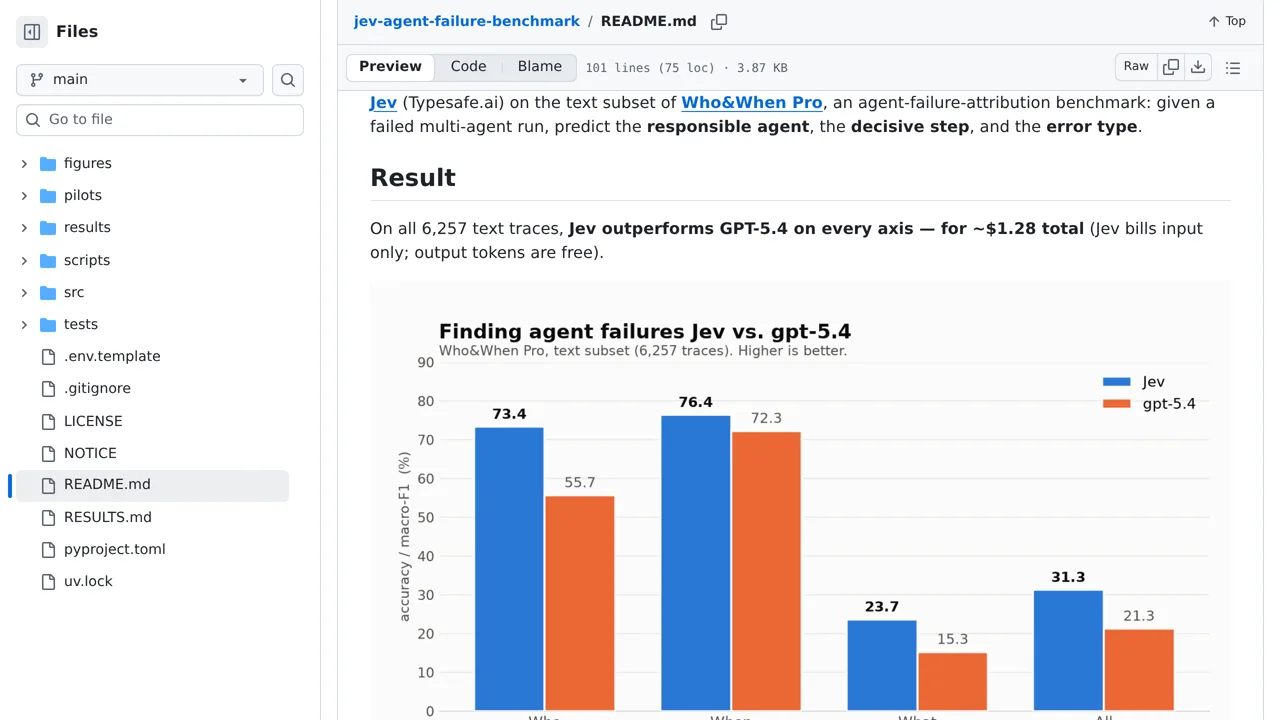
This benchmark compares Jev with a strong language model at attributing agent failures in the text subset of Who&When Pro.
Screenshot unavailable. Open the experiment ↗
Source checked 2026-09-19 — opened the GitHub repository directly.