What it does
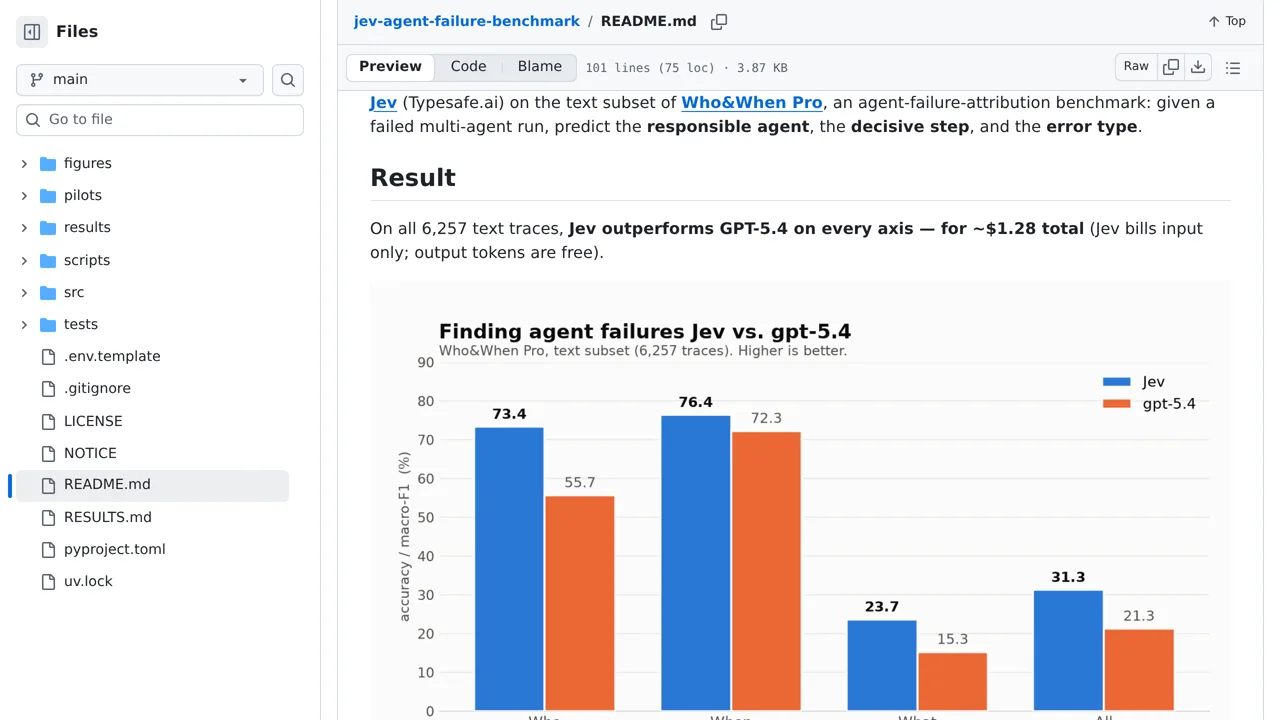
This benchmark compares Jev with a strong language model at attributing agent failures in the text subset of Who&When Pro.
Benchmarks & research
Screenshot unavailable. Open the experiment ↗
This benchmark compares Jev with a strong language model at attributing agent failures in the text subset of Who&When Pro.
Find out who caused a failed AI task, at which step, and what went wrong. Have a developer try this test's small sample and cost estimate before asking Jev, an AI service, to judge the failures. The mistakes were added deliberately, so this is practice for investigating failures, not proof it can explain real incidents.