What it does
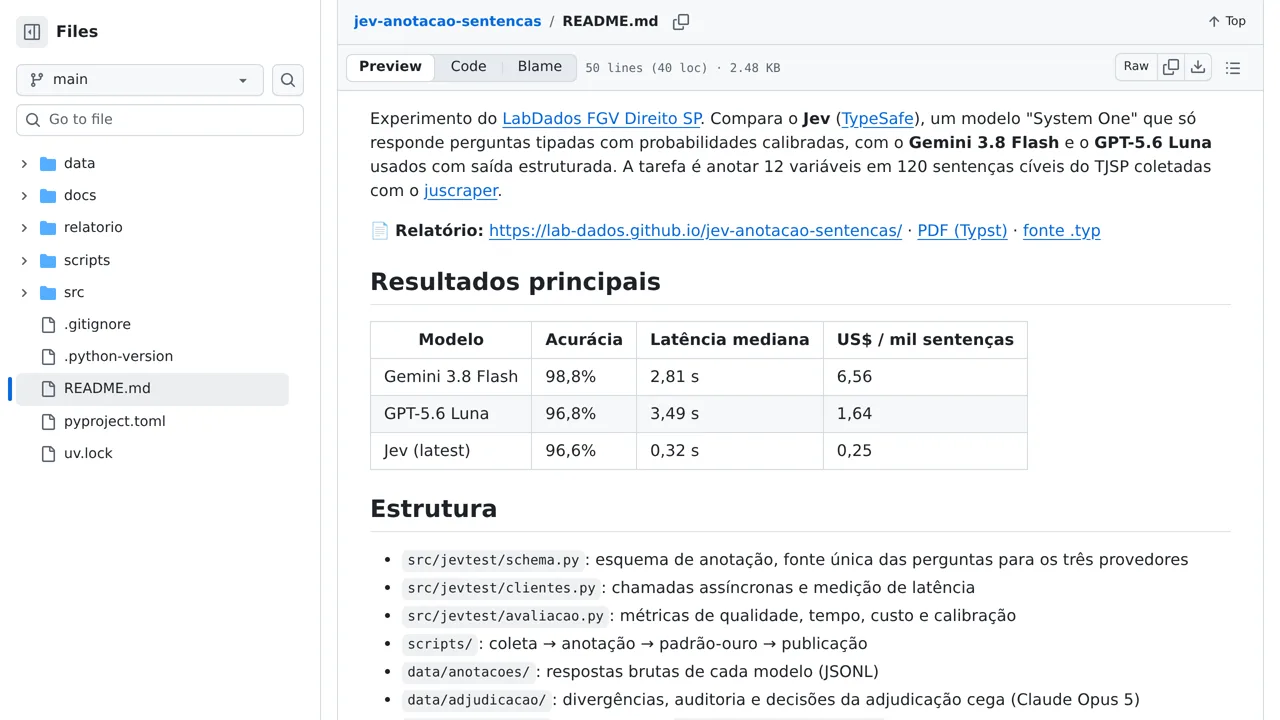
It measures annotation quality, runtime, and cost, with scripts for collecting cases and reviewing model disagreements.
Benchmarks & research
This benchmark compares Jev, Gemini, and GPT on structured annotation of São Paulo court judgments.
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
It measures annotation quality, runtime, and cost, with scripts for collecting cases and reviewing model disagreements.
To compare AI readers for a legal study, have a developer adapt this project's questions about court rulings. Ask each AI the same questions, then inspect where their answers differ. Compare time and cost as well as correct answers; a fast reader is not necessarily the most accurate one.
The project does not include full ruling texts because of privacy rules. Its code can collect them again, and running the comparison sends them to outside AI services. Make sure you are allowed to share those documents before a developer connects the services.