What it does
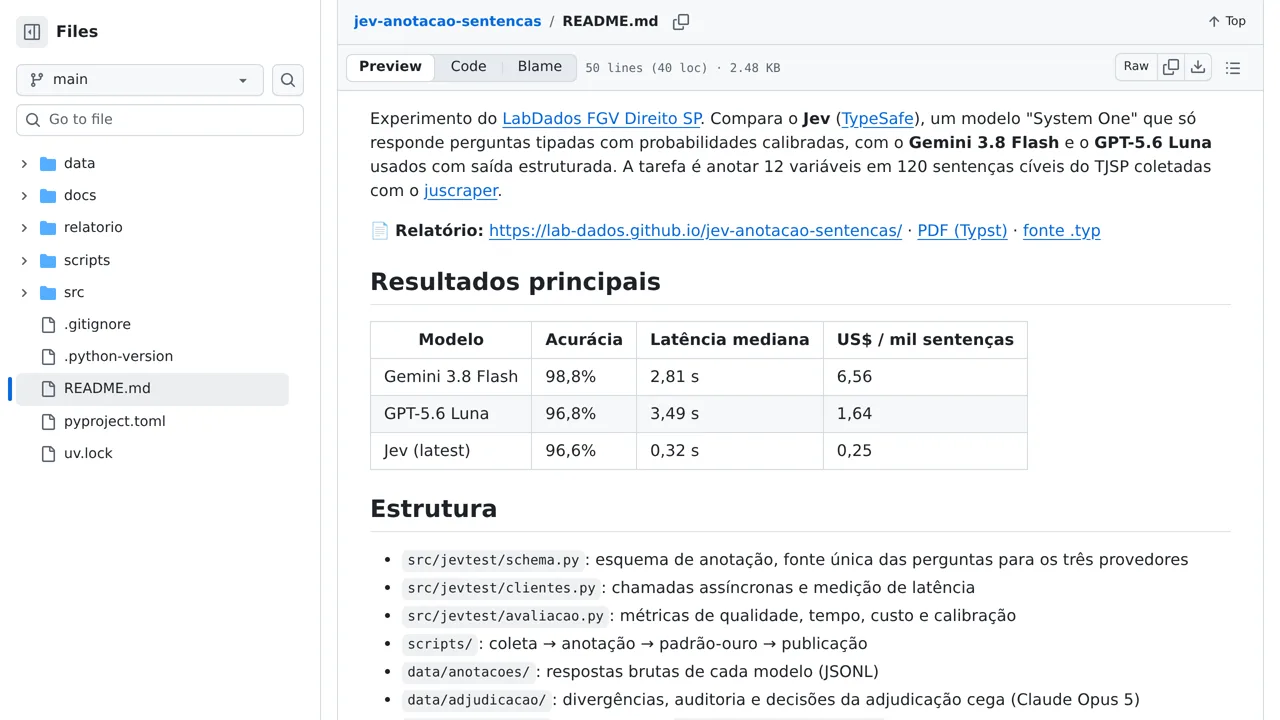
It measures annotation quality, runtime, and cost, with scripts for collecting cases and reviewing model disagreements.
- Primitives
- Not stated
- Platform
- Python
- Added
- Project created
- GitHub stars
- 0 · snapshot 2026-09-18T22:58:45Z
Source checked 2026-09-19 — opened the GitHub repository directly.