What it does
A reproducible evaluation suite measures calibration, selective risk and latency in probabilistic decision models.
Benchmarks & research
Only you can see your notes.
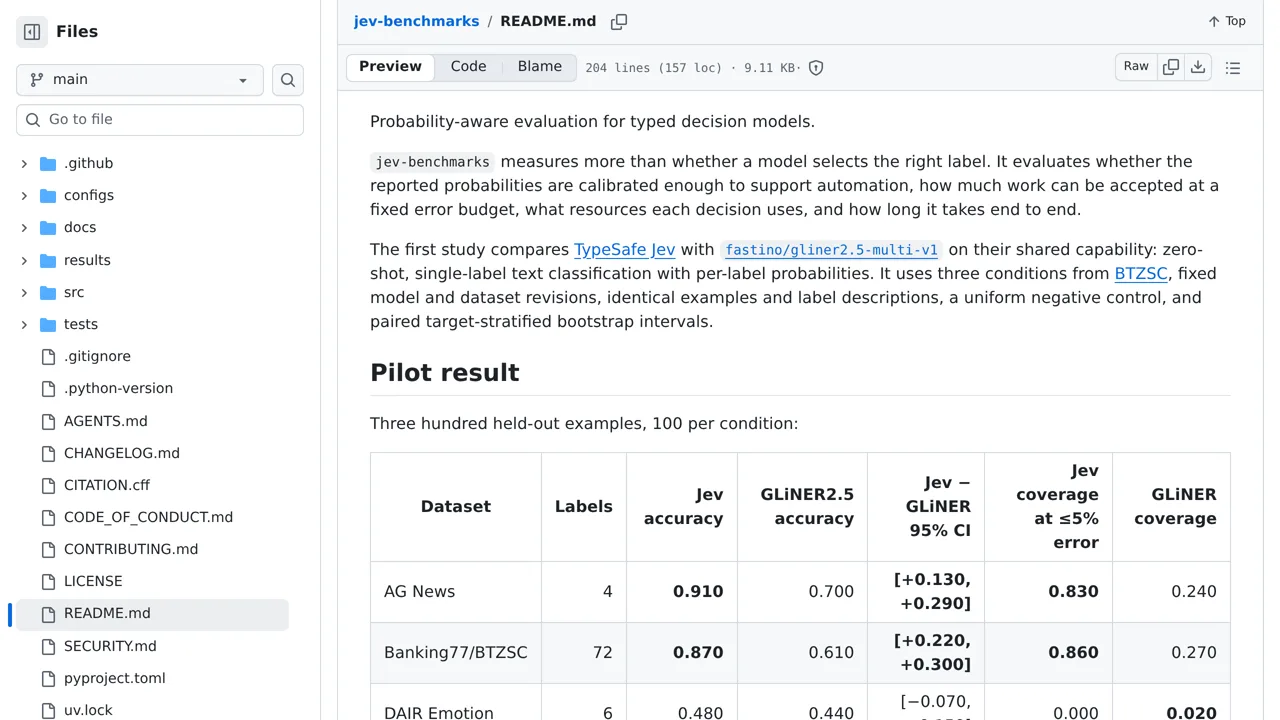
Screenshot unavailable. Open the experiment ↗
A reproducible evaluation suite measures calibration, selective risk and latency in probabilistic decision models.
You can use this suite to see whether an online language model or a local program sorts sentences more reliably. A developer sets up the test on your computer to run its built-in set of sample questions, news items, and emotion labels.
Running the local tool downloads its program files directly to your machine. Testing the TypeSafe service requires an access key provided by that service and sends the test text over the internet. Keep in mind that this small trial only describes pilot patterns, not universal rules.