What it does
The benchmark contains 60 synthetic tourism-photo inquiries in four languages; its live demo intentionally uses a different calling pattern from the measurement protocol.
Benchmarks & research
Compare Jev with general language-model judges on one multilingual booking-inquiry routing task.
Screenshot unavailable. Open the experiment ↗
The benchmark contains 60 synthetic tourism-photo inquiries in four languages; its live demo intentionally uses a different calling pattern from the measurement protocol.
To try this approach, write a list of sample customer messages in different languages and decide which team should handle each one. Your developer can borrow the test setup and replace its original sixty sample tourist inquiries with your examples to test how well different AI models sort your messages.
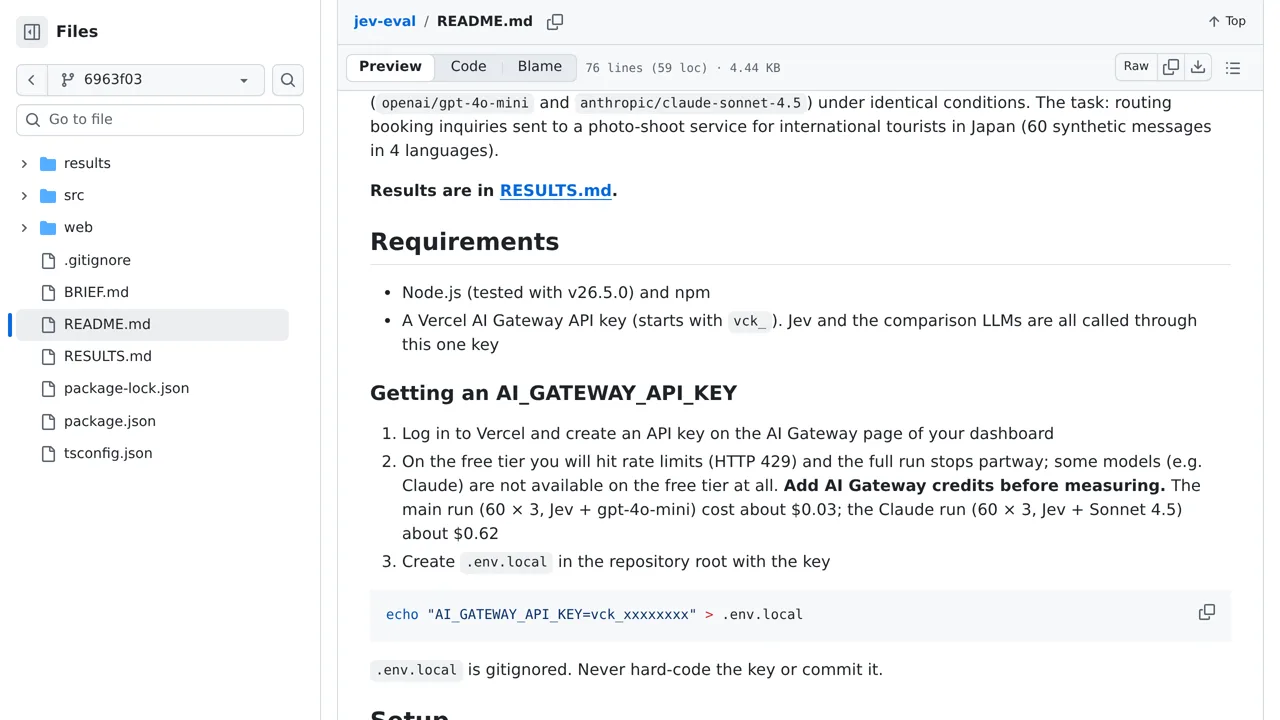
Your developer will need an access key from Vercel with added funds, which authorizes and pays for the external AI services during testing. Remember that this experiment sends all inquiry text to external cloud services, and its built-in results come from a small set of sixty tourism practice cases.