JevMade

Sign in
← Back to experiments

Benchmarks & research

Specialized Decision Models vs. General-Purpose LLMs: Benchmarking Jev Across Knowledge, Reasoning, and Multilingual Tasks

A preprint reports Jev matching frontier models on knowledge and commonsense tests while lagging on mathematical word problems.

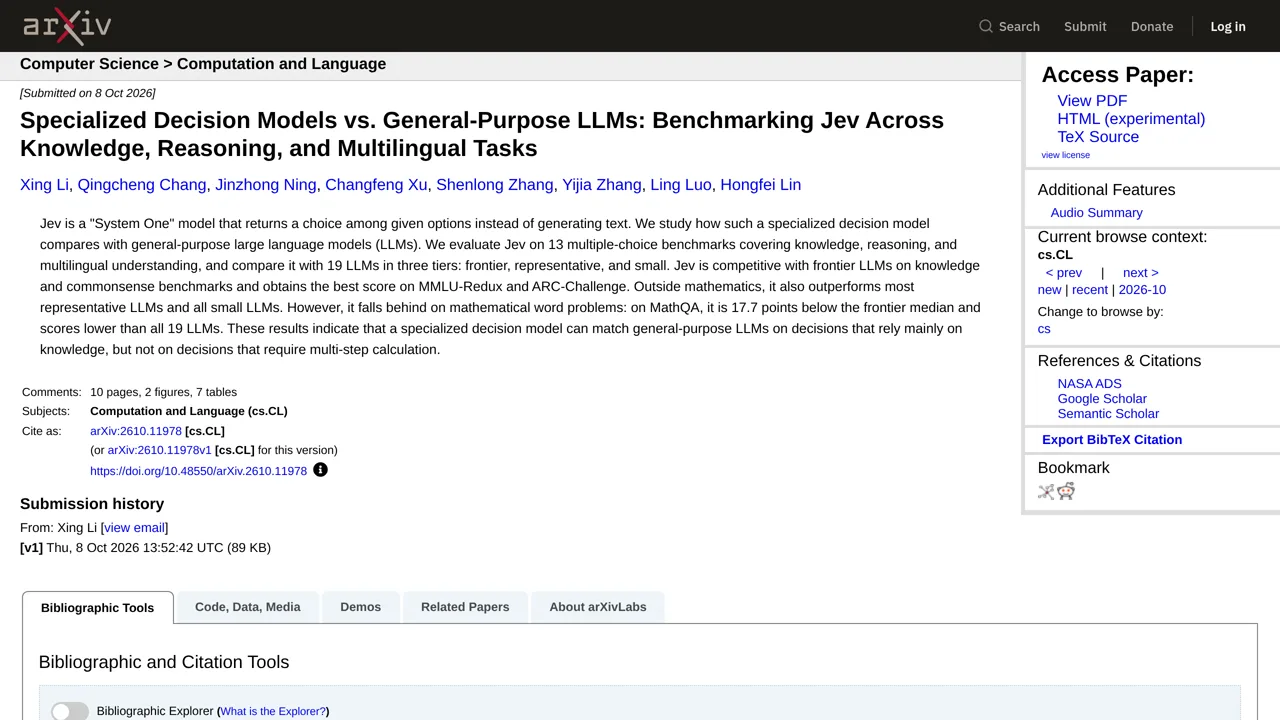
Source screenshot of Specialized Decision Models vs. General-Purpose LLMs: Benchmarking Jev Across Knowledge, Reasoning, and Multilingual Tasks
SOURCE SCREENSHOTFull screenshot ↗

What it does

The researchers note that Jev achieved the highest scores on MMLU-Redux and ARC-Challenge among tested models, but fell 17.7 points below the frontier median on MathQA. The authors acknowledge that differing prompt templates across the published model scores may influence the exact margins.

Keep this for later

Sign in to bookmark experiments, guides and videos, and keep notes only you can see.

Continue to sign in

We’ll bring you back to this listing.