What it does
On 100 queries, Chen Fei reports that Jev ranked relevant Chinese passages above the BM25 word-matching baseline. This was one run through OpenRouter with binary relevance judgments. There is no comparison with a dense neural reranker.
Benchmarks & research
A reproducible Chinese RAG reranking benchmark for Jev on C-MTEB/T2Reranking, featuring hard negatives and cost-capped execution.
Only you can see your notes.
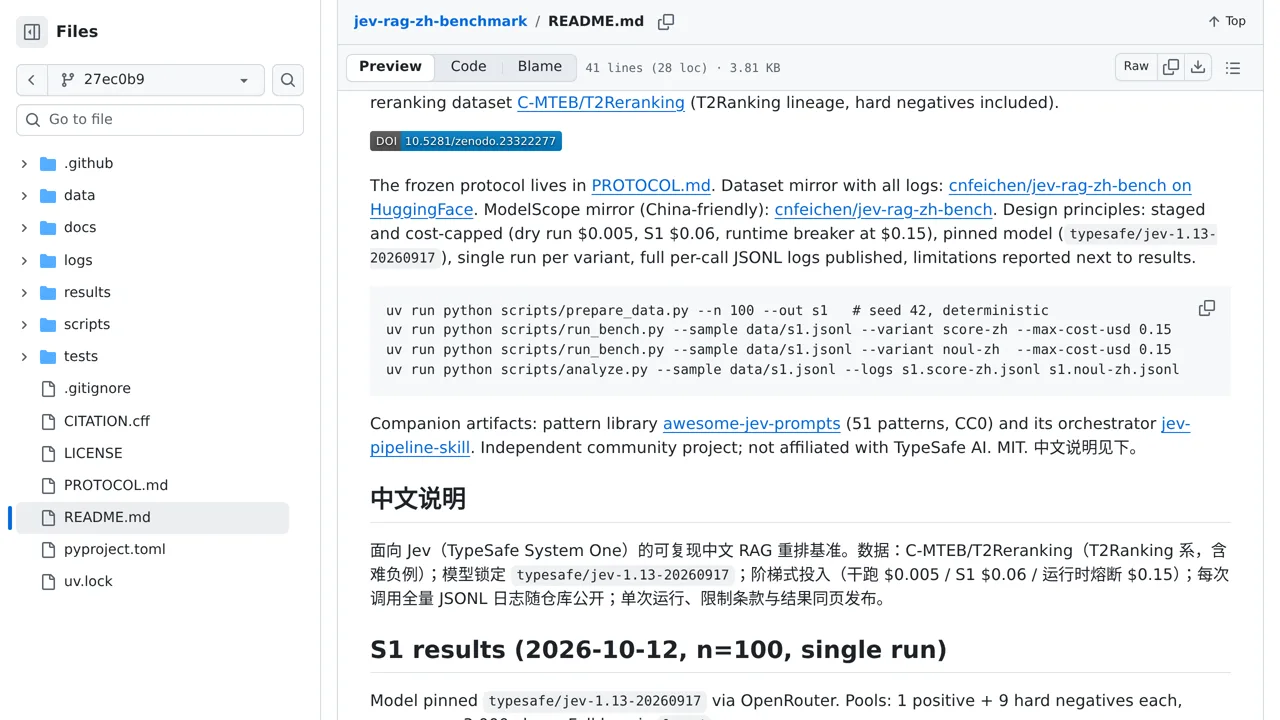
Screenshot unavailable. Open the experiment ↗
On 100 queries, Chen Fei reports that Jev ranked relevant Chinese passages above the BM25 word-matching baseline. This was one run through OpenRouter with binary relevance judgments. There is no comparison with a dense neural reranker.
For each query, the scripts present one relevant Chinese passage alongside nine difficult alternatives. They ask Jev to judge or rate relevance and compare the resulting order with word matching. Fixed inputs, saved answers and spending limits make it easier for others to check the reported comparison.