What it does
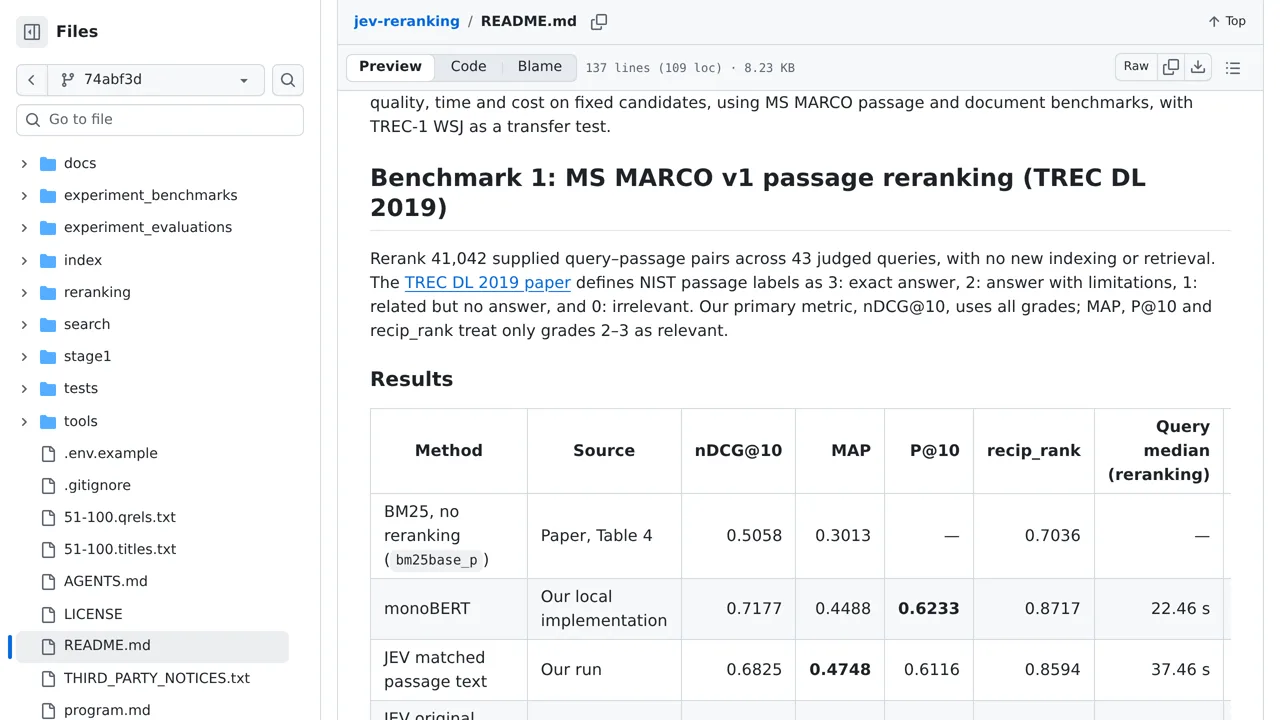
It compares against a local monoBERT reranker and published baselines on the same candidates. A complete Jev run cost $0.762991 where monoBERT cost nothing but compute.
Benchmarks & research
Reranks fixed MS MARCO candidate sets by asking Jev one relevance question per query and document pair, then scores the runs with trec_eval.
Screenshot unavailable. Open the experiment ↗
It compares against a local monoBERT reranker and published baselines on the same candidates. A complete Jev run cost $0.762991 where monoBERT cost nothing but compute.
If your app has search results, you can test different tools that reorder them. Give each tool the exact same starting list of text. Then, check if the new order puts the best answers at the top. This keeps the comparison fair for each tool.
A developer can review the saved test data and commands to get started. They can then adapt this testing approach for your project. This code only scores an existing list of answers. It is not a complete search system on its own.