What it does
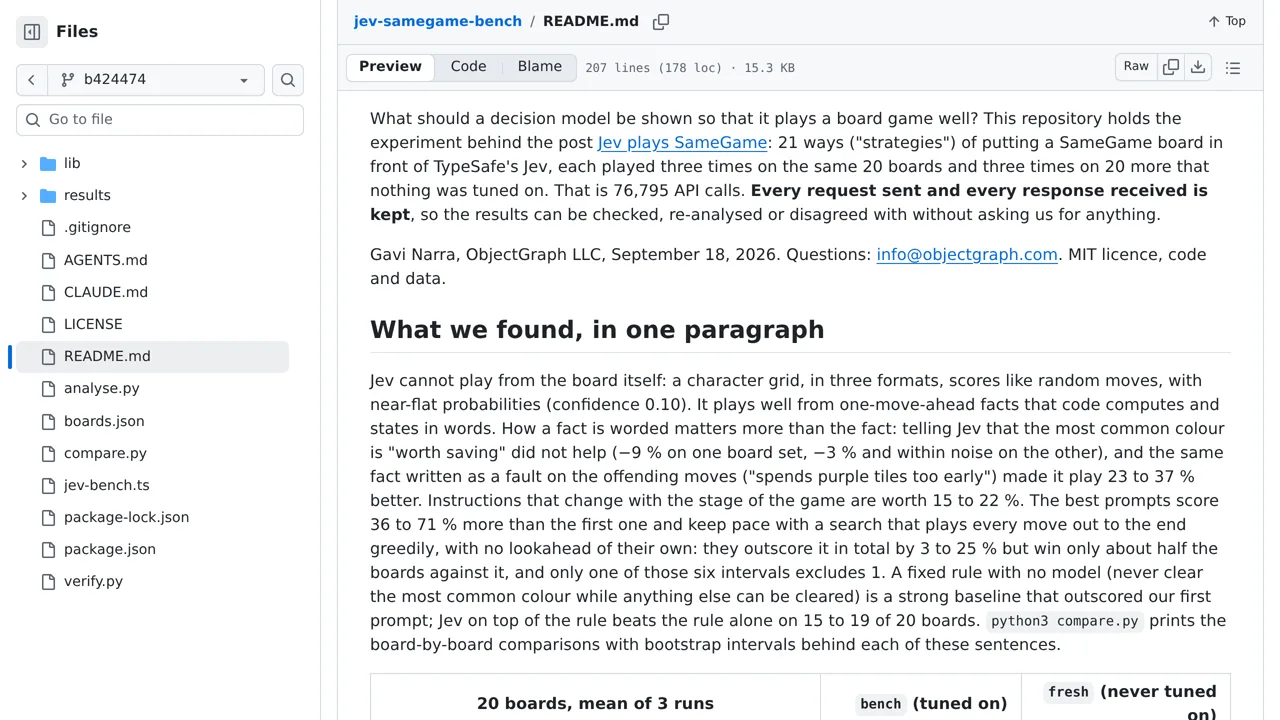
Published data show raw grids performing near random, while host-computed facts and prompt wording materially change results.
Benchmarks & research
Compare 21 ways of describing legal SameGame moves to Jev, with every raw request and response preserved.
Screenshot unavailable. Open the experiment ↗
Published data show raw grids performing near random, while host-computed facts and prompt wording materially change results.
Before writing any code, sketch simple rules for your board game. Decide how to describe bad choices in plain words, like warning that spending key tiles too early wastes them. Your developer can then calculate valid moves in normal software and pass those descriptions to the AI instead of showing it a visual grid.
Your developer can borrow the instructions from this experiment to guide the model during play. The benchmark shows that the AI makes near-random guesses when looking at raw board layouts, so your software must compute move consequences first to help it choose wisely.