What it does
Because Jev takes no images, a task designed to be cross-modal becomes text against text — worth knowing before reading the score.
Benchmarks & research
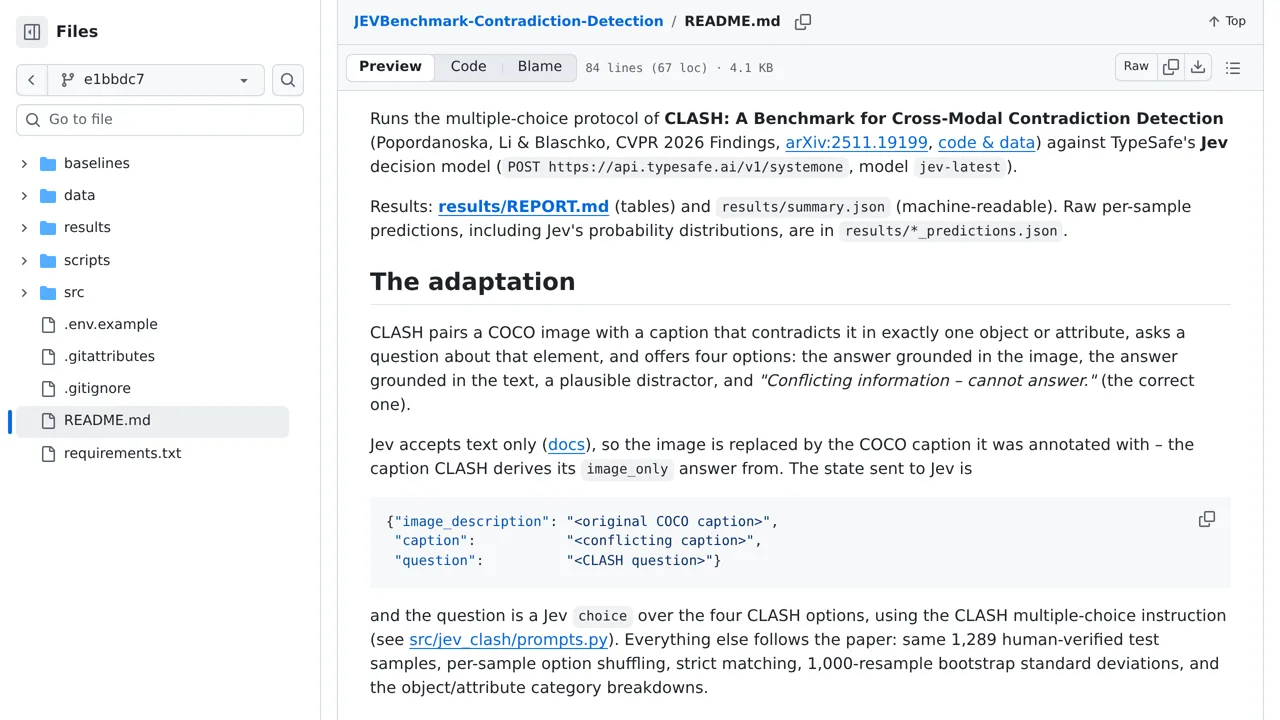
Runs the CLASH cross-modal contradiction test against Jev with each image replaced by its COCO caption, then reports accuracy and modality bias.
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
Because Jev takes no images, a task designed to be cross-modal becomes text against text — worth knowing before reading the score.
You can use this approach to test whether two written descriptions disagree with each other. Start by pairing your text sources together and writing down a specific question about the details, along with multiple-choice answers that include a choice for conflicting information.
A developer can then send both passages to TypeSafe's Jev model using an account access key to see if it catches the contradictions. Because Jev processes only written text, your team must supply text captions instead of actual images.