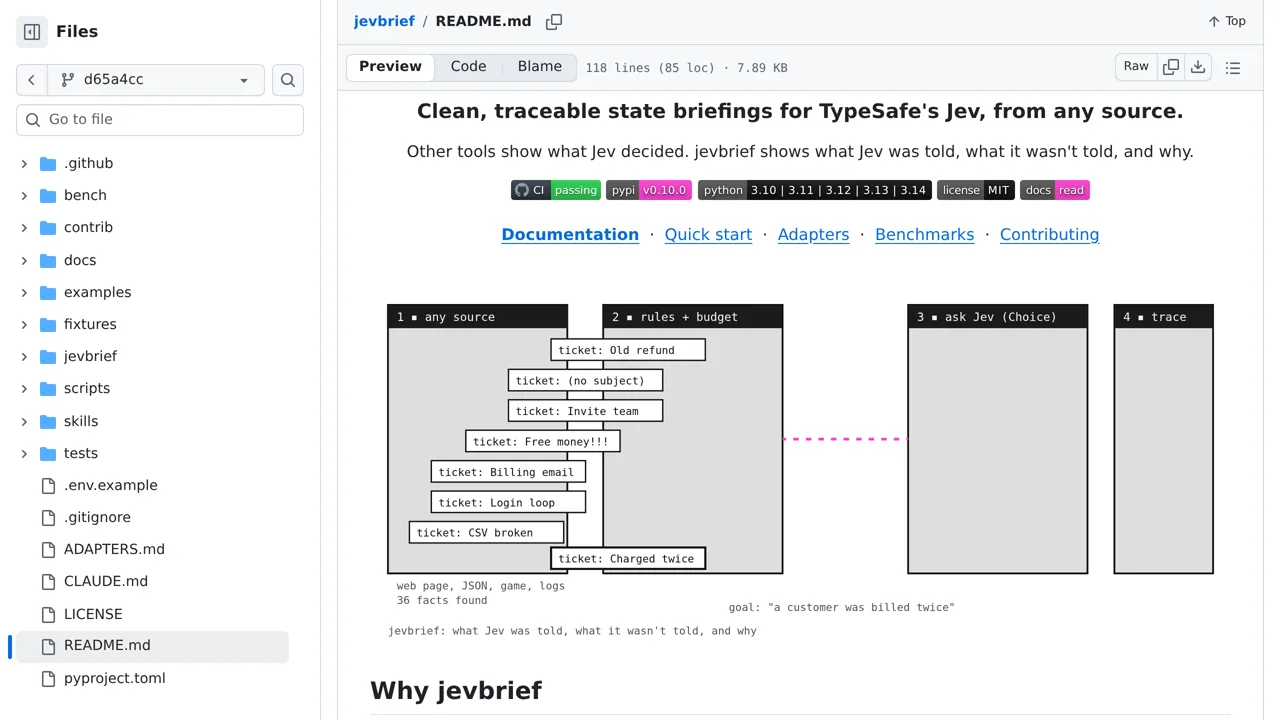
jevbrief fixes the least glamorous part of a Jev integration: what the model actually gets to read. Adapters for CI runs, pull requests, OpenTelemetry exports, and other noisy sources cut state down to what matters, and every dropped line gets a reason.
The project's own benchmark makes the case with a failure story: given a deploy incident whose single config error had scrolled out of the most recent 254 log lines, the raw-logs arm missed it every time while the briefed arm went 18 for 18. Median input fell from 29,678 tokens to 1,070. The data is synthetic and the README says so; inspect mode costs nothing.
How you can use it
To give your AI assistant fewer choices, have a developer try this project's way of sorting its tools. Tools are the actions it can take. Start with a task and keep only tools that fit that goal. This sorting happens on your computer without paying an AI service.