What it does
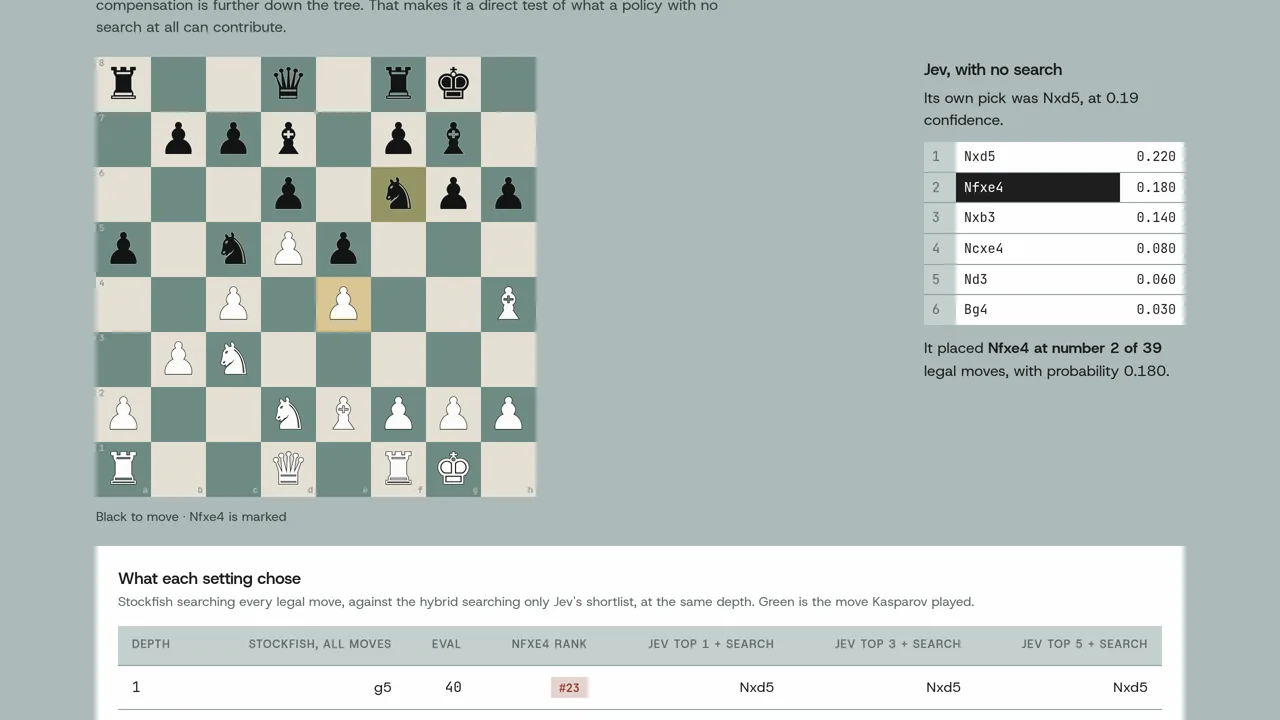
The lab reports 103 model decisions from 104 hand-picked positions. Its games and search comparisons illustrate the limits of Jev's move ranking; ten games per matchup cannot establish a chess rating.
Benchmarks & research
A chess dashboard compares Jev's move choices with Stockfish and human-style chess networks.
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
The lab reports 103 model decisions from 104 hand-picked positions. Its games and search comparisons illustrate the limits of Jev's move ranking; ten games per matchup cannot establish a chess rating.
Your developer can borrow this testing method to see how well an AI plays a game. They can feed the AI specific board situations along with a list of allowed moves. The AI picks a move, and a traditional game program grades that choice.
The published list of test positions offers a starting point for chess apps. To save time, the code automatically plays forced moves without asking the AI. These tests show how the AI handles specific tactics, but do not prove its overall skill.