What it does
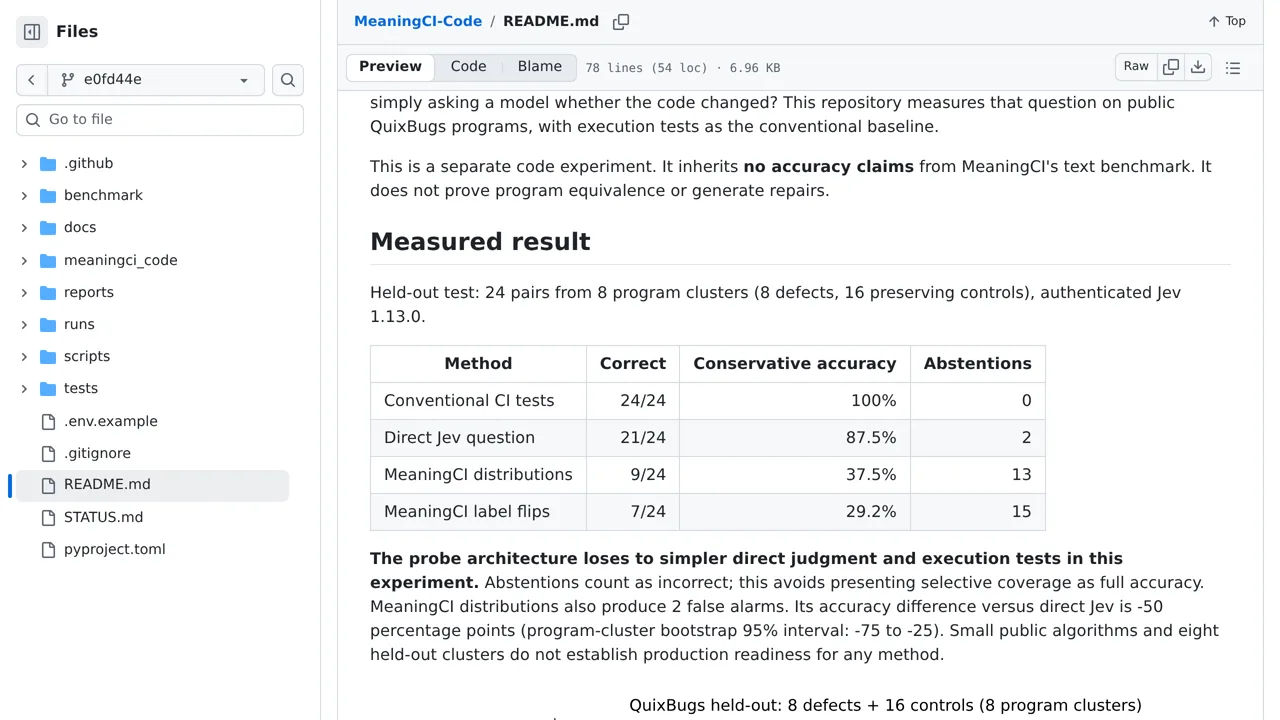
The author tests eight small public programs, counting uncertain answers as wrong. These results do not establish how well any method would work on production code.
Benchmarks & research
A study of bugs in small programs finds that comparing Jev's answer probabilities works worse than direct questions and execution tests.
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
The author tests eight small public programs, counting uncertain answers as wrong. These results do not establish how well any method would work on production code.
Read the saved results before using AI to check changes in your app's code. This study asks the same questions about what the old and new code will do, then compares the answers with tests that run the code. Keep uncertain answers visible rather than counting them as successful checks.
Keep tests that run the code as the foundation; use model judgment to flag changes for review, not to approve a release. These results cover small public programs, not your product. Check permission before copying the test tool: no license for it is declared. Its time limit does not make unknown code safe to run.