What it does
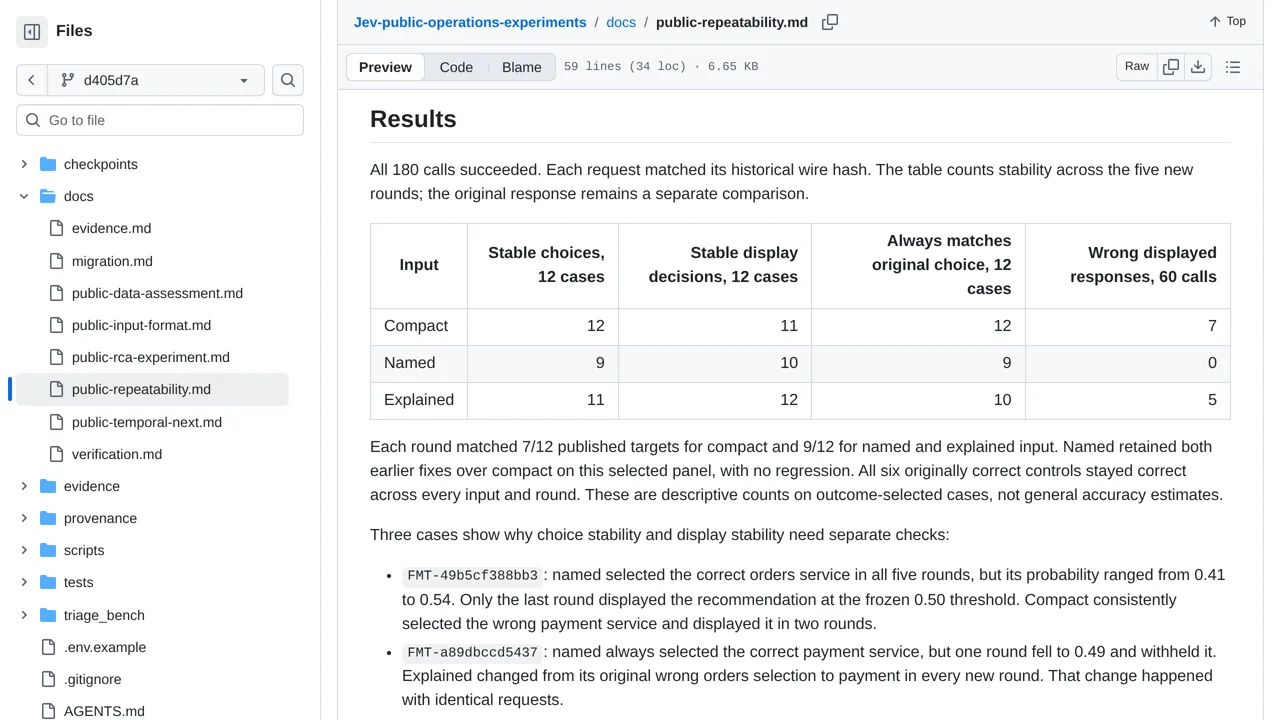
The controlled fault studies keep requests, responses and review thresholds visible. A 180-call replay failed its repeatability gate: identical inputs did not keep every choice or display decision stable.
Benchmarks & research
Explore how Jev picks a faulty service from public telemetry, and how changing the input changes its answer.
Only you can see your notes.
Saved in this browser only.
Screenshot unavailable. Open the experiment ↗
The controlled fault studies keep requests, responses and review thresholds visible. A 180-call replay failed its repeatability gate: identical inputs did not keep every choice or display decision stable.
For research on incident diagnosis, borrow the separation between evidence, model answers and known causes. Follow the instructions for the read-only app and restore the public evidence bundles to inspect saved predictions. Browsing that app needs no service access key and makes no model calls.
Compare simple ranking methods alongside Jev, keep the cutoff for showing answers fixed, and check repeated answers before making recommendations. These are controlled faults with known start times, not proof of production readiness. The replay failed its research gate. New model calls need a separate test plan and your own access key.



