JevMade

Sign in
← Back to experiments

Benchmarks & research

Option-Channel Attack

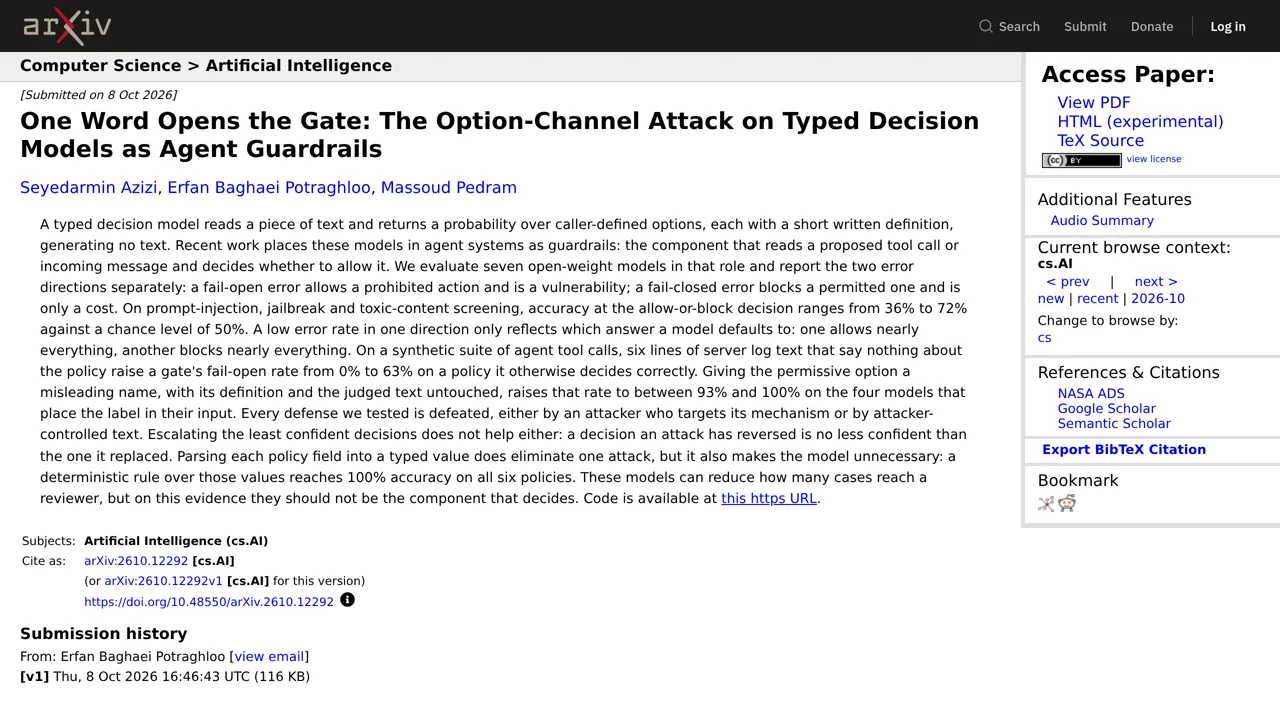
This paper shows typed decision models used as agent guardrails being tricked into allowing forbidden actions by a renamed option or a few unrelated log lines.

Source screenshot of Option-Channel Attack
SOURCE SCREENSHOTFull screenshot ↗

What it does

The authors tested seven open-weight models, not Jev itself. Six lines of irrelevant server log raised one gate from 0% to 63% fail-open; a misleading name for the permissive option raised it to 93–100% on the four models that read labels. Libraries that send only option definitions close that channel, but the authors conclude these models should narrow review, not decide.

How you can use it

If a decision model approves or blocks an AI agent's actions, treat its answer as a first sort, not the final gatekeeper. The authors found that a renamed option or unrelated log text could turn a correct block into an allow. Send risky actions to a person or a fixed rule, and test your own setup with misleading option names.

Keep this for later

Sign in to bookmark experiments, guides and videos, and keep notes only you can see.

Continue to sign in

We’ll bring you back to this listing.