JevMade

Sign in
← Back to experiments

Benchmarks & research

Piccolo

Piccolo is AgentScope's family of open 4B, 9B and 27B decision models that weigh candidate options in context and return probabilities, aimed at reviewing an agent's tool calls, choosing what context to keep and filtering data.

Bookmark: Piccolo Keep this in your collection.
Leave a noteWhat would you try with this? : Piccolo

Only you can see your notes.

Source screenshot of Piccolo
SOURCE SCREENSHOTFull screenshot ↗

What it does

AgentScope reports 92.21% on JevBench Public for Piccolo-27B, plus 84.41% on HarnessJevBench Hard and 82.60% on DataJevBench, two benchmarks it built itself. Inside QwenPaw, a local Piccolo can approve harmless tool calls, flag destructive ones and help compact long conversations. The local runtime serves one model at a time, and an ordinary chat endpoint will not do: the decision path needs Piccolo's own /v1/systemone endpoint.

How you can use it

You can have a developer use Piccolo to check an AI assistant's planned computer actions before they run. In AgentScope's QwenPaw demo, Piccolo approved two harmless file reads and flagged an attempt to overwrite a file as destructive.

Your developer runs Piccolo on your own machine, for example through QwenPaw's local runtime, which serves one model at a time. An ordinary chat service cannot ask it these questions. Piccolo can still misjudge an action, so keep a person in charge of approving risky ones.
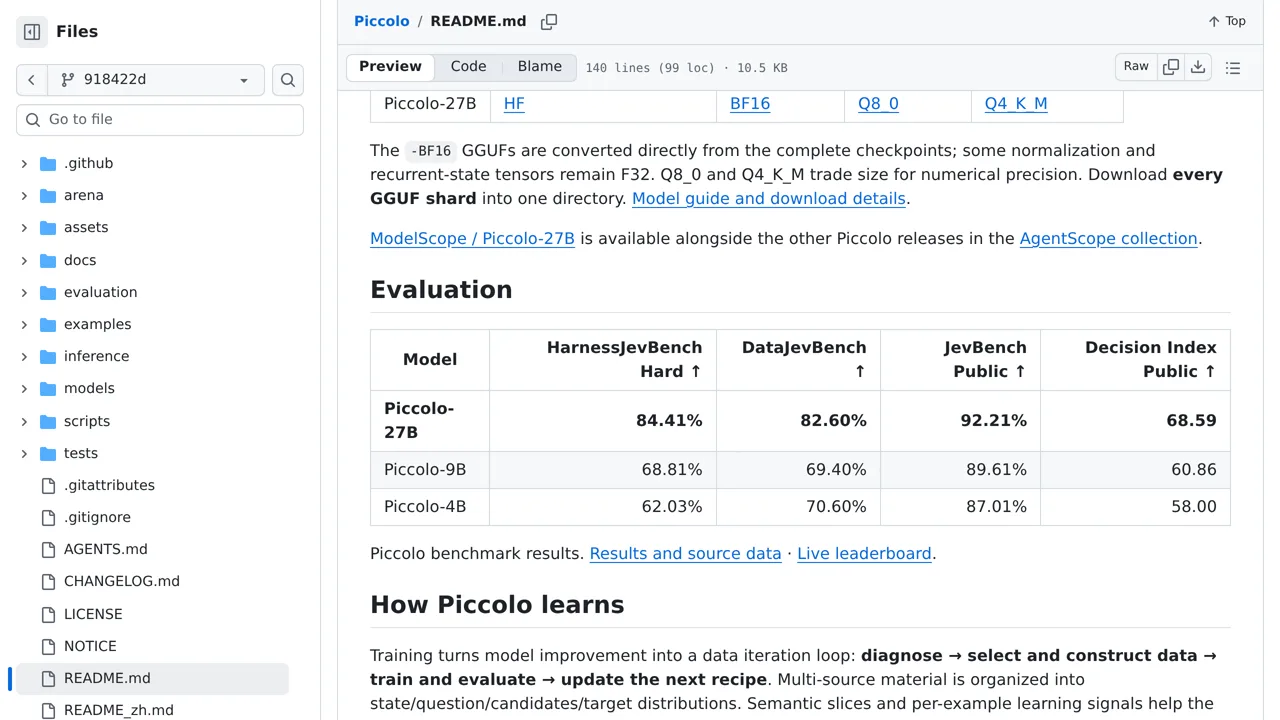
Maker-reported (not independently measured by JevMade)

README, Piccolo-27B / 9B / 4B: HarnessJevBench Hard 84.41% / 68.81% / 62.03%; DataJevBench 82.60% / 69.40% / 70.60%; JevBench Public 92.21% / 89.61% / 87.01%; Decision Index Public 68.59 / 60.86 / 58.00. AgentScope's X post adds 77.75 on the multimodal Decision Index Public for 27B. · HarnessJevBench and DataJevBench are AgentScope's own purpose-built benchmarks. · 12 Hugging Face repositories under Apache-2.0, including BF16, Q8_0 and Q4_K_M GGUFs. · Training is a "recursive self-improvement" data loop: diagnose errors, select and synthesise data, train, evaluate and update the recipe, with research agents testing changes within human-defined goals and budgets. · QwenPaw demo: Piccolo approves two Bash reads and flags an attempted overwrite as destructive. · The arena, derived from JevArena, shows archived game replays including Mario, Snake, 2048, Sokoban, Tetris, Hex, Othello and Zenless Zone Zero. The README notes GIF playback speed is not inference latency.

Primitives
Not stated
Platform
Hugging Face / GGUF (QwenPaw local runtime)
Added
Project created
GitHub stars
28 (snapshot, not live)

Keep this for later

Sign in to bookmark experiments, guides and videos, and keep notes only you can see.

Continue to sign in

We’ll bring you back to this listing.