JevMade

Sign in
← Back to experiments

Benchmarks & research

S1MB — System One Mosaic Benchmark

Compare Jev and open decision models on the same Choice, Noul and Score tasks, then browse a public leaderboard of the results.

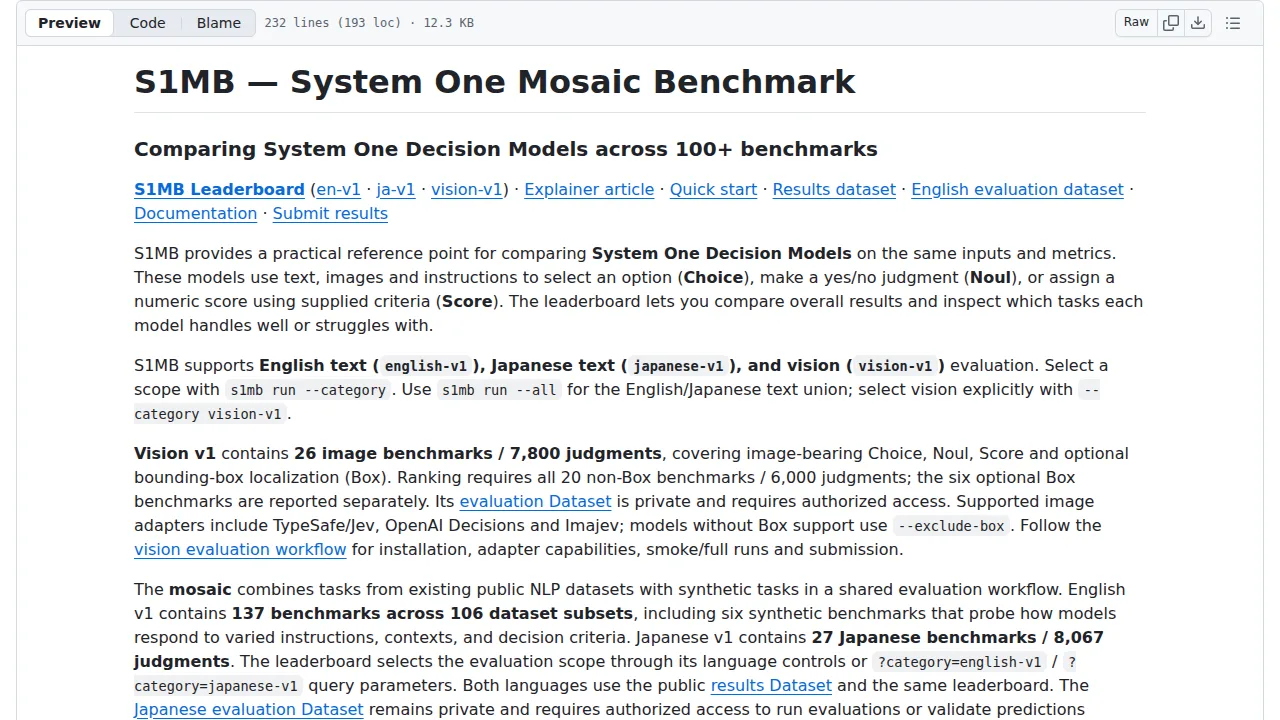
Source screenshot of S1MB — System One Mosaic Benchmark
SOURCE SCREENSHOTFull screenshot ↗

What it does

The benchmark mixes tasks adapted from public NLP datasets with synthetic ones, and records dataset revisions and inference settings with each result. The Japanese and vision evaluation datasets are private and need authorized access to run.

How you can use it

Clone the repository and install the Python evaluator with uv, then run a smoke test with the dummy adapter to check the pipeline works.

To evaluate a real model, pick an adapter such as TypeSafe/Jev, supply the needed API key or model weights, and run the full benchmark scope.

Open the Hugging Face leaderboard to compare published models, or submit your own validated results as a dataset pull request.
Maker-reported (not independently measured by JevMade)

The maker reports English v1 covers 137 benchmarks across 106 dataset subsets. · The maker reports Japanese v1 covers 27 benchmarks and 8,067 judgments. · The maker reports Vision v1 covers 26 image benchmarks and 7,800 judgments. · The submission says Jev 1.13 leads the published 23-model snapshot.

Primitives
choice, noul, score
Platform
Python
Added
Project created
GitHub stars
10 (snapshot, not live)

Keep this for later

Sign in to bookmark experiments, guides and videos, and keep notes only you can see.

Continue to sign in

We’ll bring you back to this listing.