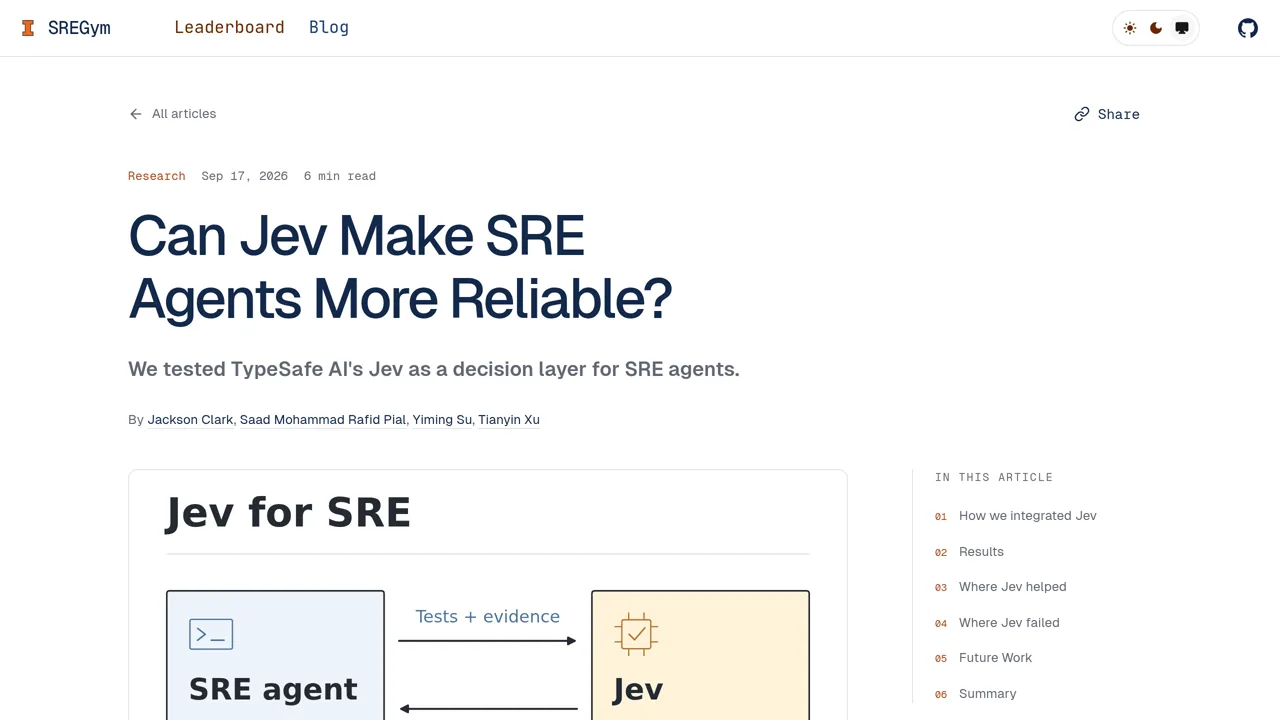
What it does
The honest parts make this one worth citing: two problems got worse with Jev in the loop, five attempts per problem is a small sample, and nobody measured whether diagnosis got faster. The gate itself is strict — every question needs 0.70 probability, and a rejection sends the agent hunting for new evidence rather than letting it reword the same claim.
Maker-reported (not independently measured by JevMade): Author-reported: Jev-assisted agent passed 24 of 50 attempts versus 20 of 50 baseline across ten SREGym-Lite problems, five attempts each
- Primitives
- choice, score, noul
- Platform
- Python
- Added
- Project created
Source checked 2026-09-29 — opened the primary source directly.