JevMade

Sign in
← Back to experiments

Benchmarks & research

Tazo

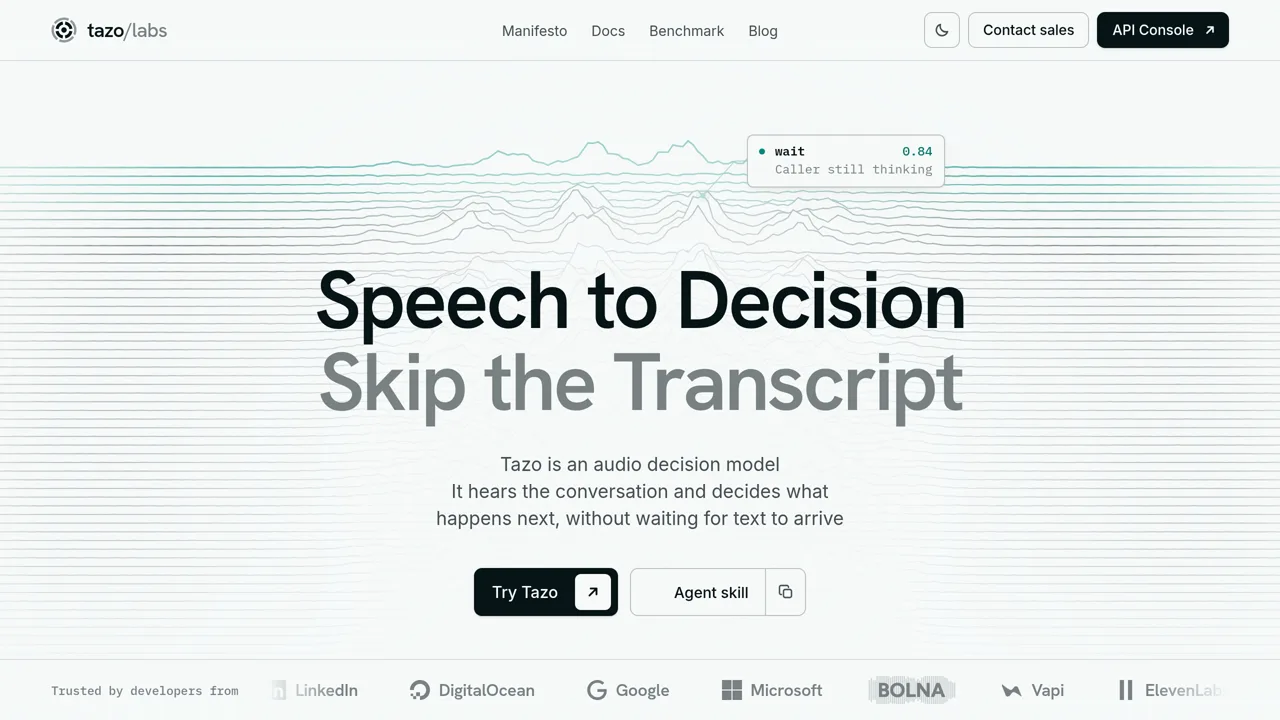
Tazo listens to raw call audio and picks from options you supply, such as respond or wait, with a probability for each, so a voice agent can make turn-taking and escalation calls without waiting for a transcript.

Bookmark: Tazo Keep this in your collection.
Leave a noteWhat would you try with this? : Tazo

Only you can see your notes.

Source screenshot of Tazo
SOURCE SCREENSHOTFull screenshot ↗

What it does

Tazo Labs runs it as a hosted service beside an existing speech-to-text, LLM and text-to-speech stack, for uploaded files or live 16 kHz audio. Co-founder Naman Jain's launch post claims 70.9% against 46.4% for speech-to-text plus Jev on real production calls, second place on the MMAU audio benchmark and under 200 ms of model latency. There is no published method behind those numbers yet: the site's benchmark page returned 404 on 6 Nov 2026.

How you can use it

You can test Tazo in a phone assistant to make quick conversation decisions without waiting for full speech transcription. Your developer connects your phone stream to Tazo's service using an access key. You supply the audio alongside a clear list of choices, such as whether to reply immediately or keep waiting.

Tazo hears tone and pauses directly from the raw audio to score your choices. Keep in mind that the current service only answers one specific question per request. Its high accuracy claims also come strictly from the maker rather than verified public tests.
Maker-reported (not independently measured by JevMade)

Naman Jain's launch post (2 Nov 2026): 70.9% vs 46.4% for STT + Jev on real production calls; #2 on the MMAU audio benchmark; <200 ms model latency; "First decision model tuned to run on streaming voice calls". No method published; tazolabs.com/benchmark returned 404 on 6 Nov 2026. · Pricing: $0.20 per hour of audio processed, billed per second. · Input: one audio file up to 16 MB (POST /v1/decisions) or live PCM16 16 kHz mono over wss://api.tazolabs.com/v1/decisions/stream. Model tazo-large; current models support one question per request. · A "None of the above" option covers out-of-scope or unsure moments. Suggested decisions include respond vs wait, end of turn, backchannel vs barge-in, voicemail, escalation, language ID and starting a tool call early. · Calibration is Tazo Labs' own claim. Its blog contrasts Tazo with Jev (text only, so speech-to-text runs first) and mocomoco's AudioJev (short clips, scores not calibrated).

Primitives
choice
Platform
HTTP and WebSocket API
Added

Keep this for later

Sign in to bookmark experiments, guides and videos, and keep notes only you can see.

Continue to sign in

We’ll bring you back to this listing.