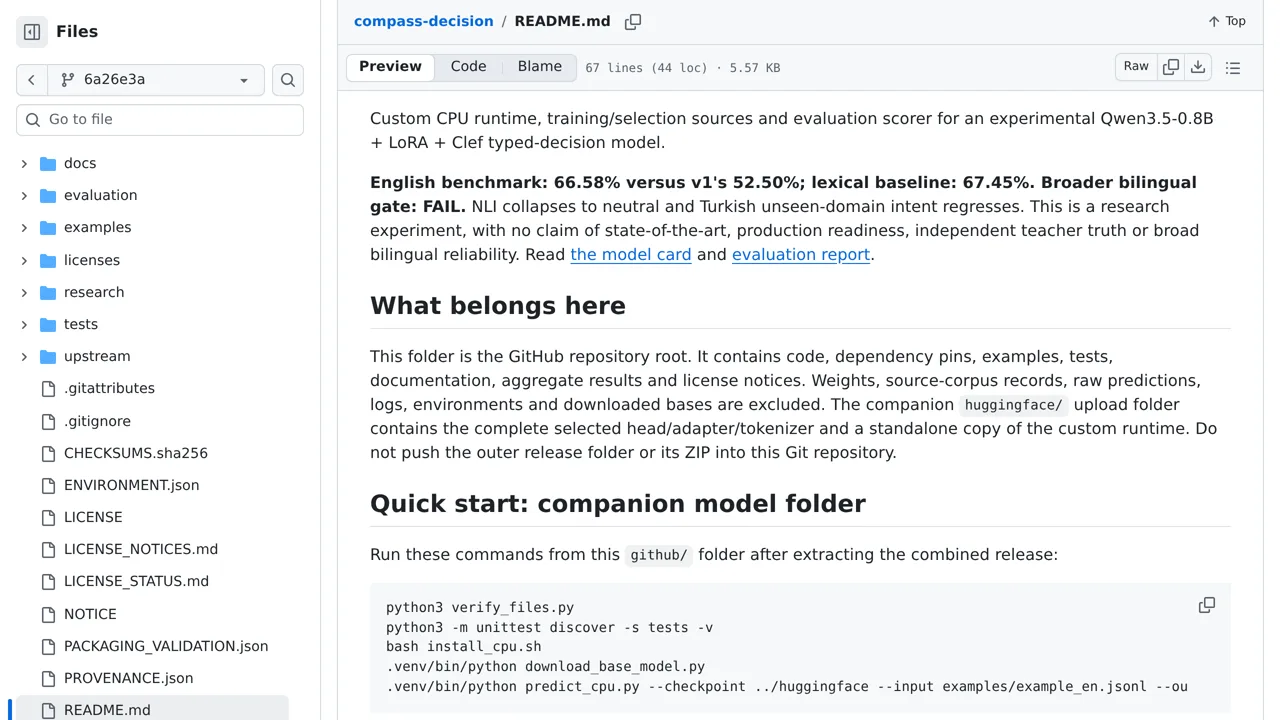
Compass fails its broader bilingual gate and scores below a lexical baseline on the English benchmark. This research experiment needs its custom Python runtime; standard Transformers, GGUF and Ollama loading are unsupported. Requests exceeding 2,048 tokens are rejected, not truncated.
How you can use it
The custom program runs on a plain processor, taking a situation and allowed answers and returning scores and decisions. An input that is too long is rejected rather than shortened. Keep its research status in mind: its English score trails word matching, and the broader bilingual checks fail.