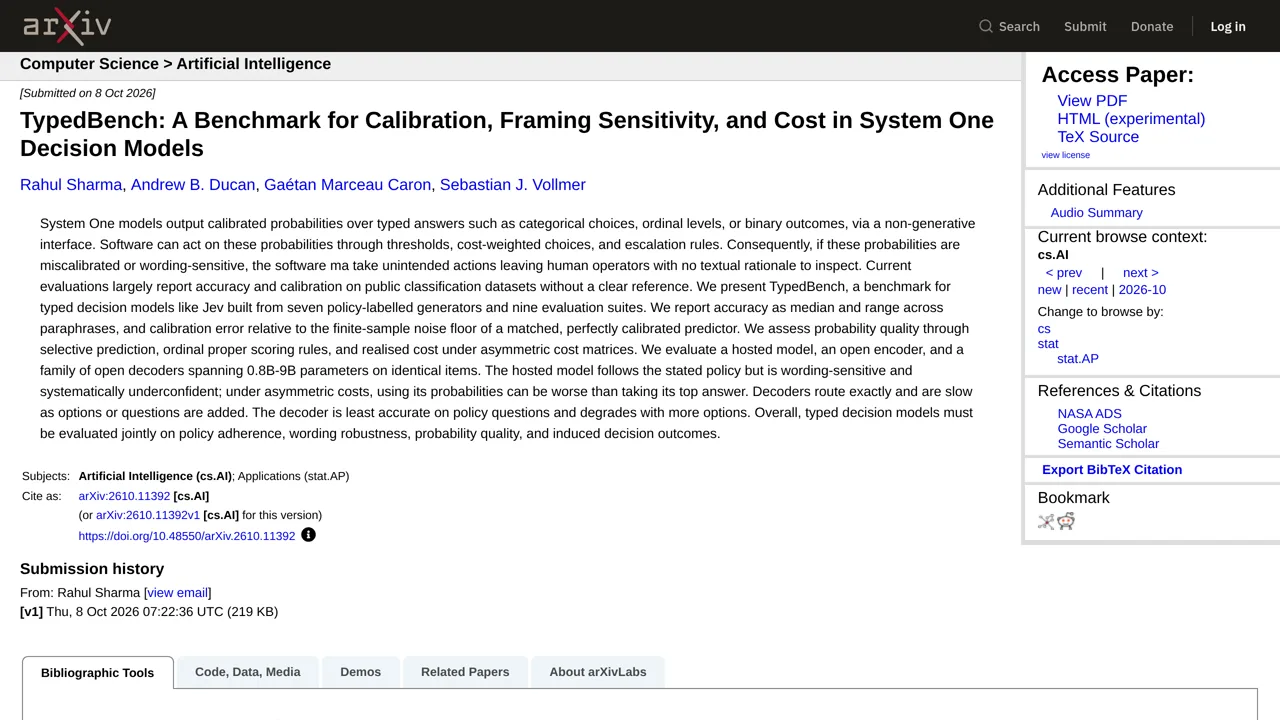
What it does
The 8 October 2026 preprint tests a hosted Jev-class model and open encoder/decoder checkpoints with fresh, rule-labelled questions, wording variations and unequal mistake costs. Its authors report wording sensitivity and underconfidence in the hosted model; using its probabilities under asymmetric costs can be worse than taking its top answer. Calibration is compared with a finite-sample noise floor, not assumed from accuracy. These results have not been independently reproduced; this is distinct from GraphDecide.