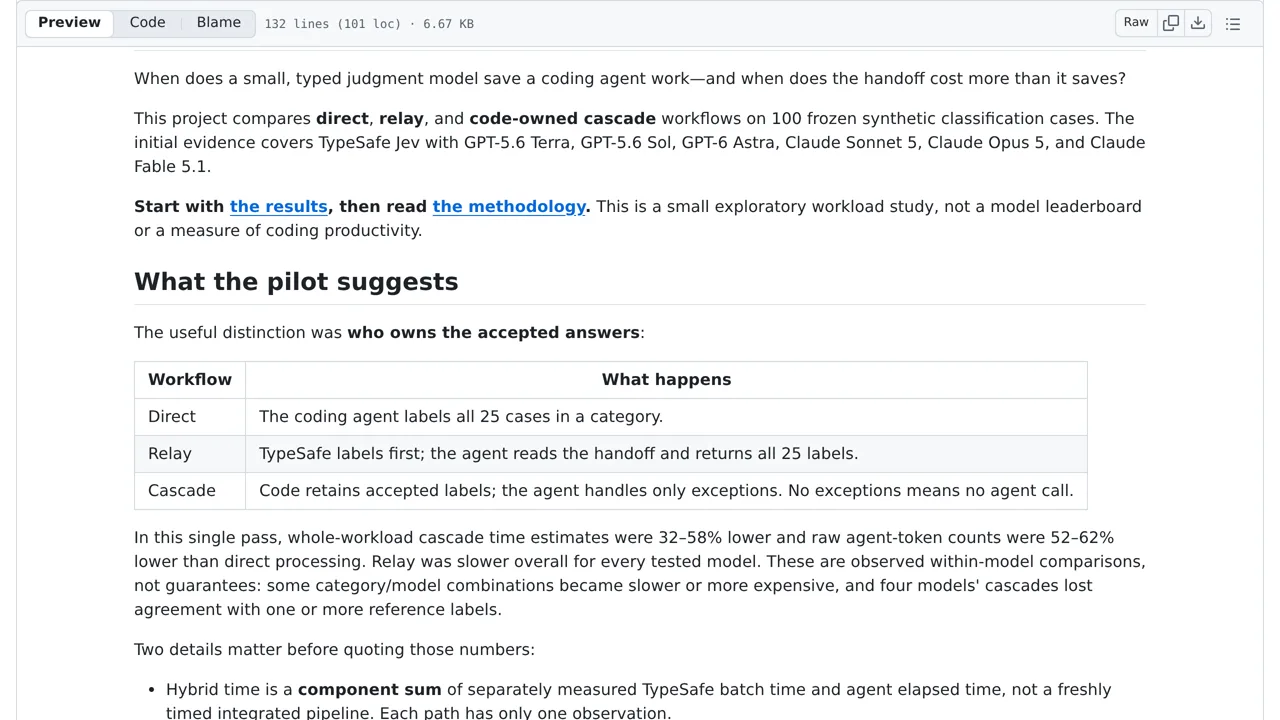
A 100-case synthetic study by Dmytro Nikolayev contrasts direct agent labeling, relay handoffs, and code-owned Jev cascades, preserving errors and no-call skips.
The runner evaluates a single pass using an in-sample threshold. Hybrid time sums separate components rather than measuring an integrated run, meaning some reported savings coincide with lost label quality. Agent-cost tables omit Jev charges and mix credit and USD units. The runner only reruns Jev, not the coding models.
How you can use it
Use a batch of messages with known categories to compare three approaches: an agent labels everything; Jev labels first and the agent repeats all labels; or code keeps accepted Jev labels and asks the agent only about uncertain cases. The last approach skips the agent when no cases need review.
Check wrong labels as well as time saved on fresh examples. This pilot uses one hundred synthetic cases and a cutoff chosen on those same cases. Its combined times add separately measured parts, and agent-cost tables exclude Jev and mix billing units. It does not measure general coding productivity.