What it does
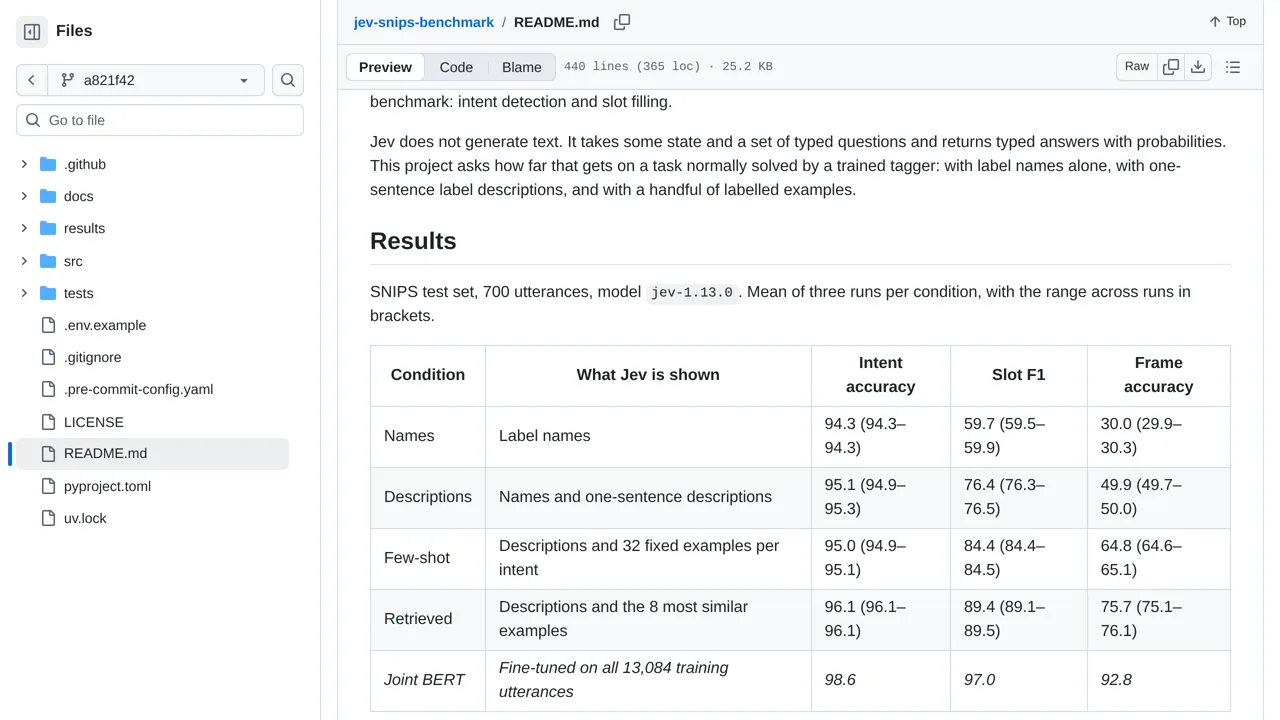
The study tests 700 SNIPS utterances without training Jev. Its best condition retrieves labelled training examples; some differ from test sentences by only one word.
Benchmarks & research
Compare how label descriptions and example selection change Jev's ability to recognize requests and identify the words that fill them.
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
The study tests 700 SNIPS utterances without training Jev. Its best condition retrieves labelled training examples; some differ from test sentences by only one word.
If your app sorts people's requests into groups, compare different ways to explain those groups. Try names alone, short descriptions and worked examples. This study also chooses examples similar to each new request. Check the answers against ones you already know, rather than assuming more examples will help.
Some test sentences almost match the supplied examples, which makes this study easier than unfamiliar requests. You can read its saved answers without running Jev. New runs send text to TypeSafe's outside AI service and spend credits.