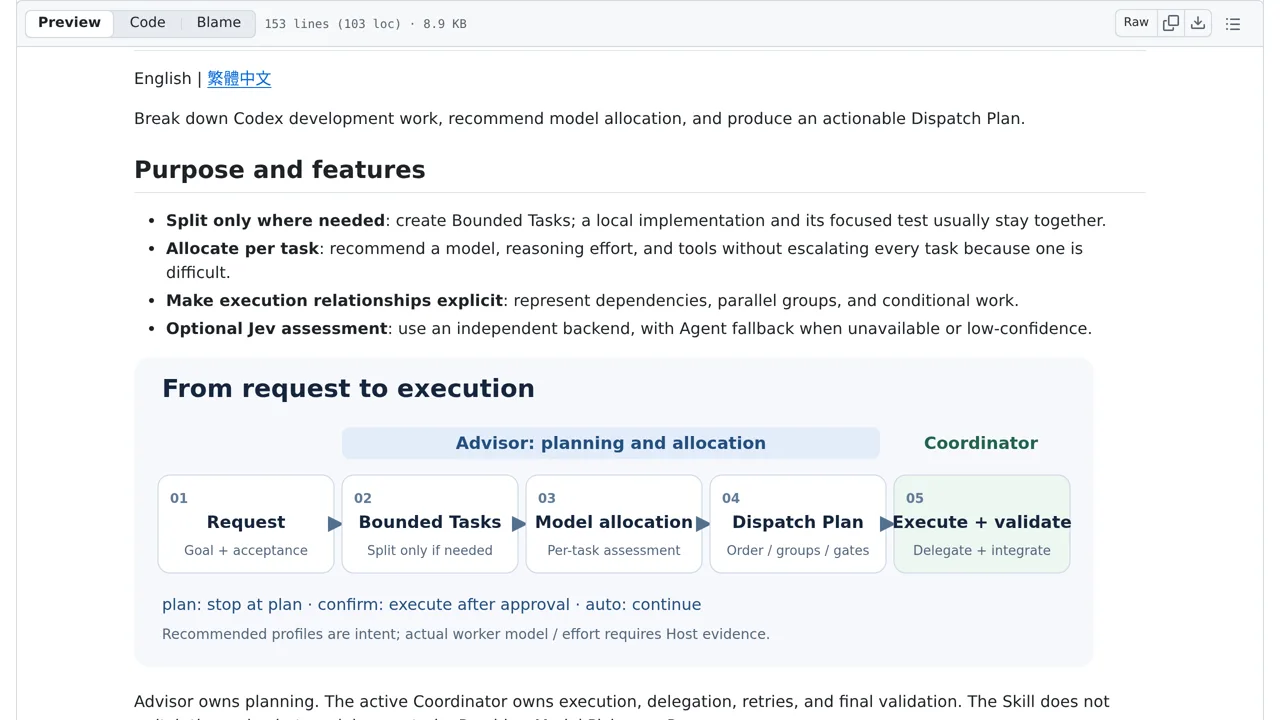
An optional backend can help choose the minimum required AI capability for a task. The main chat AI still controls the actual work and runs the code. The project author notes that a documented fifteen percent token reduction is only a manually assumed example, not a measured performance result.
How you can use it
In Codex, request a plan only for a feature such as a login API and its focused tests. Review the proposed pieces, dependencies and suggested models before allowing execution. Jev assessment is optional; only that configured path uses Jev, with the agent taking over when it is unavailable or uncertain.
Treat model allocation as advice, not a switch of your main chat model. The host's capabilities determine which workers can actually run, and local work uses the coordinator's current model. Keep execution authorization separate from planning; the documented fifteen-percent token reduction is an assumed example, not measured savings.