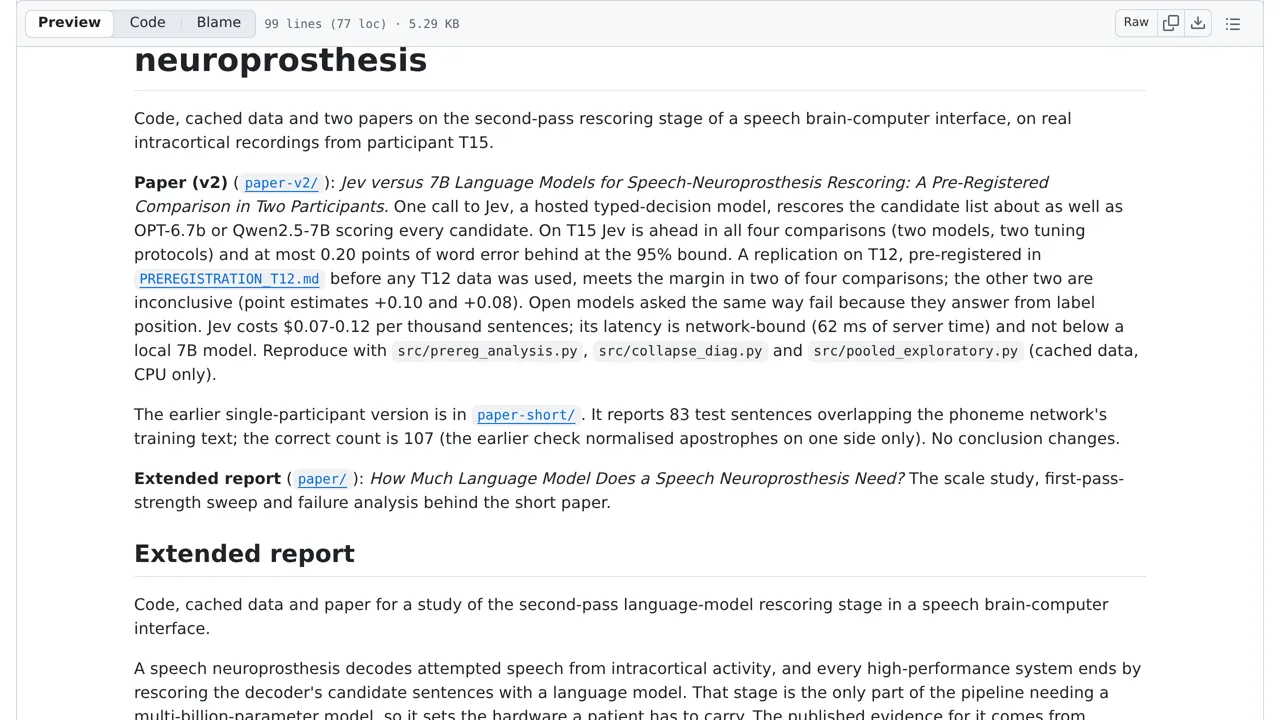
The repository's two-participant version differs from the single-participant preprint. Two of four preregistered comparisons on the second participant were inconclusive. Jev's latency was network-bound and not faster than a local 7B model.
How you can use it
Use the saved candidate lists and model scores to study how different models choose among possible transcriptions. The documented analysis scripts recompute tables on a CPU without rerunning the models or needing a graphics processor. Start with the two-participant paper's analysis instructions, keeping its results separate from the earlier single-participant paper.
This is a research reuse path, not a ready-to-use speech aid. Rebuilding candidate lists requires separate neural recordings and a large decoder setup, which are not included. Two of four preregistered comparisons on the second participant were inconclusive, and the reported Jev latency was not faster than a local 7B model.