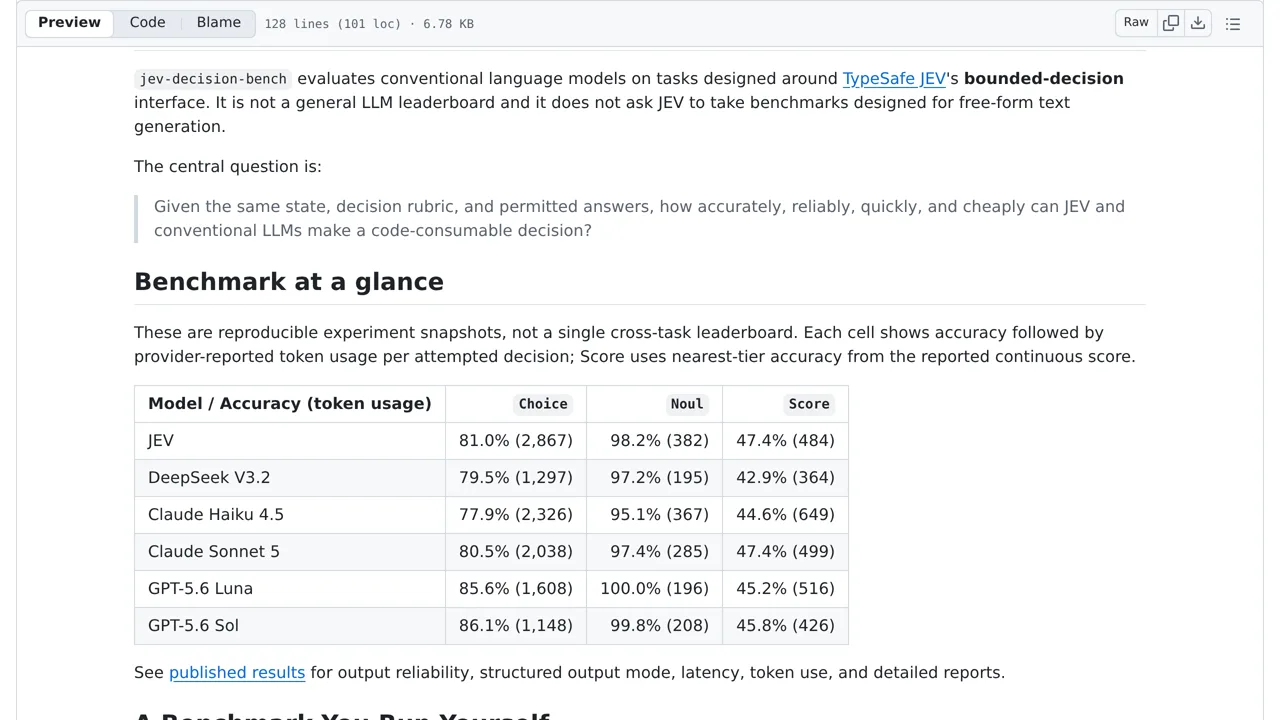
Tenkei's benchmark compares Jev and language models on choosing banking-request categories, judging hateful content and rating search relevance using fixed allowed answers.
No independent rerun or reuse license verified. Jev's inspected manifest requests jev-latest without a pinned revision. HateCheck's competing-model 100% score excludes invalid outputs; TREC measures rubric-tier accuracy. Token counts are not interchangeable.
How you can use it
Start with a banking request and a list of possible categories, or a search question and a passage with a known relevance rating. Give each model the same text, judging instructions and allowed answers. Compare its choice with the known answer while recording response time and invalid outputs.
Keep the three published tasks separate: banking categories, hateful-content judgments and search relevance are different tests. Search scores count the nearest relevance tier. Provider token counts are not interchangeable cost units, and an allowed answer is not necessarily correct. These snapshots do not establish a general model ranking.