JevMade

Sign in
← Back to experiments

Benchmarks & research

Jev vs frontier LLMs on typed decisions

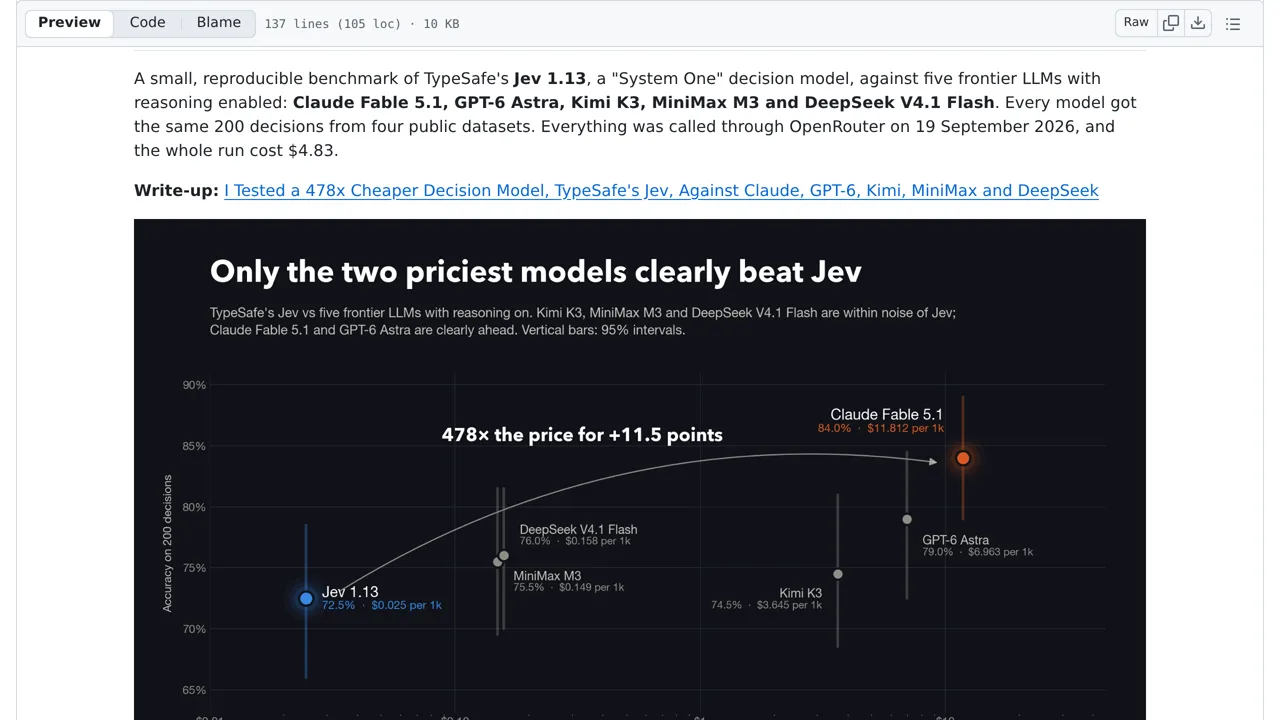
An author-run comparison evaluates Jev against five major language models on two hundred specific decisions across four different tasks.

Source screenshot of Jev vs frontier LLMs on typed decisions
SOURCE SCREENSHOTFull screenshot ↗

What it does

The test uses fifty examples per task, running once in a single region. The cascade threshold was chosen using the same test data, and users must download the original dataset text themselves. A later update adds comparisons with a local model called Laya.

How you can use it

Use the comparison design to test models on decisions such as sorting requests, rating reviews or answering yes-or-no questions. Give each model the same situations and allowed answers, then compare its predictions with known answers alongside time and cost. A confident response is not necessarily a correct one.

The test only uses fifty examples for each task, meaning small differences in scores might just be chance. You must download the original text data yourself, and the results only reflect one specific test run in a single region.

Keep this for later

Sign in to bookmark experiments, guides and videos, and keep notes only you can see.

Continue to sign in

We’ll bring you back to this listing.