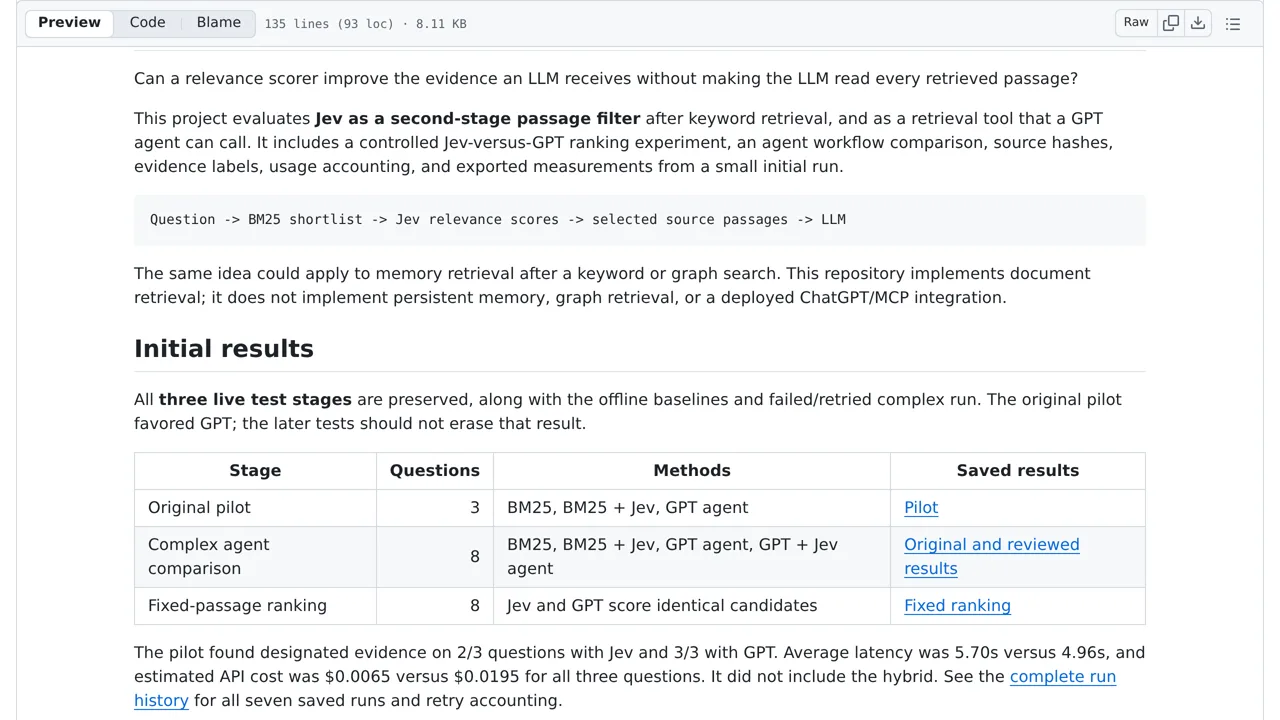
The author tested eight questions in one run, expanding evidence labels after seeing the results. An earlier pilot favored GPT. The combined workflow used different tools and budgets, improving coverage but taking longer. Cost savings are estimated from public provider rates, not actual spending. Finding a document does not guarantee the final answer is correct.
How you can use it
Start with a question and a collection of documents containing known supporting passages. A keyword search makes a shortlist; Jev judges which passages are relevant before they reach the answer-writing model. Compare the selected passages with the known evidence, not just the final answer's fluent wording.
The fixed test gives Jev and GPT the same fifty passages per question. The separate agent comparison lets systems search with unequal tools and budgets, so it answers a different question. Eight questions and revised evidence labels limit the findings; cost estimates omit failed attempts in the hybrid savings comparison.