What it does
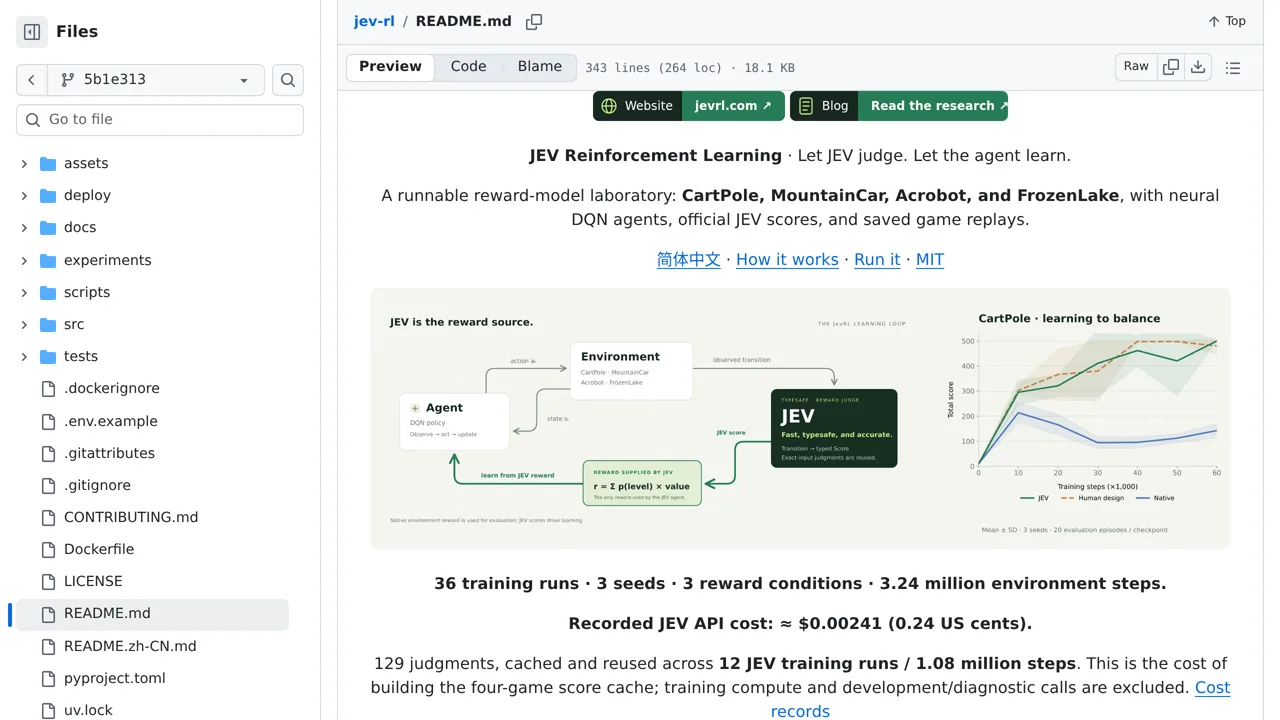
The judge layer runs over OpenRouter or TypeSafe direct, so the same reward signal works through either gateway, and a small web app replays the training runs.
Benchmarks & research
CartPole, MountainCar, Acrobot, and FrozenLake trained with reinforcement rewards that come from Jev's calibrated scores instead of a hand-written reward function.
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
The judge layer runs over OpenRouter or TypeSafe direct, so the same reward signal works through either gateway, and a small web app replays the training runs.
First, pick one of the four included games, such as balancing a pole or driving a car up a hill. Have a developer start the project so you can open its web screen. You can slide through saved attempts to watch a computer player slowly learn how to win.
You can teach a player using saved scores that come with the project without paying anything. If you want fresh scores for every move, your developer must add an access key that connects the software to an online scoring service.