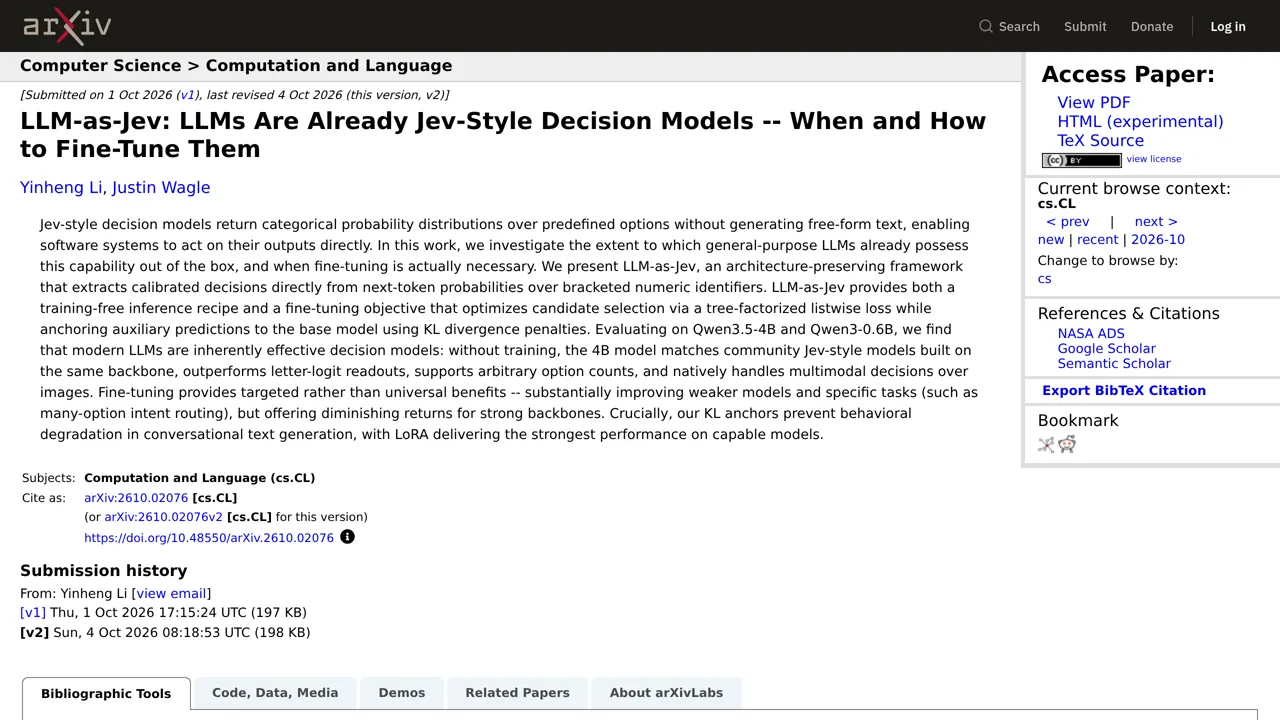
LLM-as-Jev argues that an ordinary chat model can already work as a Jev-style decision model: number the answers, then read how likely the model is to say each number.
Without any extra training, Qwen3.5-4B scored about as well as community decision models built on the same base on public JevBench items, and it could judge images too. Fine-tuning helped the smaller 0.6B model and long option lists most. It is a research paper by Yinheng Li and Justin Wagle, not a product.
How you can use it
If you already run a chat model on your own computer, this paper suggests a cheap experiment before building anything new: write the possible answers as a numbered list and let the model's own odds for each number pick the answer. The authors tested only two Qwen models, so check the results on your own questions.