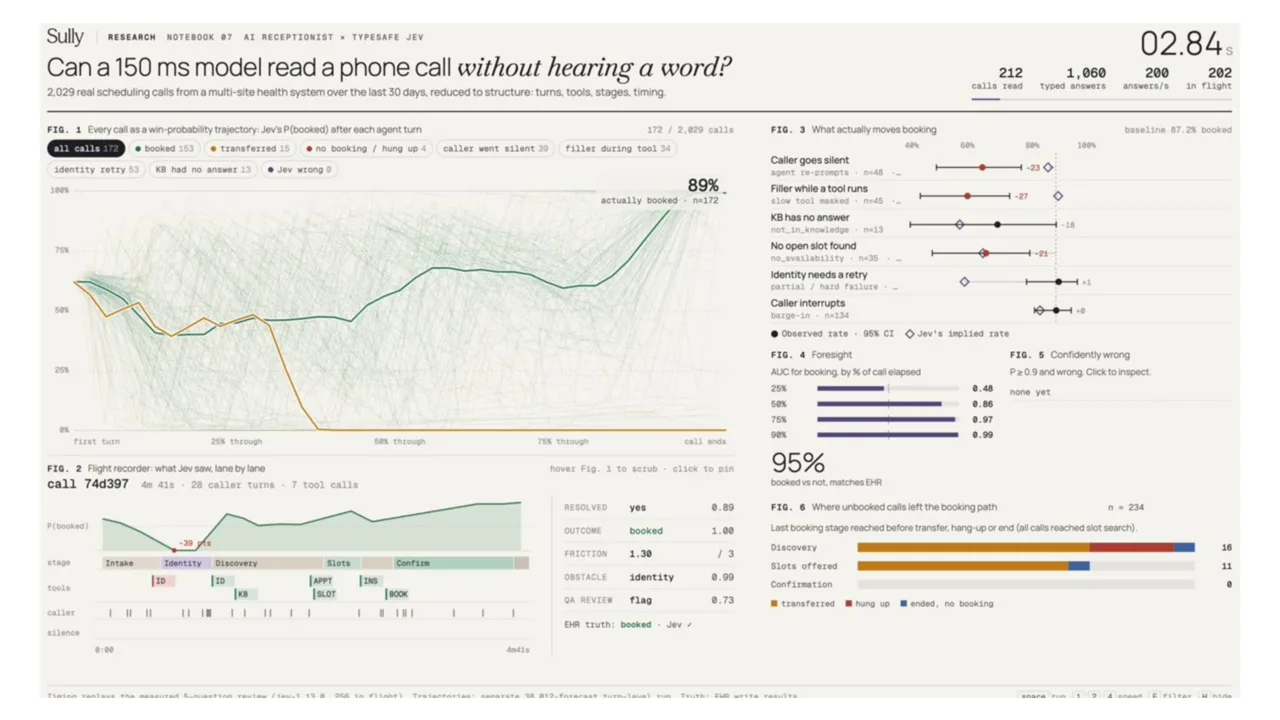
The maker reports testing 2,029 calls against booking records, but notes that Jev was too pessimistic about recoverable errors. The dashboard replays the study; its accuracy figures differ from the post, and neither the code nor the dataset is linked.
How you can use it
For your own booking service, ask a developer to compare the AI's predictions with completed bookings. Give it a record of the steps and timing, rather than call audio or everything people said. Check cases where an early mistake was fixed, because Sully found the model too pessimistic about them.
This is an idea to test, not a ready-made tool; the post shares no code or data. Keep personal details out of any records sent to an outside service. The reported results do not establish how well this would work for your project.