What it does
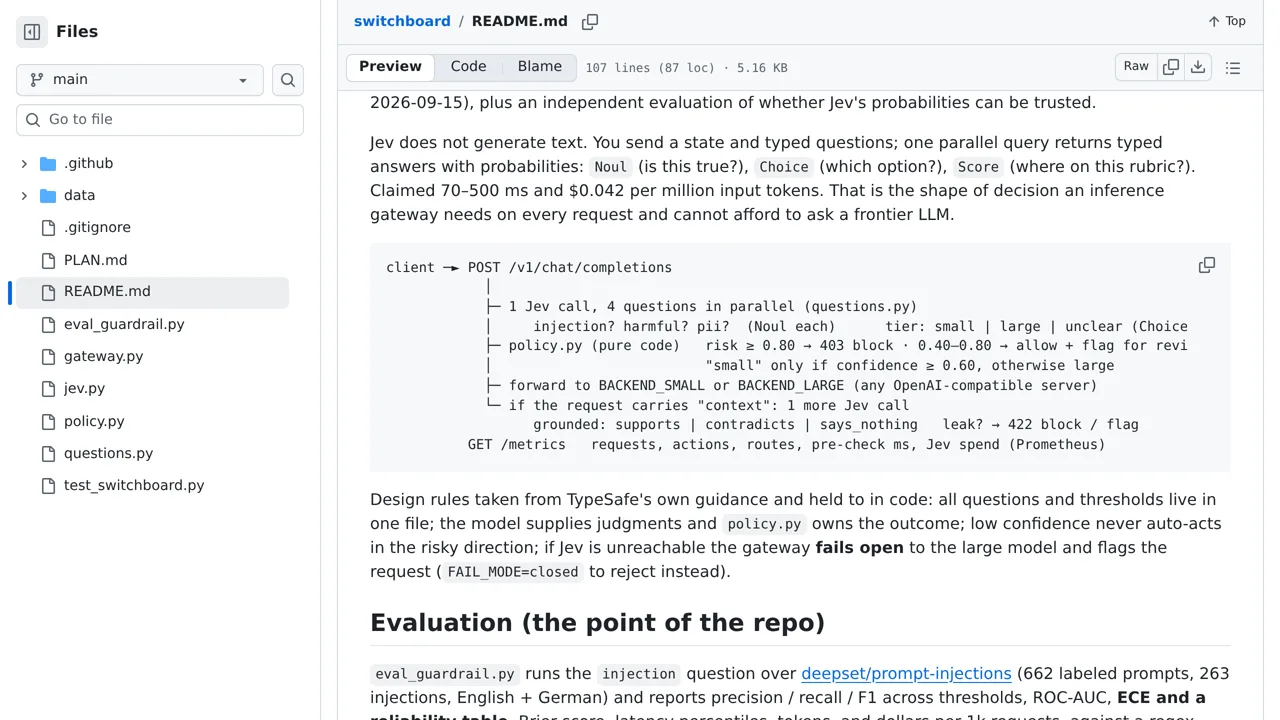
One Jev call evaluates prompt injection, harmful content, personal data, and model tier before deterministic policy code decides what happens next.
Agent tooling
A standard-library Python gateway that checks prompts for risk and routes safe requests to a suitable model.
Only you can see your notes.
Screenshot unavailable. Open the experiment ↗
One Jev call evaluates prompt injection, harmful content, personal data, and model tier before deterministic policy code decides what happens next.
Start by collecting real sample messages from your users. Group them into normal questions, harmful notes, and tricky attempts to break rules. Then decide what your system should do when risk is high, such as blocking the text or saving it for human review.
A developer can build this setup into your app to screen incoming prompts. It uses an access key to send each text to TypeSafe for evaluation scores. Automated scores can still make mistakes, and this setup only checks the newest user message rather than the full chat.